Müşteri Kaybı (Churn) Tahmini: Modelden Arama Listesine
7.043 telekom müşterisinin verisiyle bir kayıp tahmini kuruyor; doğruluk oranının neden yanıltıcı olduğunu ve modeli "bu hafta kimi arayacağız?" sorusunun cevabına nasıl çevireceğimizi gösteriyorum.
- Makine Öğrenmesi
- İstatistik
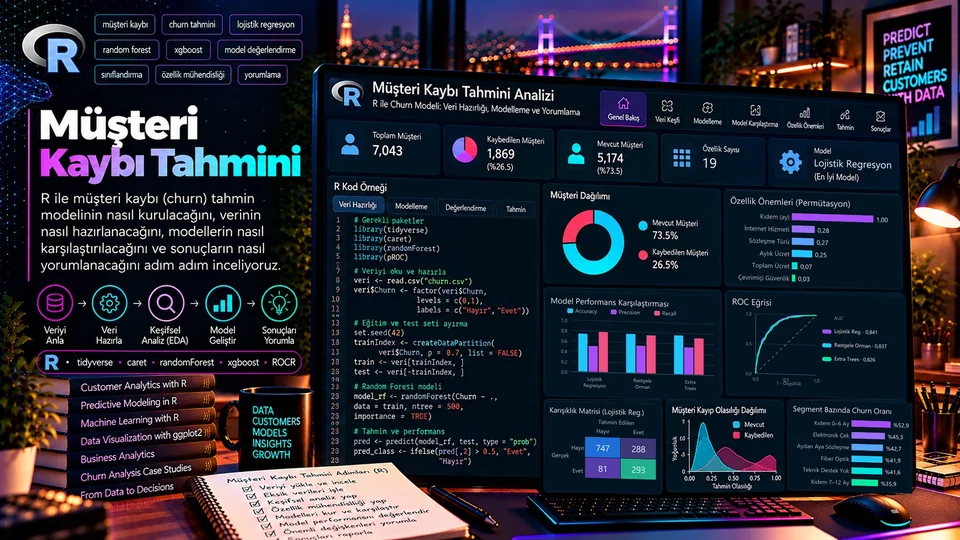
Churn modeli kurmak zor değil. Zor olan, modelin ürettiği olasılığı "bu hafta kimi arayacağız?" sorusunun cevabına çevirmek. Bu yazıda 7.043 telekom müşterisinin verisiyle baştan sona bir kayıp tahmini kuruyorum — ve modelin doğruluk oranının neden yanıltıcı bir başarı ölçüsü olduğunu sayılarla gösteriyorum.
Veri, IBM'in yayımladığı ve churn çalışmalarında standart hâline gelmiş Telco Customer Churn seti: 21 sütun, müşteri başına tek satır, hedef değişken müşterinin ayrılıp ayrılmadığı.
“Bir churn modelinin değeri, kaç müşteriyi doğru sınıflandırdığında değil; sınırlı sayıda aramayla kaç kayıp müşteriye ulaşabildiğinde ortaya çıkar.”
1. Problem ve Taban Oran
Önce bilinmesi gereken tek sayı var: 7.043 müşterinin 1.869'u ayrılmış, yani kayıp oranı %26,5. Bu, bütün değerlendirmenin zeminini belirliyor.
7.043 müşteri
21 değişken, yinelenen müşteri kaydı yok.
Churn (evet/hayır)
1.869 ayrılmış, 5.174 kalmış.
%73,5
"Hiç kimse ayrılmaz" diyen modelin doğruluğu.
5.634 / 1.409
Tabakalı %80/%20; kayıp oranı iki sette de %26,5.
2. Kayıp Nerede Yoğunlaşıyor?
Model kurmadan önce veriye bakmak, modelin sonradan bulacağı şeyin çoğunu zaten gösteriyor. Dört kırılım yeterli.
Aydan aya sözleşmeli müşterilerin kayıp oranı, iki yıllık sözleşmelilerin 15 katı. Tek bir değişkende bu kadar keskin bir ayrım nadirdir; modelin bu sütuna yüklenmesini şimdiden bekleyebiliriz.
| Kırılım | Grup | Müşteri | Kayıp oranı |
|---|---|---|---|
| İnternet hizmeti | Fiber optik | 3.096 | %41,9 |
| DSL | 2.421 | %19,0 | |
| Yok | 1.526 | %7,4 | |
| Ödeme yöntemi | Elektronik çek | 2.365 | %45,3 |
| Posta çeki | 1.612 | %19,1 | |
| Banka transferi (otomatik) | 1.544 | %16,7 | |
| Kredi kartı (otomatik) | 1.522 | %15,2 | |
| Teknik destek | Yok | 3.473 | %41,6 |
| Var | 2.044 | %15,2 | |
| İnternet hizmeti yok | 1.526 | %7,4 |
Üç tablo da aynı yöne işaret ediyor: bağlılığı zayıf, aylık ödemeli, destek almayan müşteri en riskli profil. Elektronik çekle ödeyenlerin kayıp oranının otomatik ödeme yapanların üç katı olması özellikle dikkat çekici — ödeme yöntemi burada bir niyet göstergesi gibi davranıyor.
İlk altı ay kritik: yeni müşterilerin yarısından fazlası gidiyor. Kıdem arttıkça risk tek yönlü düşüyor ve 49 ayı geçenlerde %9,5'e iniyor. Bu, elde tutma bütçesinin nereye gitmesi gerektiğini tek başına söylüyor.
3. "Eksik" Veri Gerçekten Eksik mi?
TotalCharges sütununda 11 boş hücre var. Refleks, medyanla doldurmak ya da o satırları atmak olur. Önce neden eksik olduklarına bakmak gerekiyor.
df["TotalCharges"] = pd.to_numeric(
    df["TotalCharges"].replace(r"^\s*$", pd.NA, regex=True),
    errors="coerce")

df.loc[df["TotalCharges"].isna(), "tenure"].unique()
# array([0])  -> hepsinin kidemi 0 ay
On bir müşterinin tamamının kıdemi sıfır. Yani bu insanlar daha ilk faturalarını almamış yeni abonelikler; toplam ücretleri eksik değil, henüz yok. Medyanla doldurmak bu müşterilere var olmayan bir geçmiş yazmak olurdu.
tenure = 0) tamamen açıklanıyor; doğru hamle ya sıfır yazmak ya da "yeni müşteri" bilgisini modele ayrı bir değişken olarak vermek. 11 satır 7.043'ün içinde kaybolur, ama aynı desen büyük veride binlerce satır olsaydı karar ciddi biçimde önem kazanırdı.4. Üç Model, Tek Test Seti
Sayısal değişkenler standartlaştırılıyor, kategorikler one-hot kodlanıyor ve üç model aynı veri hattından geçiyor. Sınıf dengesizliği için class_weight="balanced" kullanıyorum: model azınlık sınıfını daha pahalı sayıyor.
onisle = ColumnTransformer([
    ("num", Pipeline([("i", SimpleImputer(strategy="median")),
                      ("s", StandardScaler())]), sayisal),
    ("cat", Pipeline([("i", SimpleImputer(strategy="most_frequent")),
                      ("o", OneHotEncoder(handle_unknown="ignore"))]), kategorik),
])

X_tr, X_te, y_tr, y_te = train_test_split(
    X, y, test_size=0.2, random_state=42, stratify=y)

for ad, model in modeller.items():
    p = Pipeline([("prep", onisle), ("model", model)]).fit(X_tr, y_tr)
olasilik = p.predict_proba(X_te)[:, 1]| Model | Doğruluk | Kesinlik | Duyarlılık | F1 | ROC-AUC | PR-AUC | Brier |
|---|---|---|---|---|---|---|---|
| Lojistik regresyon | 0,738 | 0,504 | 0,783 | 0,614 | 0,841 | 0,633 | 0,169 |
| Rastgele orman | 0,759 | 0,534 | 0,743 | 0,621 | 0,837 | 0,641 | 0,158 |
| Extra Trees | 0,757 | 0,532 | 0,709 | 0,608 | 0,826 | 0,626 | 0,161 |
| Taban oran | 0,735 | — | 0,000 | — | 0,500 | 0,265 | — |
Tablonun en çarpıcı satırı en alttaki. Lojistik regresyonun %73,8'lik doğruluğu, hiçbir şey yapmayan modelin %73,5'inden yalnızca 0,3 puan yüksek. Doğruluğa bakarak bu modeli değerlendiren biri "işe yaramıyor" sonucuna varırdı. Oysa ROC-AUC 0,841 ve duyarlılık 0,783 — model ayrılacak müşterilerin dörtte üçünden fazlasını yakalıyor.
class_weight="balanced" modeli kayıp müşterileri kaçırmamaya zorluyor; bunun bedeli de yanlış alarm. Model 581 müşteriye "ayrılacak" diyor, 293'ü gerçekten ayrılıyor. Doğruluk düşüyor çünkü 288 müşteri boşuna işaretleniyor — ama 374 kayıp müşterinin 293'ü yakalanıyor. Bu bir hata değil, bilinçli bir takas.5. Eşik Bir Varsayımdır
Yukarıdaki bütün metrikler tek bir karardan doğuyor: olasılık 0,5'i geçerse "ayrılacak". Bu eşik matematikten değil alışkanlıktan geliyor. Değiştirince model değişmiyor, yalnızca olasılığı karara çevirme biçimi değişiyor.
| Eşik | Doğruluk | Duyarlılık | Kesinlik | F1 | İşaretlenen müşteri |
|---|---|---|---|---|---|
| 0,3 | 0,653 | 0,928 | 0,429 | 0,587 | 809 |
| 0,4 | 0,701 | 0,866 | 0,466 | 0,606 | 695 |
| 0,5 | 0,738 | 0,783 | 0,504 | 0,614 | 581 |
| 0,6 | 0,762 | 0,706 | 0,540 | 0,612 | 489 |
| 0,7 | 0,789 | 0,602 | 0,603 | 0,602 | 373 |
Eşiği seçen şey istatistik değil, ekip kapasitesi ve maliyet. 1.409 müşterilik bir listede ayda 800 müşteriyi arayabilecek bir ekip varsa 0,3 eşiği kayıpların %92,8'ini kapsar. Ayda 400 aramalık kapasite varsa 0,7 eşiği daha gerçekçi; bu kez kayıpların %60,2'si yakalanır ama her iki aramadan biri isabetli olur.
6. Model Ne Söylüyor?
Lojistik regresyonun en güzel yanı okunabilir olması. Katsayıları odds oranına çevirince her değişkenin yönü ve büyüklüğü doğrudan görünüyor.
| Değişken | Katsayı | Odds oranı | Yorum |
|---|---|---|---|
| Fiber optik internet | +0,705 | 2,02 | Kayıp olasılığının bahis oranını iki katına çıkarıyor. |
| Aydan aya sözleşme | +0,663 | 1,94 | Keşifte gördüğümüz en güçlü ayrım burada da karşımızda. |
| Elektronik çek | +0,239 | 1,27 | Otomatik ödemeye göre belirgin biçimde riskli. |
| Teknik destek yok | +0,164 | 1,18 | Destek almamak riski artırıyor. |
| Kıdem (standartlaştırılmış) | −1,124 | 0,33 | En güçlü koruyucu etki: bir standart sapma kıdem, bahis oranını üçte bire indiriyor. |
| 2 yıllık sözleşme | −0,781 | 0,46 | Uzun sözleşme riski yarıdan fazla azaltıyor. |
Permütasyon önemi de aynı sıralamayı veriyor: tenure tek başına ROC-AUC'yi 0,152 puan düşürüyor; onu InternetService (0,043), Contract (0,040) ve MonthlyCharges (0,038) izliyor. Yani modelin bildiği her şeyin dörtte üçü dört değişkende toplanıyor.
MonthlyCharges'ın katsayısı negatif (odds oranı 0,52) — oysa tek başına bakıldığında pahalı paketlerde kayıp daha yüksek. Çelişki değil, koşullu etki: model zaten "fiber optik" değişkenini biliyor ve pahalı olmanın riskini oradan okuyor. Fiber olduğu bilindikten sonra, aylık ücretin yüksek olması daha kapsamlı ve daha bağlı bir müşteriye işaret ediyor. Çok değişkenli bir modelde katsayılar "diğerleri sabitken" okunur; tek değişkenli sezgiyle doğrudan karşılaştırılamaz.7. Modeli İş Değerine Çevirmek
Asıl soru şuydu: bu hafta kimi arayacağız? Cevabı doğruluk oranı değil, lift veriyor. Müşterileri risk puanına göre sıralayıp üstten belli bir yüzdeyi aldığımızda o dilimde gerçekte kaç kayıp olduğuna bakıyoruz.
| Dilim | Müşteri | Dilimdeki kayıp oranı | Yakalanan kayıp | Lift |
|---|---|---|---|---|
| İlk %10 | 140 | %75,7 | 106 / 374 (%28,3) | 2,85× |
| İlk %20 | 281 | %65,8 | 185 / 374 (%49,5) | 2,48× |
| İlk %30 | 422 | %57,6 | 243 / 374 (%65,0) | 2,17× |
| İlk %50 | 704 | %46,3 | 326 / 374 (%87,2) | 1,74× |
Bu tablo doğruluk tablosundan çok daha kullanışlı. En riskli %10'u aradığında her dört müşteriden üçü gerçekten ayrılacak olan müşteri. Rastgele arama yapsan bu oran %26,5 olurdu; model aramanın isabetini 2,85 katına çıkarıyor. Müşterilerin yarısını arayacak kapasiten varsa kayıpların %87'sine ulaşıyorsun.
- Puanla
- Sırala
- Kapasiteyle
Kes - Kontrol Grubuyla
Ölç
Dört adımın üçü teknik, biri değil. Puanlama ve sıralama modelin işi; listeyi nerede keseceğini ekibin haftalık kapasitesi belirliyor. Dördüncü adım ise tamamen tasarım meselesi: işaretlenen müşterilerin rastgele seçilmiş bir bölümüne hiç dokunmamak.
8. Sık Yapılan Hatalar
| Hata | Neden problem? | Daha iyi yaklaşım |
|---|---|---|
| Doğruluk oranını raporlamak | Taban oran %73,5; model hiçbir şey öğrenmeden bunu yakalar. | ROC-AUC, PR-AUC ve ilk %N yakalama oranını birlikte vermek. |
| 0,5 eşiğini sorgulamamak | Eşik, kapasiteye ve maliyete göre değişmesi gereken bir karar. | Eşiği doğrulama setinde, iş kısıtına göre seçmek. |
| Eksikleri desenine bakmadan doldurmak | Yapısal eksikliğe medyan yazmak veriyi bozar. | Eksikliğin hangi değişkenle açıklandığını kontrol etmek. |
| Katsayıyı nedensellik saymak | Fiber optik kaybı "yapmıyor"; onunla birlikte anılıyor. | İlişkiyi tarif etmek, nedeni deneyle sınamak. |
| Modeli bir kez kurup bırakmak | Müşteri davranışı ve kampanyalar değişir; model eskir. | Performansı ve girdi dağılımlarını düzenli izlemek. |
| Tek bir bölünmeye güvenmek | 1.409 gözlemlik test setinde sayılar tohuma göre oynar. | Tekrarlı çapraz doğrulamayla aralık raporlamak. |
Sonuç
Bu veride üç model de birbirine yakın çıktı: ROC-AUC 0,826 ile 0,841 arasında. Yani model seçimi bu problemin zor kısmı değil. Zor kısım, çıkan olasılığı doğru soruya bağlamak.
Doğruluk oranına bakan biri modeli çöpe atardı — %73,8, hiçbir şey yapmayan modelin 0,3 puan üstünde. Lift tablosuna bakan biri ise şunu görüyor: en riskli %10'luk dilimde kayıp oranı %75,7, yani rastgele aramanın 2,85 katı isabet. Aynı model, aynı sayılar; farklı olan tek şey sorulan soru.
“Model kimin ayrılacağını söyler. Kimi arayacağını söyleyen şey, modelin çıktısıyla ekibin kapasitesini birleştiren karardır.”
Building a churn model is not the hard part. The hard part is turning the probability it produces into an answer to "who do we call this week?" In this post I build a churn prediction end to end on 7,043 telecom customers — and show with numbers why the model's accuracy is a misleading measure of success.
The data is IBM's Telco Customer Churn set, a standard in churn work: 21 columns, one row per customer, and a target of whether the customer left.
“A churn model's value does not show up in how many customers it classifies correctly, but in how many departing customers it can reach with a limited number of calls.”
1. The Problem and the Base Rate
One number has to come first: 1,869 of the 7,043 customers churned, a rate of 26.5%. That number sets the floor for every evaluation that follows.
7,043 customers
21 variables, no duplicate customer records.
Churn (yes/no)
1,869 left, 5,174 stayed.
73.5%
The accuracy of a model that says "nobody leaves".
5,634 / 1,409
Stratified 80/20; churn rate is 26.5% in both sets.
2. Where Does Churn Concentrate?
Looking at the data before modelling already reveals most of what the model will later find. Four breakdowns are enough.
Month-to-month customers churn at 15 times the rate of two-year contracts. A split that sharp in a single variable is rare; we can already expect the model to lean on this column.
| Breakdown | Group | Customers | Churn rate |
|---|---|---|---|
| Internet service | Fiber optic | 3,096 | 41.9% |
| DSL | 2,421 | 19.0% | |
| None | 1,526 | 7.4% | |
| Payment method | Electronic check | 2,365 | 45.3% |
| Mailed check | 1,612 | 19.1% | |
| Bank transfer (automatic) | 1,544 | 16.7% | |
| Credit card (automatic) | 1,522 | 15.2% | |
| Tech support | No | 3,473 | 41.6% |
| Yes | 2,044 | 15.2% | |
| No internet service | 1,526 | 7.4% |
All three tables point the same way: the riskiest profile is a loosely committed, month-to-month customer without support. That customers paying by electronic check churn at three times the rate of those on automatic payment is especially striking — payment method behaves here like a proxy for intent.
The first six months are critical: more than half of new customers leave. Risk falls monotonically with tenure, down to 9.5% past 49 months. That alone says where a retention budget should go.
3. Is "Missing" Data Really Missing?
The TotalCharges column has 11 blank cells. The reflex is to fill them with the median or drop those rows. The better first move is to ask why they are empty.
df["TotalCharges"] = pd.to_numeric(
    df["TotalCharges"].replace(r"^\s*$", pd.NA, regex=True),
    errors="coerce")

df.loc[df["TotalCharges"].isna(), "tenure"].unique()
# array([0])  -> every one of them has zero tenure
All eleven customers have a tenure of zero. These are brand-new subscriptions that have not been billed yet; their total charges are not missing, they do not exist yet. Filling them with the median would invent a history these customers never had.
tenure = 0); the right move is either a zero or a separate "new customer" flag for the model. Eleven rows vanish inside 7,043 — but the same pattern across thousands of rows in a larger dataset would make this decision matter a great deal.4. Three Models, One Test Set
Numeric variables are standardised, categoricals one-hot encoded, and three models run through the same pipeline. For the class imbalance I use class_weight="balanced", which makes the model treat the minority class as more expensive to miss.
preprocess = ColumnTransformer([
    ("num", Pipeline([("i", SimpleImputer(strategy="median")),
                      ("s", StandardScaler())]), numeric),
    ("cat", Pipeline([("i", SimpleImputer(strategy="most_frequent")),
                      ("o", OneHotEncoder(handle_unknown="ignore"))]), categorical),
])

X_tr, X_te, y_tr, y_te = train_test_split(
    X, y, test_size=0.2, random_state=42, stratify=y)

for name, model in models.items():
    p = Pipeline([("prep", preprocess), ("model", model)]).fit(X_tr, y_tr)
probability = p.predict_proba(X_te)[:, 1]| Model | Accuracy | Precision | Recall | F1 | ROC-AUC | PR-AUC | Brier |
|---|---|---|---|---|---|---|---|
| Logistic regression | 0.738 | 0.504 | 0.783 | 0.614 | 0.841 | 0.633 | 0.169 |
| Random forest | 0.759 | 0.534 | 0.743 | 0.621 | 0.837 | 0.641 | 0.158 |
| Extra Trees | 0.757 | 0.532 | 0.709 | 0.608 | 0.826 | 0.626 | 0.161 |
| Base rate | 0.735 | — | 0.000 | — | 0.500 | 0.265 | — |
The most telling row is the last one. Logistic regression's 73.8% accuracy is just 0.3 points above the 73.5% of a model that does nothing. Anyone judging this model by accuracy would conclude it does not work. Yet its ROC-AUC is 0.841 and its recall 0.783 — the model catches more than three quarters of the customers who actually leave.
class_weight="balanced" pushes the model not to miss churners, and the price is false alarms. The model flags 581 customers as leaving; 293 of them actually do. Accuracy drops because 288 customers are flagged for nothing — but 293 of the 374 real churners are caught. That is not a flaw, it is a deliberate trade.5. The Threshold Is an Assumption
Every metric above rests on one decision: call it churn when the probability passes 0.5. That cut-off comes from habit, not from the mathematics. Changing it does not change the model, only how its probabilities become decisions.
| Threshold | Accuracy | Recall | Precision | F1 | Customers flagged |
|---|---|---|---|---|---|
| 0.3 | 0.653 | 0.928 | 0.429 | 0.587 | 809 |
| 0.4 | 0.701 | 0.866 | 0.466 | 0.606 | 695 |
| 0.5 | 0.738 | 0.783 | 0.504 | 0.614 | 581 |
| 0.6 | 0.762 | 0.706 | 0.540 | 0.612 | 489 |
| 0.7 | 0.789 | 0.602 | 0.603 | 0.602 | 373 |
What picks the threshold is not statistics but team capacity and cost. On a list of 1,409 customers, a team able to call 800 a month covers 92.8% of the churn at a threshold of 0.3. With capacity for 400 calls, 0.7 is the realistic choice: 60.2% of churners are caught, but roughly every second call lands on a real one.
6. What Does the Model Say?
The best thing about logistic regression is that it can be read. Converting its coefficients to odds ratios makes each variable's direction and size visible directly.
| Variable | Coefficient | Odds ratio | Reading |
|---|---|---|---|
| Fiber optic internet | +0.705 | 2.02 | Doubles the odds of churning. |
| Month-to-month contract | +0.663 | 1.94 | The sharpest split from the exploration shows up here too. |
| Electronic check | +0.239 | 1.27 | Clearly riskier than automatic payment. |
| No tech support | +0.164 | 1.18 | Going without support raises the risk. |
| Tenure (standardised) | −1.124 | 0.33 | The strongest protective effect: one standard deviation of tenure cuts the odds to a third. |
| Two-year contract | −0.781 | 0.46 | A long contract more than halves the risk. |
Permutation importance gives the same ordering: tenure alone costs 0.152 of ROC-AUC when shuffled, followed by InternetService (0.043), Contract (0.040) and MonthlyCharges (0.038). Three quarters of what the model knows sits in four variables.
MonthlyCharges is negative (odds ratio 0.52) — yet on its own, churn is higher among expensive plans. This is not a contradiction but a conditional effect: the model already knows about "fiber optic" and reads the risk of being expensive from there. Given that a customer is on fiber, a higher monthly bill points to a broader, more committed subscription. In a multivariate model coefficients are read "holding the others constant"; they cannot be compared directly with single-variable intuition.7. Turning the Model Into Business Value
The original question was: who do we call this week? Accuracy does not answer it; lift does. Sort customers by risk score, take the top slice, and look at how many of them actually churned.
| Slice | Customers | Churn rate in slice | Churners captured | Lift |
|---|---|---|---|---|
| Top 10% | 140 | 75.7% | 106 / 374 (28.3%) | 2.85× |
| Top 20% | 281 | 65.8% | 185 / 374 (49.5%) | 2.48× |
| Top 30% | 422 | 57.6% | 243 / 374 (65.0%) | 2.17× |
| Top 50% | 704 | 46.3% | 326 / 374 (87.2%) | 1.74× |
This table is far more useful than the accuracy one. Call the riskiest 10% and three out of every four customers are genuinely about to leave. Calling at random would hit 26.5%; the model makes each call 2.85 times more likely to land. With capacity to call half the base, you reach 87% of the churn.
- Score
- Rank
- Cut by
Capacity - Measure vs
Control
Three of the four steps are technical and one is not. Scoring and ranking are the model's job; where the list gets cut is set by the team's weekly capacity. The fourth step is purely a matter of design: leaving a randomly chosen share of flagged customers untouched.
8. Common Mistakes
| Mistake | Why it is a problem | Better approach |
|---|---|---|
| Reporting accuracy | The base rate is 73.5%; a model reaches it without learning anything. | Report ROC-AUC, PR-AUC and top-N capture together. |
| Never questioning the 0.5 cut-off | The threshold is a decision that should follow capacity and cost. | Choose it on a validation set against the business constraint. |
| Imputing without checking the pattern | Writing a median over structural missingness corrupts the data. | Check which variable explains the missingness. |
| Reading a coefficient as causation | Fiber optic does not "cause" churn; it travels with it. | Describe the association; test the cause with an experiment. |
| Building the model once and walking away | Customer behaviour and campaigns change; models go stale. | Monitor performance and input distributions on a schedule. |
| Trusting a single split | On a 1,409-row test set the numbers move with the seed. | Report a range from repeated cross-validation. |
Conclusion
All three models landed close together on this data: ROC-AUC between 0.826 and 0.841. Model selection is not the hard part of this problem. The hard part is attaching the resulting probability to the right question.
Someone looking at accuracy would throw the model away — 73.8%, a mere 0.3 points above doing nothing. Someone looking at the lift table sees this instead: in the riskiest 10%, the churn rate is 75.7%, 2.85 times better than calling at random. Same model, same numbers; the only difference is the question being asked.
“The model tells you who is going to leave. What tells you who to call is the decision that joins the model's output to the team's capacity.”