A/B Testi Nedir? Veri Odaklı Karar Verme
Hipotez kurmaktan kontrol ve test gruplarına, dönüşüm oranından istatistiksel anlamlılığa kadar bir A/B testinin tüm adımlarını örnekle inceliyorum.
- İstatistik
- Araçlar
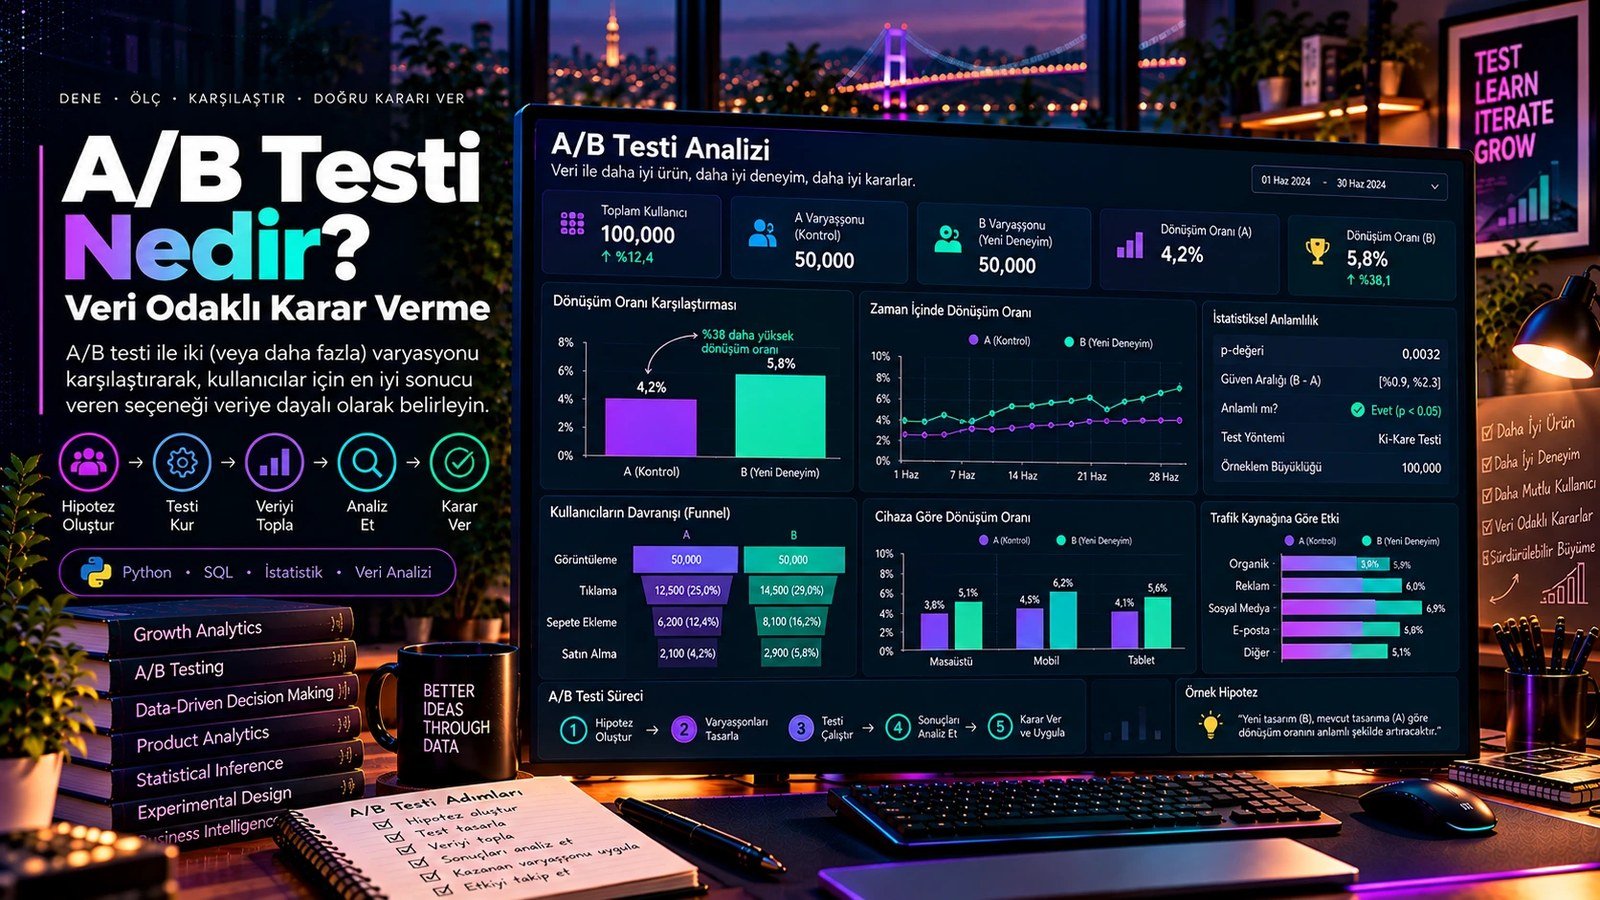
“Hangisi daha iyi?” sorusunu tahminle değil, kontrollü bir deneyle yanıtlamak. A/B testi; web sitelerinden reklam kampanyalarına, e-posta başlıklarından ürün akışlarına kadar birçok alanda kullanıcı davranışını ölçerek daha bilinçli kararlar vermeyi sağlıyor.
Bu yazıda hipotez kurmaktan kontrol/test gruplarına, dönüşüm oranından istatistiksel anlamlılığa kadar bir A/B testinin tüm adımlarını gerçek hayata yakın bir e-ticaret örneğiyle ele alıyorum.
“İyi bir deney yalnızca ‘hangi grup kazandı?' sorusuna cevap vermez; farkın büyüklüğünü, belirsizliğini ve iş açısından değerini de ortaya koyar.”
1. A/B Testi Nedir?
A/B testi, bir ürünün, sayfanın, reklamın veya mesajın iki farklı versiyonunu kullanıcı gruplarına göstererek hangi versiyonun hedeflenen davranışı daha iyi gerçekleştirdiğini ölçen kontrollü deney yöntemidir.
En basit senaryoda kullanıcıların bir bölümü A versiyonunu (kontrol), diğer bölümü B versiyonunu (test) görür. Sonra satın alma, kayıt olma, form gönderme veya reklama tıklama gibi önceden belirlenmiş bir hedef karşılaştırılır.
Kontrol
Mevcut durumda kullanılan versiyon; karşılaştırmanın referans noktası.
Test
Değişiklik içeren versiyon; etkisi kontrol grubuna göre ölçülür.
Hedef metrik
Sonucu belirleyen ana ölçü: dönüşüm, tıklama, gelir veya başka bir gösterge.
- Hipotez
Oluştur - Testi
Kur - Veriyi
Topla - Analiz
Et - Karar
Ver
2. Veri Odaklı Karar Vermede Neden Önemli?
Pazarlama ve ürün kararlarında “bu tasarım daha güzel”, “bu başlık kesin daha çok tık alır” gibi sezgisel yorumlar faydalı başlangıç noktaları olabilir; ama tek başına kanıt değildir. A/B testi bu varsayımları ölçülebilir hipotezlere dönüştürüyor.
Böylece ekipler “B daha iyi görünüyor” demek yerine “B versiyonu, belirli koşullarda dönüşüm oranını ne ölçüde değiştiriyor ve bu fark istatistiksel olarak güvenilir mi?” sorusunu sorabiliyor.
3. Hipotez Nasıl Kurulur?
İyi bir deney ölçülebilir bir hipotezle başlar. Hipotez yalnızca yapılacak değişikliği değil, beklenen sonucu da açıklar.
| Hipotez | İfade |
|---|---|
| H₀ (sıfır hipotezi) | A ve B versiyonlarının hedef metrik üzerinde anlamlı bir farkı yoktur. |
| H₁ (alternatif hipotez) | B versiyonunun hedef metrik üzerinde A'dan farklı bir etkisi vardır. |
Hipotezin ölçülebilir olması şart. “Sayfa daha iyi olacak” yerine “satın alma dönüşüm oranı artacak” denildiğinde test edilecek net bir çıktı ortaya çıkıyor.
4. Kontrol ve Test Grupları
Kullanıcıların gruplara mümkün olduğunca rastgele atanması önemli. Amaç, iki grubun yaş, cihaz, trafik kaynağı ve önceki davranış gibi özellikler açısından gereksiz biçimde ayrışmasını önlemek.
Mevcut deneyim
Bugün kullanılan sayfa veya kampanya; yeni versiyon bununla karşılaştırılır.
Değiştirilmiş deneyim
Hipotezi sınamak için belirli bir değişkenin farklılaştırıldığı versiyon.
Tek değişken
Yalnızca başlık değiştiyse, sonucun hangi değişiklikten geldiğini yorumlamak kolaydır.
Yeterli hacim
Çok az kullanıcıyla yapılan testlerde küçük farklar güvenilir görünmez.
5. Dönüşüm Oranı Nasıl Hesaplanır?
A/B testlerinde en sık kullanılan göstergelerden biri dönüşüm oranı. Hedef davranışı gerçekleştiren kullanıcıların toplam kullanıcıya oranını ifade eder.
CR: dönüşüm oranı, C: dönüşüm sayısı, N: toplam kullanıcı sayısı.
| Grup | Kullanıcı | Dönüşüm | Dönüşüm oranı |
|---|---|---|---|
| A • Kontrol | 100.000 | 5.800 | %5,8 |
| B • Test | 100.000 | 7.100 | %7,1 |
Göreceli artış nasıl bulunur?
Bu örnekte B versiyonunun dönüşüm oranı yaklaşık %22,4 daha yüksek görünüyor. Fakat burada önemli bir ayrım var: gözlenen fark ile istatistiksel olarak güvenilir fark aynı şey değil.
6. İstatistiksel Anlamlılık Nedir?
Bir deneyde B'nin A'dan yüksek sonuç vermesi, tek başına B'nin gerçekten daha iyi olduğunu kanıtlamaz. Aradaki fark örneklem kaynaklı rastlantısal dalgalanmanın sonucu olabilir. İstatistiksel anlamlılık, gözlenen farkın yalnızca şans eseri ortaya çıkma ihtimalini değerlendirmeye yardımcı olur.
p-değeri
Test edilen varsayım altında gözlenen veya daha uç bir farkın ne kadar sıra dışı olduğunu değerlendirir. Tek başına “başarı yüzdesi” değildir.
Güven aralığı
Etkinin ne büyüklükte olabileceğine dair aralık sunar; “anlamlı/anlamsız” demekten çok daha açıklayıcıdır.
İstatistiksel anlamlılık ≠ iş açısından anlamlılık
B versiyonu istatistiksel olarak anlamlı şekilde %1 daha iyi olabilir. Fakat bu iyileştirmenin maliyeti, kullanıcı deneyimine etkisi veya gelir katkısı çok düşükse iş kararı farklı olabilir. İyi bir A/B testi hem istatistiksel hem de iş açısından değerlendirilir.
7. Gerçek Hayata Yakın Bir Örnek
Bir e-ticaret sitesinde “Sepete Ekle” butonunun yeterince görünür olmadığı düşünülüyor. Pazarlama ekibi, butonu daha belirgin hale getiren yeni bir tasarımın satın alma oranını artıracağını öngörüyor.
Deney tasarımı
| Alan | Karar |
|---|---|
| Hipotez | Daha görünür buton, satın alma dönüşümünü artırır. |
| Kontrol | Mevcut ürün sayfası |
| Test | Yeni buton konumu ve tasarımı |
| Ana metrik | Satın alma dönüşüm oranı |
| İkincil metrik | Sepete ekleme oranı ve kullanıcı başına gelir |
| Dağılım | %50 A / %50 B |
Örnek sonuç
+1,3 puan
Dönüşüm oranındaki mutlak artış (%5,8 → %7,1).
+%22,4
Kontrol grubuna göre göreceli iyileşme.
2 ek metrik
Sepete ekleme ve gelir etkisi kararı destekler.
Son aşamada uygun istatistiksel test uygulanır ve farkın güvenilirliği incelenir. Sonuç, önceden belirlenen analiz planına göre anlamlı bulunursa B versiyonunun yayına alınması düşünülebilir. Ancak karar yalnızca p-değerine değil, gelir ve kullanıcı deneyimi göstergelerine de bakılarak verilmeli.
Python ile temel dönüşüm hesabı
control_users = 100000
control_conversions = 5800

test_users = 100000
test_conversions = 7100

control_rate = control_conversions / control_users
test_rate = test_conversions / test_users

print("Kontrol:", control_rate)
print("Test:", test_rate)

lift = (test_rate - control_rate) / control_rate
print("Goreceli artis:", lift)
Farkın istatistiksel olarak anlamlı olup olmadığını değerlendirmek için iki oran arasındaki farkı test eden yöntemler kullanılır:
from statsmodels.stats.proportion import proportions_ztest

# dönüşümler ve kullanıcı sayıları
donusumler = [5800, 7100]
kullanicilar = [100000, 100000]

z, p = proportions_ztest(donusumler, kullanicilar)
print("z:", z, "p:", p)
8. Sonuçları Nasıl Yorumlamalı?
A/B testi sonuçlarını okurken tek bir yüzdeye odaklanmak yerine deneyin tamamını değerlendirmek gerekiyor. Şu dört soru iyi bir başlangıç:
Fark ne kadar?
Mutlak ve göreceli etkiyi ayrı ayrı hesapla.
Güvenilir mi?
İstatistiksel belirsizliği ve güven aralığını incele.
İşe etkisi ne?
Gelir, maliyet, elde tutma veya diğer göstergeleri değerlendir.
Deney doğru mu?
Gruplar, süre, trafik ve ölçüm kalitesi uygun mu kontrol et.
9. Sık Yapılan Hatalar
| Hata | Neden problem? | Daha iyi yaklaşım |
|---|---|---|
| Sonuca çok erken bakmak | Rastlantısal dalgalanmalar yanıltır. | Önceden belirlenen deney planına ve örneklem ihtiyacına uy. |
| Aynı anda çok şey değiştirmek | Hangi değişkenin etki yarattığı belirsizleşir. | Hipoteze bağlı net bir değişiklik yap. |
| Sadece p-değerine odaklanmak | Etkinin büyüklüğü ve belirsizlik gözden kaçar. | Etki büyüklüğü, güven aralığı ve iş metriklerini birlikte değerlendir. |
| Yanlış metrik seçmek | Kolay ölçülen bir metrik gerçek hedefi temsil etmeyebilir. | Ana başarı metriğini iş hedefiyle ilişkilendir. |
| Grupların dengesiz olması | Karşılaştırmanın adilliği bozulur. | Rastgele atama ve dağılımı kontrol et. |
10. İyi Bir A/B Testi İçin Kontrol Listesi
Net hipotez
Neyi değiştirdiğin ve hangi davranışı etkilemesini beklediğin açık mı?
Doğru metrik
Başarı ölçüsü iş hedefini gerçekten temsil ediyor mu?
Adil gruplar
Kullanıcılar rastgele ve dengeli dağıtılıyor mu?
Yeterli veri
Sonucun güvenilirliği için yeterli örneklem ve uygun süre var mı?
İstatistik
Belirsizlik, güven aralığı ve uygun hipotez testi dikkate alınıyor mu?
İş yorumu
Sonuç gerçek gelir, maliyet veya kullanıcı davranışı açısından anlamlı mı?
A/B testi web sitesi, mobil uygulama, reklam kreatifi, e-posta başlığı, açılış sayfası, buton metni, fiyatlandırma sunumu ve kullanıcı karşılama akışı gibi birçok alanda uygulanabiliyor.
Sonuç: Daha Az Tahmin, Daha Çok Kanıt
A/B testi, veri odaklı karar verme kültürünün en pratik yöntemlerinden biri. Kontrol ve test gruplarını karşılaştırarak bir değişikliğin gerçekten fayda sağlayıp sağlamadığını sistematik biçimde değerlendirmeye yardımcı oluyor.
Testleri başarılı kılan asıl unsur ise doğru hipotez, doğru deney tasarımı, doğru metrik ve doğru istatistiksel yorum kombinasyonu. Veri analistleri için bu süreç; ham kullanıcı davranışını ölçülebilir kanıta ve sonunda daha sağlam iş kararlarına dönüştürmenin en güçlü yollarından biri.
“A/B testinin değeri kazananı ilan etmek değil; kararın arkasındaki kanıtı görünür kılmaktır.”
Answering “which one is better?” with a controlled experiment instead of a guess. A/B testing measures user behaviour across websites, ad campaigns, email subject lines and product flows, and lets teams decide with evidence.
In this post I go through every step of an A/B test — from forming a hypothesis to control and test groups, from conversion rate to statistical significance — over a realistic e-commerce example.
“A good experiment does not only answer ‘which group won?'; it also shows the size of the difference, its uncertainty and its business value.”
1. What Is an A/B Test?
An A/B test is a controlled experiment that shows two different versions of a product, page, ad or message to user groups and measures which version performs the target behaviour better.
In the simplest setup, part of the users see version A (control) and the rest see version B (test). A predefined goal — a purchase, a sign-up, a form submission or an ad click — is then compared.
Control
The version currently in use; the reference point of the comparison.
Test
The version carrying the change; its effect is measured against the control.
Target metric
The main measure that decides the outcome: conversion, clicks, revenue or another indicator.
- Form a
Hypothesis - Set Up
the Test - Collect
Data - Analyse
- Decide
2. Why Does It Matter for Data-Driven Decisions?
In marketing and product decisions, intuitions such as “this design looks better” or “this headline will definitely get more clicks” can be useful starting points, but they are not evidence on their own. A/B testing turns those assumptions into measurable hypotheses.
Teams can then ask “by how much does version B change the conversion rate under these conditions, and is that difference statistically reliable?” instead of saying “B looks better”.
3. How Is the Hypothesis Formed?
A good experiment starts with a measurable hypothesis that explains not only the change but the expected outcome.
| Hypothesis | Statement |
|---|---|
| H₀ (null) | There is no meaningful difference between versions A and B on the target metric. |
| H₁ (alternative) | Version B has a different effect on the target metric than A. |
The hypothesis has to be measurable. “The page will be better” gives nothing to test; “the purchase conversion rate will increase” gives a clear outcome.
4. Control and Test Groups
Assigning users to groups as randomly as possible matters. The aim is to prevent the two groups from differing needlessly in age, device, traffic source or previous behaviour.
Current experience
The page or campaign in use today; the new version is compared against it.
Changed experience
The version where one specific variable is changed to test the hypothesis.
One variable
If only the headline changed, it is easier to attribute the result to that change.
Enough volume
In tests with very few users, small differences do not look reliable.
5. How Is the Conversion Rate Calculated?
One of the most used indicators in A/B tests is the conversion rate: the share of users who performed the target behaviour.
CR: conversion rate, C: number of conversions, N: total users.
| Group | Users | Conversions | Conversion rate |
|---|---|---|---|
| A • Control | 100,000 | 5,800 | 5.8% |
| B • Test | 100,000 | 7,100 | 7.1% |
How is the relative lift found?
In this example version B's conversion rate looks about 22.4% higher. But there is an important distinction here: an observed difference and a statistically reliable difference are not the same thing.
6. What Is Statistical Significance?
B scoring higher than A in one experiment does not prove on its own that B is genuinely better. The difference may be random fluctuation from sampling. Statistical significance helps evaluate how likely the observed difference is to have appeared by chance alone.
p-value
Evaluates how unusual the observed (or a more extreme) difference is under the tested assumption. It is not a “success percentage”.
Confidence interval
Gives a range for how large the effect might be — far more informative than a plain “significant or not”.
Statistical significance ≠ business significance
Version B may be statistically significantly 1% better. If the cost of that improvement, its effect on user experience or its revenue contribution is very small, the business decision can still go the other way. A good A/B test is judged both statistically and commercially.
7. A Realistic Example
On an e-commerce site the “Add to cart” button is thought not to be visible enough. The marketing team expects that a new design making the button more prominent will increase the purchase rate.
The experiment design
| Field | Decision |
|---|---|
| Hypothesis | A more visible button increases purchase conversion. |
| Control | The current product page |
| Test | The new button position and design |
| Primary metric | Purchase conversion rate |
| Secondary metric | Add-to-cart rate and revenue per user |
| Split | 50% A / 50% B |
The example result
+1.3 points
The absolute increase in conversion rate (5.8% → 7.1%).
+22.4%
The relative improvement over the control group.
2 extra metrics
Add-to-cart rate and revenue impact back the decision up.
In the final step the appropriate statistical test is run and the reliability of the difference is examined. If the result is significant under the planned analysis, rolling out version B can be considered — but the decision should also weigh revenue and user experience indicators, not the p-value alone.
A basic conversion calculation in Python
control_users = 100000
control_conversions = 5800

test_users = 100000
test_conversions = 7100

control_rate = control_conversions / control_users
test_rate = test_conversions / test_users

print("Control:", control_rate)
print("Test:", test_rate)

lift = (test_rate - control_rate) / control_rate
print("Relative lift:", lift)
To judge whether the difference is statistically significant, methods that test the difference between two proportions are used:
from statsmodels.stats.proportion import proportions_ztest

# conversions and user counts
conversions = [5800, 7100]
users = [100000, 100000]

z, p = proportions_ztest(conversions, users)
print("z:", z, "p:", p)
8. How Should the Results Be Read?
Rather than focusing on a single percentage, the whole experiment has to be judged. These four questions are a good start:
How big is the difference?
Calculate the absolute and relative effect separately.
Is it reliable?
Examine the statistical uncertainty and the confidence interval.
What is the business impact?
Evaluate revenue, cost, retention and other indicators.
Is the experiment sound?
Check the groups, duration, traffic and measurement quality.
9. Common Mistakes
| Mistake | Why is it a problem? | Better approach |
|---|---|---|
| Looking at the result too early | Random fluctuations mislead. | Follow the predefined plan and sample size requirement. |
| Changing too many things at once | It becomes unclear which variable caused the effect. | Make one clear change tied to the hypothesis. |
| Focusing only on the p-value | The size of the effect and the uncertainty get missed. | Weigh effect size, confidence interval and business metrics together. |
| Choosing the wrong metric | An easily measured metric may not represent the real goal. | Tie the primary success metric to the business goal. |
| Imbalanced groups | The fairness of the comparison breaks down. | Check the randomisation and the split. |
10. A Checklist for a Good A/B Test
A clear hypothesis
Is it obvious what you changed and which behaviour you expect it to affect?
The right metric
Does the success measure really represent the business goal?
Fair groups
Are users assigned randomly and in a balanced way?
Enough data
Is there enough sample and a suitable duration for a reliable result?
Statistics
Are uncertainty, the confidence interval and a suitable test taken into account?
Business reading
Is the outcome meaningful in terms of real revenue, cost or user behaviour?
A/B tests can be applied to websites, mobile apps, ad creatives, email subject lines, landing pages, button copy, pricing presentation and onboarding flows.
Conclusion: Less Guessing, More Evidence
A/B testing is one of the most practical methods in a data-driven decision culture. By comparing control and test groups it helps evaluate systematically whether a change really brings a benefit.
What makes a test successful is the combination of the right hypothesis, the right experiment design, the right metric and the right statistical reading. For data analysts it is one of the strongest ways of turning raw user behaviour into measurable evidence and, in the end, into sounder business decisions.
“The value of an A/B test is not declaring a winner; it is making the evidence behind the decision visible.”