Confusion Matrix Nedir? Accuracy, Precision, Recall ve F1-Score
Sınıflandırma modellerini doğru değerlendirmek için confusion matrix'i ve accuracy, precision, recall, F1-score metriklerini adım adım inceliyorum.
- Makine Öğrenmesi
- İstatistik
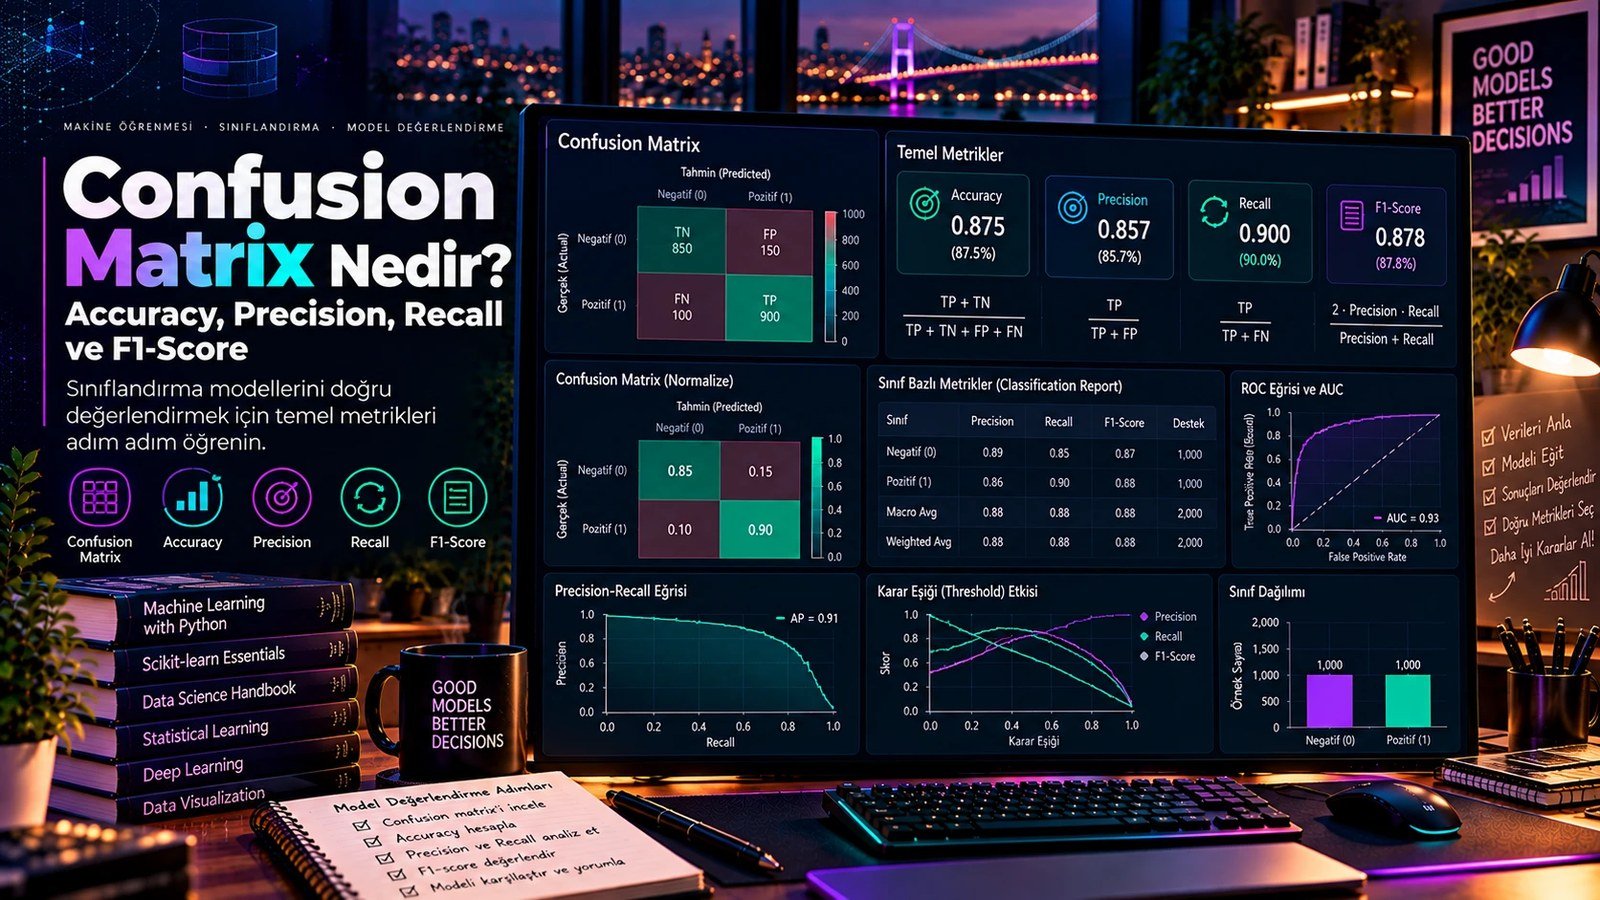
Sınıflandırma modellerinin gerçekten ne kadar iyi çalıştığını anlamak için yalnızca “kaç tanesini doğru bildi?” sorusu yeterli değil. Confusion matrix, modelin doğru ve yanlış tahminlerini ayrıntılı biçimde görmemizi sağlıyor.
Bu yazıda confusion matrix'in dört temel hücresinden başlayıp accuracy, precision, recall ve F1-score metriklerini; hangi problemde hangisine bakmak gerektiğini ve dengesiz veride accuracy'nin neden yanıltıcı olduğunu örneklerle ele alıyorum.
“Model %90 doğru” demek tek başına yeterli değildir; o %10'luk hatanın hangi sınıfta ve hangi yönde gerçekleştiğini de bilmek gerekir.”
Confusion Matrix Nedir?
Confusion matrix (karışıklık matrisi), bir sınıflandırma modelinin gerçek sınıflar ile tahmin ettiği sınıfları karşılaştıran tablodur. Özellikle ikili sınıflandırmada modelin yalnızca doğru tahminlerini değil, hangi tür hataları yaptığını görmemizi sağlar.
Bu ayrım önemli; çünkü bazı problemlerde yanlış pozitif üretmek, bazı problemlerde ise gerçek pozitifi kaçırmak çok daha maliyetli.
- Confusion
Matrix - Accuracy
- Precision
- Recall
- F1-Score
1. TP, TN, FP ve FN
Confusion matrix'in temelini dört sonuç oluşturur. Buradaki “pozitif” ve “negatif” problemin sınıflarıdır; otomatik olarak “iyi” ve “kötü” anlamına gelmez.
| Tahmin: pozitif | Tahmin: negatif | |
|---|---|---|
| Gerçek: pozitif | True Positive (TP) Pozitifi doğru buldu. | False Negative (FN) Pozitifi negatif sandı. |
| Gerçek: negatif | False Positive (FP) Negatifi pozitif sandı. | True Negative (TN) Negatifi doğru buldu. |
Doğru pozitif
Model pozitif dedi ve gerçekten pozitifti.
Doğru negatif
Model negatif dedi ve gerçekten negatifti.
Yanlış pozitif
Model pozitif dedi ama değildi — yanlış alarm.
Yanlış negatif
Model negatif dedi ama pozitifti — kaçırılan vaka.
2. Gerçek Hayat Örneği: Spam E-posta Tespiti
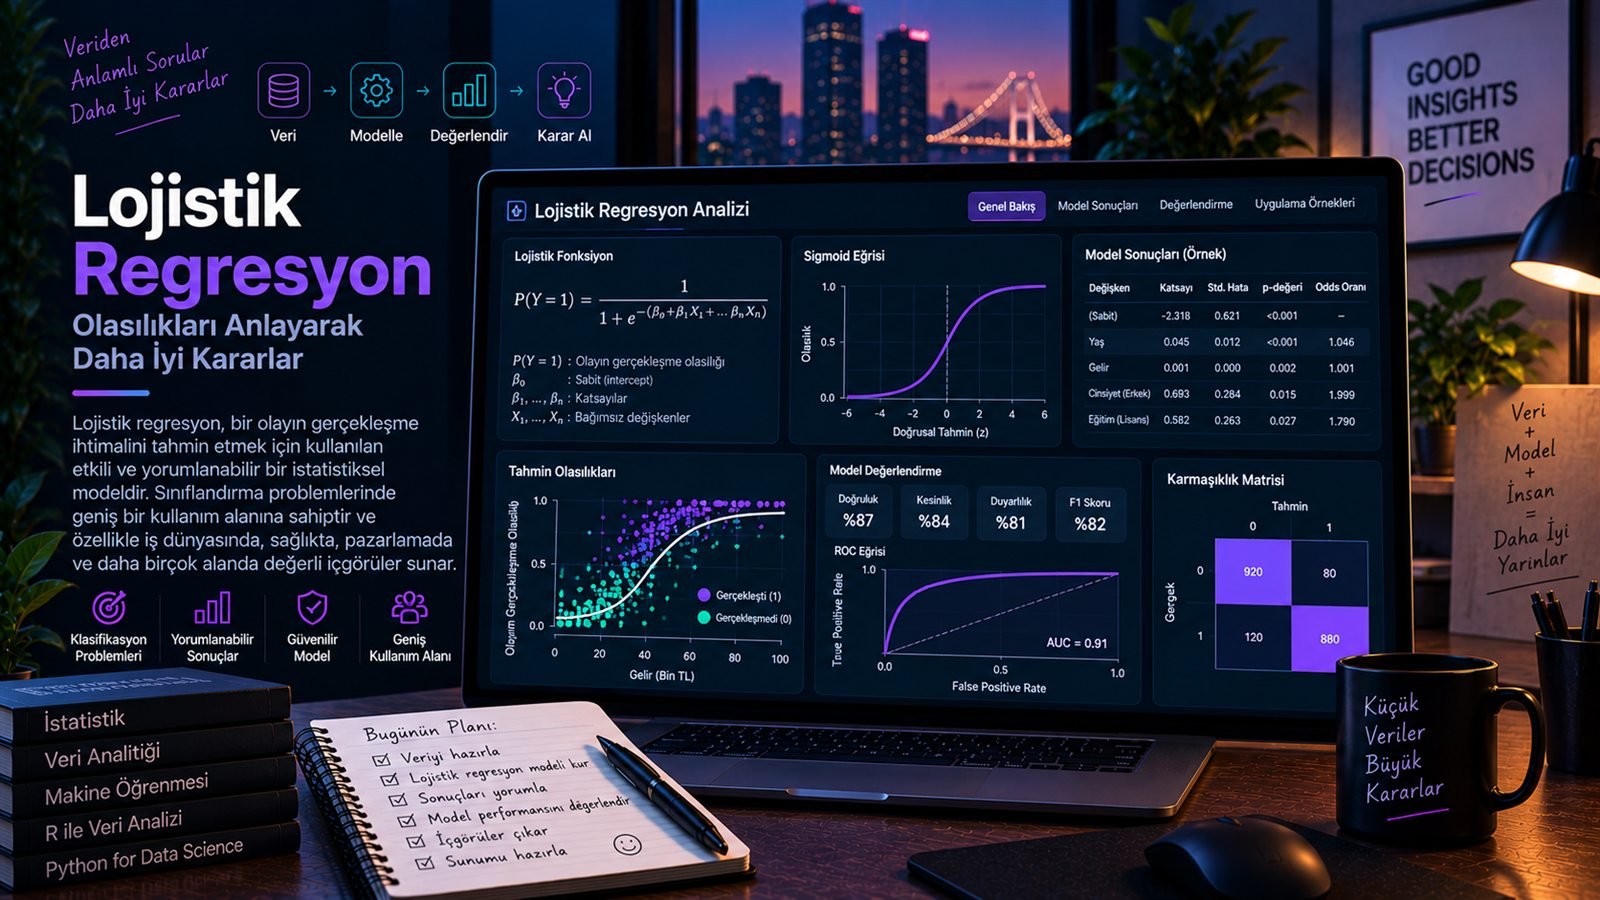
Bir e-posta modelinin mesajları spam veya normal olarak sınıflandırdığını düşünelim. 1.000 e-posta üzerinde şu sonuçlar alınsın:
| Tahmin: spam | Tahmin: normal | |
|---|---|---|
| Gerçek: spam | TP = 180 | FN = 20 |
| Gerçek: normal | FP = 30 | TN = 770 |
Model 180 spam mesajını doğru yakalıyor. Ancak 20 spam mesajını normal sanarak kaçırıyor, 30 normal e-postayı da yanlışlıkla spam klasörüne gönderiyor.
3. Accuracy, Precision, Recall ve F1-Score
Confusion matrix'teki dört değeri kullanarak model performansını farklı açılardan ölçebiliriz.
Accuracy — genel doğruluk
Modelin tüm örnekler içindeki doğru tahmin oranını gösterir.
Sınıflar dengeliyse ve FP ile FN hatalarının maliyeti birbirine yakınsa iyi bir başlangıç metriğidir.
Precision — pozitif tahminlerin kalitesi
Modelin pozitif dediği örneklerin ne kadarının gerçekten pozitif olduğunu ölçer.
Yanlış pozitifleri azaltmak kritikse öne çıkar: gereksiz alarm, yanlış kampanya hedefleme veya yanlış işlem başlatma gibi durumlar.
Recall — pozitifleri yakalama gücü
Gerçekte pozitif olanların ne kadarını modelin yakalayabildiğini gösterir.
Pozitif vakaları kaçırmak kritikse öne çıkar: riskli işlem, arıza veya önemli bir vaka tespiti gibi senaryolar.
F1-score — precision ve recall dengesi
Precision ve recall'un harmonik ortalamasıdır; iki metriğin birlikte güçlü olmasını ister.
Precision ve recall'u tek bir özet sayıyla birlikte değerlendirmek istediğinde, özellikle sınıflar dengesizken faydalıdır.
4. Örnek Üzerinden Hesaplama
Yukarıdaki spam örneğinde TP = 180, TN = 770, FP = 30 ve FN = 20 olduğunda metrikler şöyle çıkar:
| Metrik | Hesap | Sonuç |
|---|---|---|
| Accuracy | (180 + 770) / 1000 | 0,95 → %95 |
| Precision | 180 / (180 + 30) | ≈ 0,857 → %85,7 |
| Recall | 180 / (180 + 20) | 0,90 → %90 |
| F1-score | 2 × (0,857 × 0,90) / (0,857 + 0,90) | ≈ 0,878 → %87,8 |
Dört metrik de yüksek görünüyor; ancak recall'un precision'dan yüksek olması modelin spam yakalamada cömert davrandığını, bunun karşılığında 30 normal e-postayı yanlışlıkla spam'e attığını söylüyor.
5. Hangi Metrik Ne Zaman Tercih Edilmeli?
Yanlış alarm pahalıysa
Modelin pozitif dediği kayıtların mümkün olduğunca gerçekten pozitif olmasını istersin.
Vaka kaçırmak pahalıysa
Gerçek pozitifleri kaçırmamak önceliklidir; FN hatasının maliyeti yüksektir.
Denge arıyorsan
Precision ile recall arasında dengeli performans ve tek bir karşılaştırma metriği istersin.
Sınıflar dengeliyse
Yanlış pozitif ve negatifin maliyeti birbirine yakınsa genel doğruluk anlamlıdır.
| Senaryo | Öncelikli metrik | Neden? |
|---|---|---|
| Dolandırıcılık alarmı | Precision | Çok fazla yanlış alarm operasyon ekibini yorar. |
| Hastalık taraması | Recall | Gerçek vakaları kaçırmamak daha kritiktir. |
| Metin sınıflandırma | F1-score | Yakalama ve yanlış alarm dengesine birlikte bakılır. |
| Dengeli iki sınıf | Accuracy + diğerleri | Genel doğruluk anlamlı bir özet sunar. |
6. Dengesiz Veride Accuracy Neden Yanıltır?
Diyelim ki 10.000 müşterinin yalnızca 100'ü dolandırıcılık vakası. Model tüm müşterilere “dolandırıcılık değil” derse 9.900 doğru tahmin yapmış olur ve accuracy %99 çıkar.
İlk bakışta mükemmel görünür. Fakat model gerçek dolandırıcılık vakalarının hiçbirini yakalayamamıştır; recall %0'dır.
7. Python ile Confusion Matrix ve Metrikler
scikit-learn ile temel metrikleri birkaç satırda hesaplayabilirsin.
from sklearn.metrics import (
    confusion_matrix, accuracy_score,
    precision_score, recall_score, f1_score
)

y_true = [1, 1, 1, 1, 0, 0, 0, 0]
y_pred = [1, 1, 0, 1, 1, 0, 0, 0]

cm = confusion_matrix(y_true, y_pred)
accuracy = accuracy_score(y_true, y_pred)
precision = precision_score(y_true, y_pred)
recall = recall_score(y_true, y_pred)
f1 = f1_score(y_true, y_pred)

print(cm)
print(accuracy, precision, recall, f1)
Tek bir rapor satırında hepsini görmek istersen classification_report() sınıf bazında precision, recall ve F1 değerlerini birlikte verir.
from sklearn.metrics import classification_report

print(classification_report(y_true, y_pred))8. Model Seçiminde Confusion Matrix'i Kullanmak
İki modelin accuracy değeri aynı olsa bile hata profilleri tamamen farklı olabilir. Model karşılaştırırken şu sırayla düşünmek faydalı:
- Confusion
Matrix - Precision
- Recall
- F1-Score
- İş
Maliyeti
Son aşamada metrikleri iş hedefleriyle birleştirmek gerekiyor. Pazarlama modelinde FP gereksiz hedefleme maliyeti yaratırken, risk tespitinde FN çok daha pahalıya mal olabilir.
Sonuç
Confusion matrix, bir sınıflandırma modelini yalnızca “kaç doğru yaptı?” seviyesinde değil, hangi tür hataları neden ürettiği açısından incelemeni sağlar.
Accuracy genel performansı, precision pozitif tahminlerin kalitesini, recall gerçek pozitifleri yakalama gücünü, F1-score ise bu ikisi arasındaki dengeyi özetler.
“En yüksek metriğe sahip modeli otomatik seçmek yerine, iş probleminin hangi hataya daha fazla tolerans gösterdiğini belirle.”
To understand how well a classification model really works, “how many did it get right?” is not enough on its own. A confusion matrix lets us see the model's correct and incorrect predictions in detail.
In this post I start from the four cells of the confusion matrix and go through accuracy, precision, recall and the F1-score: which metric to look at in which problem, and why accuracy misleads on imbalanced data.
“Saying ‘the model is 90% accurate' is not enough; you also need to know in which class and in which direction that 10% of error happened.”
What Is a Confusion Matrix?
A confusion matrix is the table that compares the real classes with the classes a classification model predicted. In binary classification especially, it shows not only the correct predictions but which kind of mistakes the model makes.
That distinction matters, because in some problems producing a false positive is costly, while in others missing a true positive is far worse.
- Confusion
Matrix - Accuracy
- Precision
- Recall
- F1-Score
1. TP, TN, FP and FN
Four outcomes form the basis of the confusion matrix. “Positive” and “negative” here are the classes of the problem; they do not automatically mean “good” and “bad”.
| Predicted: positive | Predicted: negative | |
|---|---|---|
| Actual: positive | True Positive (TP) Found the positive correctly. | False Negative (FN) Thought the positive was negative. |
| Actual: negative | False Positive (FP) Thought the negative was positive. | True Negative (TN) Found the negative correctly. |
True positive
The model said positive and it really was positive.
True negative
The model said negative and it really was negative.
False positive
The model said positive but it was not — a false alarm.
False negative
The model said negative but it was positive — a missed case.
2. A Real-Life Example: Spam Detection
Imagine an email model that classifies messages as spam or normal. On 1,000 emails it produces these results:
| Predicted: spam | Predicted: normal | |
|---|---|---|
| Actual: spam | TP = 180 | FN = 20 |
| Actual: normal | FP = 30 | TN = 770 |
The model catches 180 spam messages correctly. But it misses 20 spam messages by treating them as normal, and it sends 30 normal emails to the spam folder by mistake.
3. Accuracy, Precision, Recall and F1-Score
Using the four values in the confusion matrix, we can measure model performance from different angles.
Accuracy — overall correctness
Shows the proportion of correct predictions across all examples.
It is a good starting metric when the classes are balanced and the cost of FP and FN errors is similar.
Precision — the quality of positive predictions
Measures how many of the examples the model called positive really are positive.
It comes first when reducing false positives is critical: unnecessary alarms, wrong campaign targeting or triggering the wrong process.
Recall — the power to catch positives
Shows how many of the truly positive cases the model managed to catch.
It comes first when missing positive cases is critical: risky transactions, failures or detecting an important case.
F1-score — the balance of precision and recall
The harmonic mean of precision and recall; it wants both metrics to be strong together.
It helps when you want to weigh precision and recall together in a single summary number, especially with imbalanced classes.
4. Calculating the Metrics on the Example
With TP = 180, TN = 770, FP = 30 and FN = 20 from the spam example, the metrics come out as:
| Metric | Calculation | Result |
|---|---|---|
| Accuracy | (180 + 770) / 1000 | 0.95 → 95% |
| Precision | 180 / (180 + 30) | ≈ 0.857 → 85.7% |
| Recall | 180 / (180 + 20) | 0.90 → 90% |
| F1-score | 2 × (0.857 × 0.90) / (0.857 + 0.90) | ≈ 0.878 → 87.8% |
All four look high, but recall being above precision tells us the model is generous in flagging spam, and pays for it by sending 30 normal emails to the spam folder.
5. Which Metric to Prefer, and When?
When false alarms are costly
You want the records the model calls positive to really be positive.
When missing cases is costly
Not missing true positives comes first; the cost of FN is high.
When you need balance
You want balanced performance between precision and recall in one comparison metric.
When classes are balanced
If FP and FN cost about the same, overall correctness is meaningful.
| Scenario | Priority metric | Why? |
|---|---|---|
| Fraud alerting | Precision | Too many false alarms exhaust the operations team. |
| Disease screening | Recall | Not missing real cases is more critical. |
| Text classification | F1-score | Catching positives and avoiding false alarms are weighed together. |
| Two balanced classes | Accuracy + the others | Overall correctness gives a meaningful summary. |
6. Why Does Accuracy Mislead on Imbalanced Data?
Say only 100 of 10,000 customers are fraud cases. If the model calls every customer “not fraud”, it makes 9,900 correct predictions and accuracy lands at 99%.
At first glance that looks perfect. But the model caught none of the real fraud cases; recall is 0%.
7. The Confusion Matrix and Metrics in Python
With scikit-learn you can calculate the core metrics in a few lines.
from sklearn.metrics import (
    confusion_matrix, accuracy_score,
    precision_score, recall_score, f1_score
)

y_true = [1, 1, 1, 1, 0, 0, 0, 0]
y_pred = [1, 1, 0, 1, 1, 0, 0, 0]

cm = confusion_matrix(y_true, y_pred)
accuracy = accuracy_score(y_true, y_pred)
precision = precision_score(y_true, y_pred)
recall = recall_score(y_true, y_pred)
f1 = f1_score(y_true, y_pred)

print(cm)
print(accuracy, precision, recall, f1)
If you want to see everything in one report, classification_report() gives precision, recall and F1 per class together.
from sklearn.metrics import classification_report

print(classification_report(y_true, y_pred))8. Using the Confusion Matrix in Model Selection
Two models can share the same accuracy and still have completely different error profiles. When comparing models, this order helps:
- Confusion
Matrix - Precision
- Recall
- F1-Score
- Business
Cost
In the final step the metrics have to be combined with business goals. In a marketing model an FP creates wasted targeting cost, while in risk detection an FN can be far more expensive.
Conclusion
A confusion matrix lets you examine a classification model not only at the level of “how many did it get right?” but in terms of which kinds of errors it produces and why.
Accuracy summarises overall performance, precision the quality of positive predictions, recall the power to catch true positives, and the F1-score the balance between the last two.
“Instead of automatically picking the model with the highest metric, decide which error your business problem tolerates more.”