R ile Sınıflandırma: Lojistik Regresyon, SVM, CART ve Rastgele Orman
Lojistik regresyon, SVM, CART ve rastgele ormanı aynı veriyle eğitip aynı test setinde karşılaştırıyorum. Sonuç beklenenin tersi çıkıyor.
- Makine Öğrenmesi
- İstatistik
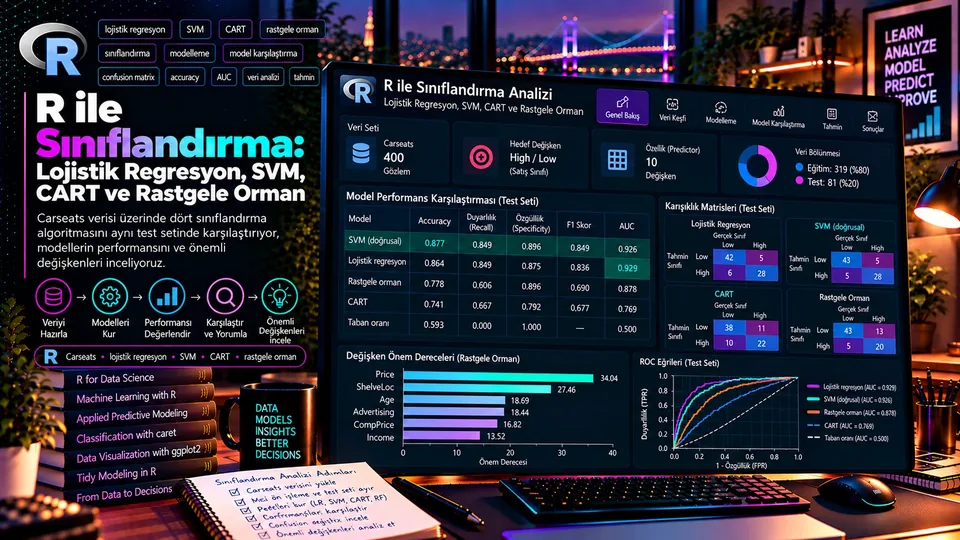
Dört farklı sınıflandırma algoritması, tek bir veri seti, tek bir test kümesi. Bu yazının amacı algoritmaları tek tek anlatmak değil — her birini sitede ayrı yazılarda ele aldım. Buradaki soru şu: aynı problemde hangisi ne yapıyor ve neden?
Serinin üçüncü yazısında Carseats verisi üzerinde lojistik regresyon, destek vektör makineleri, karar ağacı ve rastgele ormanı kuruyor; dördünü de aynı test setinde, aynı metriklerle karşılaştırıyorum.
“Modelleri karşılaştırmak için hepsinin aynı veriyle eğitilmesi yetmez; hepsinin aynı veriyle ölçülmesi de gerekir.”
1. Problem ve Taban Oran
Carseats'te Sales sürekli bir değişken. Sınıflandırma problemine çevirmek için 8 bin adet eşiğinden ikiye ayırıyoruz: 8'in üzerindeki mağazalar High, altındakiler Low.
df <- Carseats
df$Sales <- factor(ifelse(df$Sales <= 8, "Low", "High"),
                   levels = c("Low", "High"))

table(df$Sales)        # Low 236  High 164

set.seed(5364)
idx <- unlist(lapply(levels(df$Sales), function(lv) {
  satirlar <- which(df$Sales == lv)
  sample(satirlar, size = floor(0.8 * length(satirlar)))
}))

train <- df[idx, ]    # 319 gozlem: Low 188, High 131
test <- df[-idx, ] # 81 gozlem: Low 48, High 33İkili sınıf
High (164) / Low (236) — hafif dengesiz ama kritik düzeyde değil.
High
Bütün duyarlılık ve kesinlik değerleri "High" sınıfı için hesaplanıyor.
%59,3
Çoğunluk sınıfını tahmin eden saf modelin doğruluğu.
Tabakalı %80/%20
Sınıf oranları iki sette de korunuyor.
2. Lojistik Regresyon
En yorumlanabilir seçenekle başlıyoruz. Lojistik regresyon, doğrusal bir birleşimi sigmoid fonksiyonundan geçirerek olasılık üretir.
set.seed(86451)
glm_fit <- glm(Sales ~ ., data = train, family = "binomial")

# "High" ikinci seviye oldugu icin model P(High) tahmin ediyor
olasilik <- predict(glm_fit, newdata = test, type = "response")
tahmin   <- factor(ifelse(olasilik > 0.5, "High", "Low"),
                   levels = c("Low", "High"))

table(Tahmin = tahmin, Gercek = test$Sales)predict() çağrısına newdata = test yazmayı unutmak. Bu durumda R sessizce eğitim verisi üzerinde tahmin üretir, sen de modelin test performansını ölçtüğünü sanırsın. Faktör seviyelerinin sırası da önemli: modelin hangi sınıfı modellediği levels() ile kontrol edilmeli.Coefficients:
Estimate Std. Error z value Pr(>|z|)
(Intercept) -5.282068 2.933818 -1.800 0.0718 .
CompPrice 0.192240 0.029544 6.507 7.68e-11 ***
Income 0.030561 0.009737 3.139 0.0017 **
Advertising 0.343855 0.064202 5.356 8.52e-08 ***
Price -0.188692 0.026197 -7.203 5.90e-13 ***
ShelveLocGood 9.076140 1.282961 7.074 1.50e-12 ***
ShelveLocMedium 4.229255 0.805378 5.251 1.51e-07 ***
Age -0.088403 0.018244 -4.846 1.26e-06 ***
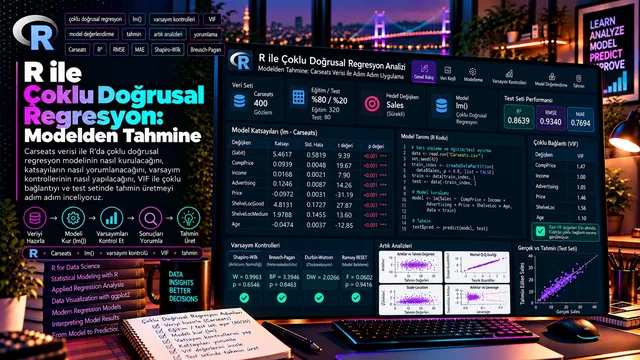
Null deviance: 431.99 on 318 degrees of freedom
Residual deviance: 126.34 on 307 degrees of freedom
AIC: 150.34Sapma (deviance) 431,99'dan 126,34'e düşüyor: model boş modele göre ciddi bir açıklama gücü kazanmış. Katsayılar da regresyon yazısındakiyle aynı hikâyeyi anlatıyor — raf konumu Good olduğunda yüksek satış log-odds'u 9,08 artıyor.
| Gerçek | |||
|---|---|---|---|
| Low | High | ||
| Tahmin | Low | 42 | 5 |
| High | 6 | 28 | |
Accuracy 0,864 · Duyarlılık 0,849 · Özgüllük 0,875 · F1 0,836 · AUC 0,929
0,5 eşiği nereden geliyor?
Yukarıdaki karışıklık matrisi tek bir karardan doğuyor: olasılık 0,5'i geçerse "High". Bu eşik matematikten gelmiyor — bir varsayım. Değiştirdiğinde model değişmez, sadece modelin ürettiği olasılıkları nasıl karara çevirdiğin değişir.
p <- predict(glm_fit, newdata = test, type = "response")

for (esik in c(0.3, 0.4, 0.5, 0.6, 0.7)) {
  tahmin <- factor(ifelse(p > esik, "High", "Low"),
                   levels = c("Low", "High"))
  print(table(tahmin, test$Sales))
}

# Youden J ile en iyi esik:
coords(roc(test$Sales, p), "best", best.method = "youden")
# threshold = 0.5924| Eşik | Accuracy | Duyarlılık | Özgüllük | Kesinlik | F1 |
|---|---|---|---|---|---|
| 0,3 | 0,827 | 0,879 | 0,792 | 0,744 | 0,806 |
| 0,4 | 0,852 | 0,849 | 0,854 | 0,800 | 0,824 |
| 0,5 | 0,864 | 0,849 | 0,875 | 0,824 | 0,836 |
| 0,6 | 0,889 | 0,849 | 0,917 | 0,875 | 0,862 |
| 0,7 | 0,840 | 0,727 | 0,917 | 0,857 | 0,787 |
0,6 eşiği doğruluğu 0,864'ten 0,889'a çıkarıyor — üç mağaza daha doğru sınıflanıyor ve duyarlılıktan hiçbir şey kaybedilmiyor. ROC eğrisi üzerinde Youden J ölçütünün bulduğu optimum eşik de 0,592, yani 0,5 değil.
Eşiği nereye koyacağın aslında bir maliyet sorusu. Yüksek satış potansiyelli bir mağazayı kaçırmanın maliyeti, boşuna yatırım yapmanın maliyetinden büyükse eşik aşağı çekilir; tersiyse yukarı.
3. Destek Vektör Makineleri (SVM)
SVM, iki sınıfı ayıran ve marjı en geniş tutan sınırı arar. Doğrusal çekirdekle başlıyoruz.
library(e1071)

set.seed(144)
svm_fit <- svm(Sales ~ ., data = train,
               kernel = "linear", cost = 1,
               scale = TRUE, type = "C-classification")

tahmin_svm <- predict(svm_fit, newdata = test)
table(Tahmin = tahmin_svm, Gercek = test$Sales)

svm_fit$tot.nSV   # 89 destek vektoru
scale = TRUE şart: SVM mesafe tabanlı bir yöntem. Population (10–509) ile Advertising (0–29) aynı ölçekte değilken, büyük ölçekli değişken sınırı domine eder. Orijinal çalışmada scale = FALSE kullanılmıştı; ölçekleme açıldığında model belirgin biçimde iyileşiyor.| Gerçek | |||
|---|---|---|---|
| Low | High | ||
| Tahmin | Low | 43 | 5 |
| High | 5 | 28 | |
Accuracy 0,877 · Duyarlılık 0,849 · Özgüllük 0,896 · F1 0,849 — dört model arasında en yüksek doğruluk.
cost ve çekirdek: varsayılanlarla mı kalalım?
Yukarıdaki model cost = 1 ve doğrusal çekirdekle kuruldu; ikisi de varsayılan tercih. cost, SVM'in marj ihlallerine ne kadar tolerans göstereceğini belirler: küçük değer geniş ama hoşgörülü bir marj, büyük değer dar ve katı bir sınır demek. Doğru değer veriye bağlı, dolayısıyla aranması gerekir.
set.seed(144)
t1 <- tune(svm, Sales ~ ., data = train, kernel = "linear",
          ranges = list(cost = c(0.01, 0.1, 1, 5, 10)))
t1$performances

t2 <- tune(svm, Sales ~ ., data = train, kernel = "radial",
          ranges = list(cost = c(0.1, 1, 5, 10),
                        gamma = c(0.01, 0.05, 0.1)))
t2$best.parameters # cost = 5, gamma = 0.05| cost | CV hatası | Dağılım (sd) |
|---|---|---|
| 0,01 | 0,1627 | 0,0774 |
| 0,10 | 0,1065 | 0,0573 |
| 1,00 | 0,1128 | 0,0446 |
| 5,00 | 0,1191 | 0,0459 |
| 10,00 | 0,1128 | 0,0513 |
En iyi cost değeri 1 değil 0,1 — ama fark yalnızca 0,006 ve katlar arası standart sapma 0,057. Yani bu tarama "cost'u değiştir" demiyor; "bu veride cost'un geniş bir aralıkta önemi yok" diyor. Tek istisna 0,01: fazla gevşek bir marj modeli belirgin biçimde bozuyor.
| Çekirdek | En iyi parametreler | CV hatası | Destek vektörü | Test doğruluğu |
|---|---|---|---|---|
| Doğrusal | cost = 0,1 | 0,1065 | 89 | 0,877 |
| Radyal (RBF) | cost = 5, gamma = 0,05 | 0,1066 | 128 | 0,827 |
Radyal çekirdek doğrusal olmayan sınırlar çizebiliyor ve genellikle "daha güçlü" sayılıyor. Burada çapraz doğrulama hatası neredeyse birebir aynı (0,1066'ya karşı 0,1065), test doğruluğu ise beş puan daha düşük. Üstelik 89 yerine 128 destek vektörü kullanıyor — yani aynı işi daha karmaşık bir modelle yapıyor.
4. Karar Ağacı (CART)
CART, veriyi ardışık ikili bölünmelerle ayırır. En büyük avantajı okunabilirliği: modeli bir dizi "eğer–ise" kuralı olarak görebilirsin.
library(rpart)
library(rpart.plot)

set.seed(144)
cart_fit <- rpart(Sales ~ ., data = train, method = "class")

# Capraz dogrulama hatasini en kucuk yapan cp
printcp(cart_fit)
en_iyi_cp <- cart_fit$cptable[which.min(cart_fit$cptable[, "xerror"]), "CP"]

cart_budanmis <- prune(cart_fit, cp = en_iyi_cp)
rpart.plot(cart_budanmis) CP nsplit rel error xerror xstd
1 0.32061069 0 1.0000000 1.0000000 0.06707303
2 0.07633588 1 0.6793893 0.6793893 0.06114941
3 0.05343511 2 0.6030534 0.7557252 0.06307573
4 0.03816794 4 0.4961832 0.6335878 0.05981752
5 0.02798982 6 0.4198473 0.5877863 0.05834268
6 0.02290076 9 0.3358779 0.5648855 0.05754827 <- en dusuk xerror
7 0.01000000 11 0.2900763 0.5725191 0.05781745Tablodaki iki sütun farkı anlatıyor: rel error eğitim hatası, ağaç büyüdükçe sürekli düşüyor (1,00 → 0,29). xerror ise çapraz doğrulama hatası ve 9 bölünmeden sonra yükselmeye başlıyor. İşte aşırı öğrenmenin başladığı nokta burası. En düşük xerror'u veren cp = 0,0229 seçiliyor ve ağaç 10 yaprağa budanıyor.
| Gerçek | |||
|---|---|---|---|
| Low | High | ||
| Tahmin | Low | 38 | 11 |
| High | 10 | 22 | |
Accuracy 0,741 · Duyarlılık 0,667 · Özgüllük 0,792 · F1 0,677 · AUC 0,769 — dört model arasında en düşük performans.
5. Rastgele Orman
Rastgele orman, yüzlerce karar ağacını farklı örneklem ve değişken alt kümeleriyle eğitip oylarını birleştirir. Tek ağacın kararsızlığını büyük ölçüde giderir.
library(randomForest)

set.seed(144)
rf_fit <- randomForest(Sales ~ ., data = train, importance = TRUE)
rf_fit

# OOB estimate of error rate: 17.55%
# Confusion matrix (OOB):
#      Low High class.error
# Low  171   17   0.0904
# High  39   92   0.2977

tahmin_rf <- predict(rf_fit, newdata = test)
importance(rf_fit)[, "MeanDecreaseGini"]
OOB (out-of-bag) hatası, rastgele ormanın bedava gelen çapraz doğrulaması: her ağaç eğitilirken dışarıda kalan gözlemler üzerinde test edilir. Buradaki %17,55'lik OOB hatası, ayrı bir doğrulama seti ayırmaya gerek kalmadan elde edilen bir tahmin.
| Değişken | MeanDecreaseGini |
|---|---|
| Price | 34,04 |
| ShelveLoc | 27,46 |
| Age | 18,69 |
| Advertising | 18,44 |
| CompPrice | 16,82 |
| Income | 13,52 |
Değişken önemi sıralaması regresyon modelinin anlattığıyla örtüşüyor: fiyat ve raf konumu açık ara önde. Üç farklı yöntemin aynı iki değişkeni öne çıkarması, bulgunun yönteme değil veriye ait olduğunu gösteriyor.
| Gerçek | |||
|---|---|---|---|
| Low | High | ||
| Tahmin | Low | 43 | 13 |
| High | 5 | 20 | |
Accuracy 0,778 · Duyarlılık 0,606 · Özgüllük 0,896 · F1 0,690 · AUC 0,878
6. Dört Model, Tek Tablo
Bütün modeller aynı eğitim setiyle kuruldu ve aynı 81 gözlemlik test setinde ölçüldü. Pozitif sınıf "High".
| Model | Accuracy | Duyarlılık | Özgüllük | F1 | AUC |
|---|---|---|---|---|---|
| SVM (doğrusal) | 0,877 | 0,849 | 0,896 | 0,849 | 0,926 |
| Lojistik regresyon | 0,864 | 0,849 | 0,875 | 0,836 | 0,929 |
| Rastgele orman | 0,778 | 0,606 | 0,896 | 0,690 | 0,878 |
| CART | 0,741 | 0,667 | 0,792 | 0,677 | 0,769 |
| Taban oran | 0,593 | 0,000 | 1,000 | — | 0,500 |
7. Neden Basit Modeller Kazandı?
Beklenti genellikle tersidir: rastgele ormanın lojistik regresyonu geçmesi beklenir. Burada tam tersi oldu ve sebebi veride.
İlişki zaten doğrusal
Regresyon yazısında gördük: aynı değişkenler satışı doğrusal bir modelle %87 açıklıyor. Doğrusal bir sınır bu problemi çözmeye yetiyor.
Eşik yapay bir sınır
High/Low ayrımı 8 bin adette keyfî olarak çizildi. Sınıra yakın mağazalar ağaç tabanlı yöntemleri zorluyor.
Veri küçük
319 eğitim gözlemi, topluluk yöntemlerinin avantajını göstermesi için az. Rastgele orman veri büyüdükçe fark yaratır.
Ağaçlar eşiği kesemiyor
CART sürekli bir değişkeni basamaklarla böler; sürekli bir eşiği yakalamak doğrusal modelin işi.
Rastgele ormanın profili ayrıca dikkat çekici: özgüllüğü 0,896 ile SVM ile aynı, ama duyarlılığı 0,606. Yani düşük satışlı mağazaları iyi buluyor, yüksek satışlıların üçte birini kaçırıyor. Eğer amaç "yüksek potansiyelli mağazaları tespit etmek" ise bu model, doğruluk sıralamasında ikinci olmasına rağmen iş açısından en kötü seçenek olabilir.
8. Model Karşılaştırmasında Üç Tuzak
| Tuzak | Nasıl oluşur? | Sonucu |
|---|---|---|
| Farklı veri üzerinde ölçmek | Bir model eğitim, diğeri test setinde değerlendirilir. | Karşılaştırma tamamen geçersizdir; eğitimde ölçülen model haksız kazanır. |
| Taban oranı atlamak | Doğruluk tek başına raporlanır. | %60 doğruluk başarı sanılır; oysa hiçbir şey öğrenmemiş olabilir. |
| Tek bölünmeye güvenmek | Sonuç tek bir rastgele eğitim-test ayrımından gelir. | Tohum değişince sıralama değişebilir; fark gürültü olabilir. |
Üçüncüsü bu çalışma için de geçerli: SVM ile lojistik regresyon arasındaki 0,013'lük fark, 81 gözlemlik bir test setinde tek bir mağaza demek. Bu farka dayanarak "SVM daha iyi" demek doğru olmaz. Gerçek bir karşılaştırma için tekrarlı çapraz doğrulama gerekir.
library(caret)

ctrl <- trainControl(method = "repeatedcv", number = 10, repeats = 5,
                     classProbs = TRUE, summaryFunction = twoClassSummary)

modeller <- lapply(c("glm", "svmLinear", "rpart", "rf"), function(m) {
  set.seed(144)
  train(Sales ~ ., data = train, method = m,
        metric = "ROC", trControl = ctrl)
})

summary(resamples(setNames(modeller, c("glm", "svm", "cart", "rf"))))
9. Fark Gerçek mi? Tekrarlı Çapraz Doğrulama
Önceki bölüm bir soruyla kapandı: SVM ile lojistik regresyon arasındaki 0,013'lük fark gerçek mi, gürültü mü? Bu sorunun iki cevabı var ve ikisi de aynı yöne işaret ediyor.
Birinci cevap: McNemar testi
İki model aynı test setinde ölçüldüğünde, doğruluk oranlarını bağımsız örneklermiş gibi karşılaştırmak yanlış olur — ikisi de aynı 81 mağazayı tahmin ediyor. Doğru araç eşleştirilmiş veriler için tasarlanmış McNemar testi. Sorduğu şey şu: bir modelin doğru, diğerinin yanlış bildiği mağazalar dengeli mi dağılmış?
dogru_svm <- pred_svm == test$Sales
dogru_glm <- pred_glm == test$Sales

mcnemar.test(table(dogru_svm, dogru_glm))
# McNemar's chi-squared = 0, df = 1, p-value = 1| Karşılaştırma | Yalnız 1. doğru | Yalnız 2. doğru | χ² | p | Sonuç |
|---|---|---|---|---|---|
| SVM – Lojistik | 1 | 0 | 0,000 | 1,000 | Fark yok |
| SVM – Rastgele orman | 12 | 4 | 3,063 | 0,080 | Sınırda |
| SVM – CART | 16 | 5 | 4,762 | 0,029 | Anlamlı fark |
| Lojistik – Rastgele orman | 11 | 4 | 2,400 | 0,121 | Fark yok |
Sayılar tabloyu bitiriyor: SVM ile lojistik regresyon 81 mağazadan yalnızca birinde farklı karar veriyor. Doğruluk tablosunda SVM'i birinci sıraya koyan şey tek bir mağaza. "SVM daha iyi" cümlesinin arkasında duracak hiçbir kanıt yok. Buna karşılık SVM ile CART arasındaki fark (p = 0,029) gerçek.
İkinci cevap: 5 × 10 katlı çapraz doğrulama
Tek bir bölünme tek bir fotoğraf. Veriyi 10 kata bölüp bunu 5 kez farklı tohumlarla tekrarlarsak elimizde her model için 50 ölçüm olur — ve sıralamanın ne kadar kararlı olduğunu görebiliriz.
# her tekrar icin tabakali 10 kat; 4 model x 50 kat = 200 egitim
for (tekrar in 1:5) {
  set.seed(1000 + tekrar)
  # ... sinif oranlarini koruyarak 10 kata bol ...
  for (k in 1:10) {
    egitim <- df[kat != k, ]; dogrulama <- df[kat == k, ]
    # glm / svm / rpart / randomForest egitilir ve olculur
  }
}| Model | Ortalama doğruluk | Standart sapma | En kötü kat | En iyi kat | Kazandığı kat |
|---|---|---|---|---|---|
| Lojistik regresyon | 0,8886 | 0,0522 | 0,756 | 1,000 | 40 / 50 |
| SVM (doğrusal) | 0,8815 | 0,0515 | 0,756 | 1,000 | 6 / 50 |
| Rastgele orman | 0,8107 | 0,0760 | 0,575 | 0,949 | 4 / 50 |
| CART | 0,7470 | 0,0811 | 0,575 | 0,878 | 0 / 50 |
Sıralama değişti. Tek bölünmede SVM birinciydi; 50 katın ortalamasında lojistik regresyon önde ve 50 katın 40'ında kazanıyor. Eşleştirilmiş t-testi farkı anlamlı buluyor: ortalama fark 0,0071, p = 0,024. Küçük bir fark ama tutarlı.
Alt sıralarda tablo daha net: SVM ile rastgele orman arasındaki 0,071'lik fark p < 0,00001 ile anlamlı. Yani "doğrusal modeller bu veride topluluk yöntemlerini geçiyor" iddiası tek bir bölünmenin kaprisi değil — 50 katta da aynı yönde duruyor.
Sonuç
Dört algoritma aynı veriyle eğitildi, aynı test setinde ölçüldü ve sonuç beklenenin tersi çıktı: doğrusal modeller topluluk yöntemlerini geçti. Bu, "rastgele orman her zaman daha iyidir" varsayımının neden test edilmesi gerektiğini gösteriyor.
Ama asıl ders tek bir tablonun içinde değil, o tabloyu sorgulamakta. Test setindeki sıralama SVM'i birinci gösteriyordu; McNemar testi bu üstünlüğün tek bir mağazadan ibaret olduğunu, 50 katlı çapraz doğrulama ise ortalamada lojistik regresyonun önde olduğunu söyledi. İlk tablo yanlış değildi — yalnızca tek bir bölünmenin fotoğrafıydı.
Bütün modellerin ortak noktası ise daha değerli: fiyat ve raf konumu, hangi algoritmayı kullanırsan kullan en belirleyici iki değişken. Bir bulgu üç farklı yöntemde de ortaya çıkıyorsa, o bulgu modele değil veriye aittir.
“En iyi model, doğruluk tablosunda ilk sırada olan değil; iş probleminin sorduğu soruya en iyi cevabı verendir.”
Four classification algorithms, one data set, one test set. The aim of this post is not to explain each algorithm — I covered them individually elsewhere on the site. The question here is: on the same problem, what does each one do, and why?
In this third post of the series I fit logistic regression, a support vector machine, a decision tree and a random forest on the Carseats data, and compare all four on the same test set with the same metrics.
“Comparing models takes more than training them on the same data; they also have to be measured on the same data.”
1. The Problem and the Base Rate
Sales in Carseats is continuous. To turn this into a classification problem we split it at 8 thousand units: stores above 8 are High, the rest are Low.
df <- Carseats
df$Sales <- factor(ifelse(df$Sales <= 8, "Low", "High"),
                   levels = c("Low", "High"))

table(df$Sales)        # Low 236  High 164

set.seed(5364)
idx <- unlist(lapply(levels(df$Sales), function(lv) {
  rows <- which(df$Sales == lv)
  sample(rows, size = floor(0.8 * length(rows)))
}))

train <- df[idx, ]    # 319 rows: Low 188, High 131
test <- df[-idx, ] # 81 rows: Low 48, High 33Binary class
High (164) / Low (236) — slightly imbalanced but not critically so.
High
All sensitivity and precision figures are computed for the "High" class.
59.3%
The accuracy of a naive model predicting the majority class.
Stratified 80/20
Class ratios preserved in both sets.
2. Logistic Regression
We start with the most interpretable option. Logistic regression passes a linear combination through the sigmoid function to produce a probability.
set.seed(86451)
glm_fit <- glm(Sales ~ ., data = train, family = "binomial")

# "High" is the second level, so the model predicts P(High)
prob <- predict(glm_fit, newdata = test, type = "response")
pred <- factor(ifelse(prob > 0.5, "High", "Low"),
               levels = c("Low", "High"))

table(Prediction = pred, Actual = test$Sales)newdata = test in the predict() call. R then silently predicts on the training data while you believe you are measuring test performance. The order of the factor levels matters too: check with levels() which class the model is modelling.Coefficients:
Estimate Std. Error z value Pr(>|z|)
(Intercept) -5.282068 2.933818 -1.800 0.0718 .
CompPrice 0.192240 0.029544 6.507 7.68e-11 ***
Income 0.030561 0.009737 3.139 0.0017 **
Advertising 0.343855 0.064202 5.356 8.52e-08 ***
Price -0.188692 0.026197 -7.203 5.90e-13 ***
ShelveLocGood 9.076140 1.282961 7.074 1.50e-12 ***
ShelveLocMedium 4.229255 0.805378 5.251 1.51e-07 ***
Age -0.088403 0.018244 -4.846 1.26e-06 ***
Null deviance: 431.99 on 318 degrees of freedom
Residual deviance: 126.34 on 307 degrees of freedom
AIC: 150.34Deviance falls from 431.99 to 126.34: the model gains substantial explanatory power over the null model. The coefficients tell the same story as the regression post — a Good shelving location raises the log-odds of high sales by 9.08.
| Actual | |||
|---|---|---|---|
| Low | High | ||
| Predicted | Low | 42 | 5 |
| High | 6 | 28 | |
Accuracy 0.864 · Sensitivity 0.849 · Specificity 0.875 · F1 0.836 · AUC 0.929
Where does the 0.5 threshold come from?
The confusion matrix above rests on a single decision: call it "High" when the probability passes 0.5. That threshold does not come from the mathematics — it is an assumption. Changing it does not change the model, only how you turn the model's probabilities into decisions.
p <- predict(glm_fit, newdata = test, type = "response")

for (cut in c(0.3, 0.4, 0.5, 0.6, 0.7)) {
  pred <- factor(ifelse(p > cut, "High", "Low"),
                 levels = c("Low", "High"))
  print(table(pred, test$Sales))
}

# Best threshold by Youden's J:
coords(roc(test$Sales, p), "best", best.method = "youden")
# threshold = 0.5924| Threshold | Accuracy | Sensitivity | Specificity | Precision | F1 |
|---|---|---|---|---|---|
| 0.3 | 0.827 | 0.879 | 0.792 | 0.744 | 0.806 |
| 0.4 | 0.852 | 0.849 | 0.854 | 0.800 | 0.824 |
| 0.5 | 0.864 | 0.849 | 0.875 | 0.824 | 0.836 |
| 0.6 | 0.889 | 0.849 | 0.917 | 0.875 | 0.862 |
| 0.7 | 0.840 | 0.727 | 0.917 | 0.857 | 0.787 |
A threshold of 0.6 lifts accuracy from 0.864 to 0.889 — three more stores classified correctly, with no loss in sensitivity. Youden's J on the ROC curve also puts the optimum at 0.592 rather than 0.5.
Where you put it is ultimately a question of cost. If missing a high-potential store costs more than investing in the wrong one, the threshold comes down; if the reverse holds, it goes up.
3. Support Vector Machines
An SVM looks for the boundary that separates the two classes with the widest margin. We start with a linear kernel.
library(e1071)

set.seed(144)
svm_fit <- svm(Sales ~ ., data = train,
               kernel = "linear", cost = 1,
               scale = TRUE, type = "C-classification")

pred_svm <- predict(svm_fit, newdata = test)
table(Prediction = pred_svm, Actual = test$Sales)

svm_fit$tot.nSV   # 89 support vectors
scale = TRUE is essential: SVM is a distance-based method. With Population (10–509) and Advertising (0–29) on different scales, the large-scale variable dominates the boundary. The original study used scale = FALSE; turning scaling on improves the model noticeably.| Actual | |||
|---|---|---|---|
| Low | High | ||
| Predicted | Low | 43 | 5 |
| High | 5 | 28 | |
Accuracy 0.877 · Sensitivity 0.849 · Specificity 0.896 · F1 0.849 — the highest accuracy of the four.
cost and kernel: should we keep the defaults?
The model above was fitted with cost = 1 and a linear kernel — both default choices. cost controls how much margin violation the SVM tolerates: a small value buys a wide but forgiving margin, a large value a narrow and strict boundary. The right value depends on the data, so it has to be searched for.
set.seed(144)
t1 <- tune(svm, Sales ~ ., data = train, kernel = "linear",
          ranges = list(cost = c(0.01, 0.1, 1, 5, 10)))
t1$performances

t2 <- tune(svm, Sales ~ ., data = train, kernel = "radial",
          ranges = list(cost = c(0.1, 1, 5, 10),
                        gamma = c(0.01, 0.05, 0.1)))
t2$best.parameters # cost = 5, gamma = 0.05| cost | CV error | Dispersion (sd) |
|---|---|---|
| 0.01 | 0.1627 | 0.0774 |
| 0.10 | 0.1065 | 0.0573 |
| 1.00 | 0.1128 | 0.0446 |
| 5.00 | 0.1191 | 0.0459 |
| 10.00 | 0.1128 | 0.0513 |
The best cost is 0.1 rather than 1 — but the gap is only 0.006 against a fold-to-fold standard deviation of 0.057. So the search is not telling us to change cost; it is telling us that cost barely matters across a wide range in this dataset. The one exception is 0.01: too loose a margin clearly degrades the model.
| Kernel | Best parameters | CV error | Support vectors | Test accuracy |
|---|---|---|---|---|
| Linear | cost = 0.1 | 0.1065 | 89 | 0.877 |
| Radial (RBF) | cost = 5, gamma = 0.05 | 0.1066 | 128 | 0.827 |
The radial kernel can draw non-linear boundaries and is usually treated as the "stronger" option. Here its cross-validated error is all but identical (0.1066 against 0.1065) and its test accuracy is five points lower. It also leans on 128 support vectors instead of 89 — doing the same job with a more complicated model.
4. Decision Tree (CART)
CART splits the data through successive binary partitions. Its biggest advantage is readability: you can see the model as a series of if–then rules.
library(rpart)
library(rpart.plot)

set.seed(144)
cart_fit <- rpart(Sales ~ ., data = train, method = "class")

# The cp that minimizes cross-validated error
printcp(cart_fit)
best_cp <- cart_fit$cptable[which.min(cart_fit$cptable[, "xerror"]), "CP"]

cart_pruned <- prune(cart_fit, cp = best_cp)
rpart.plot(cart_pruned) CP nsplit rel error xerror xstd
1 0.32061069 0 1.0000000 1.0000000 0.06707303
2 0.07633588 1 0.6793893 0.6793893 0.06114941
3 0.05343511 2 0.6030534 0.7557252 0.06307573
4 0.03816794 4 0.4961832 0.6335878 0.05981752
5 0.02798982 6 0.4198473 0.5877863 0.05834268
6 0.02290076 9 0.3358779 0.5648855 0.05754827 <- lowest xerror
7 0.01000000 11 0.2900763 0.5725191 0.05781745Two columns tell the story: rel error is the training error and keeps falling as the tree grows (1.00 → 0.29). xerror is the cross-validated error, and after nine splits it starts rising again. That is where overfitting begins. We take the cp = 0.0229 with the lowest xerror and prune the tree to 10 leaves.
| Actual | |||
|---|---|---|---|
| Low | High | ||
| Predicted | Low | 38 | 11 |
| High | 10 | 22 | |
Accuracy 0.741 · Sensitivity 0.667 · Specificity 0.792 · F1 0.677 · AUC 0.769 — the weakest of the four.
5. Random Forest
A random forest trains hundreds of decision trees on different samples and variable subsets, then combines their votes. It largely removes the instability of a single tree.
library(randomForest)

set.seed(144)
rf_fit <- randomForest(Sales ~ ., data = train, importance = TRUE)
rf_fit

# OOB estimate of error rate: 17.55%
# Confusion matrix (OOB):
#      Low High class.error
# Low  171   17   0.0904
# High  39   92   0.2977

pred_rf <- predict(rf_fit, newdata = test)
importance(rf_fit)[, "MeanDecreaseGini"]
The out-of-bag (OOB) error is a random forest's built-in cross-validation: each tree is tested on the observations left out while it was trained. The 17.55% OOB error here is an estimate obtained without setting aside a separate validation set.
| Variable | MeanDecreaseGini |
|---|---|
| Price | 34.04 |
| ShelveLoc | 27.46 |
| Age | 18.69 |
| Advertising | 18.44 |
| CompPrice | 16.82 |
| Income | 13.52 |
The importance ranking matches what the regression model said: price and shelving location are far ahead. Three different methods highlighting the same two variables suggests the finding belongs to the data, not to the method.
| Actual | |||
|---|---|---|---|
| Low | High | ||
| Predicted | Low | 43 | 13 |
| High | 5 | 20 | |
Accuracy 0.778 · Sensitivity 0.606 · Specificity 0.896 · F1 0.690 · AUC 0.878
6. Four Models, One Table
Every model was trained on the same training set and measured on the same 81-observation test set. The positive class is "High".
| Model | Accuracy | Sensitivity | Specificity | F1 | AUC |
|---|---|---|---|---|---|
| SVM (linear) | 0.877 | 0.849 | 0.896 | 0.849 | 0.926 |
| Logistic regression | 0.864 | 0.849 | 0.875 | 0.836 | 0.929 |
| Random forest | 0.778 | 0.606 | 0.896 | 0.690 | 0.878 |
| CART | 0.741 | 0.667 | 0.792 | 0.677 | 0.769 |
| Base rate | 0.593 | 0.000 | 1.000 | — | 0.500 |
7. Why Did the Simple Models Win?
The expectation usually runs the other way: a random forest is supposed to beat logistic regression. Here the opposite happened, and the reason lies in the data.
The relationship is already linear
We saw it in the regression post: the same variables explain 87% of sales with a linear model. A linear boundary is enough for this problem.
The threshold is artificial
The High/Low split was drawn arbitrarily at 8 thousand units. Stores near the boundary are hard for tree-based methods.
The data is small
319 training rows is little for ensembles to show their advantage. Random forests pull ahead as data grows.
Trees cannot cut a smooth threshold
CART splits a continuous variable into steps; catching a smooth threshold is a linear model's job.
The random forest's profile is also notable: its specificity of 0.896 matches the SVM, but its sensitivity is 0.606. It finds low-selling stores well and misses a third of the high-selling ones. If the goal is "identify high-potential stores", this model may be the worst business choice despite ranking second on accuracy.
8. Three Pitfalls in Model Comparison
| Pitfall | How it happens | The consequence |
|---|---|---|
| Measuring on different data | One model is evaluated on training, another on test. | The comparison is void; the one measured on training wins unfairly. |
| Ignoring the base rate | Accuracy is reported on its own. | 60% accuracy looks like success when nothing was learned. |
| Trusting a single split | The result comes from one random train/test partition. | The ranking can change with the seed; the gap may be noise. |
The third applies to this study too: the 0.013 gap between the SVM and logistic regression amounts to a single store in an 81-observation test set. Declaring "the SVM is better" on that basis would be wrong. A real comparison needs repeated cross-validation.
library(caret)

ctrl <- trainControl(method = "repeatedcv", number = 10, repeats = 5,
                     classProbs = TRUE, summaryFunction = twoClassSummary)

models <- lapply(c("glm", "svmLinear", "rpart", "rf"), function(m) {
  set.seed(144)
  train(Sales ~ ., data = train, method = m,
        metric = "ROC", trControl = ctrl)
})

summary(resamples(setNames(models, c("glm", "svm", "cart", "rf"))))
9. Is the Difference Real? Repeated Cross-Validation
The previous section closed on a question: is the 0.013 gap between SVM and logistic regression real, or noise? There are two ways to answer it, and both point the same way.
First answer: McNemar's test
When two models are measured on the same test set, comparing their accuracies as if they were independent samples is wrong — both are predicting the same 81 stores. The right tool is McNemar's test, built for paired data. The question it asks is: are the stores one model gets right and the other gets wrong balanced between them?
right_svm <- pred_svm == test$Sales
right_glm <- pred_glm == test$Sales

mcnemar.test(table(right_svm, right_glm))
# McNemar's chi-squared = 0, df = 1, p-value = 1| Comparison | Only 1st right | Only 2nd right | χ² | p | Verdict |
|---|---|---|---|---|---|
| SVM – Logistic | 1 | 0 | 0.000 | 1.000 | No difference |
| SVM – Random forest | 12 | 4 | 3.063 | 0.080 | Borderline |
| SVM – CART | 16 | 5 | 4.762 | 0.029 | Real difference |
| Logistic – Random forest | 11 | 4 | 2.400 | 0.121 | No difference |
The numbers settle the table: SVM and logistic regression disagree on exactly one of the 81 stores. What puts SVM at the top of the accuracy ranking is a single store. There is no evidence to stand behind the sentence "SVM is better". The gap between SVM and CART (p = 0.029), by contrast, is real.
Second answer: 5 × 10-fold cross-validation
A single split is a single photograph. Splitting the data into 10 folds and repeating that 5 times with different seeds gives 50 measurements per model — enough to see how stable the ranking actually is.
# stratified 10 folds per repeat; 4 models x 50 folds = 200 fits
for (rep in 1:5) {
  set.seed(1000 + rep)
  # ... split into 10 folds preserving class ratios ...
  for (k in 1:10) {
    tr <- df[fold != k, ]; va <- df[fold == k, ]
    # glm / svm / rpart / randomForest are fitted and scored
  }
}| Model | Mean accuracy | Std. deviation | Worst fold | Best fold | Folds won |
|---|---|---|---|---|---|
| Logistic regression | 0.8886 | 0.0522 | 0.756 | 1.000 | 40 / 50 |
| SVM (linear) | 0.8815 | 0.0515 | 0.756 | 1.000 | 6 / 50 |
| Random forest | 0.8107 | 0.0760 | 0.575 | 0.949 | 4 / 50 |
| CART | 0.7470 | 0.0811 | 0.575 | 0.878 | 0 / 50 |
The ranking flips. SVM was first on the single split; averaged over 50 folds, logistic regression leads and wins 40 of them. A paired t-test finds the difference significant: mean gap 0.0071, p = 0.024. Small, but consistent.
Further down the table the picture is sharper: the 0.071 gap between SVM and random forest is significant at p < 0.00001. So the claim that linear models beat the ensembles on this data is not the whim of one split — it holds across 50 folds.
Conclusion
Four algorithms were trained on the same data and measured on the same test set, and the result ran against expectation: the linear models beat the ensembles. That is why the assumption "a random forest is always better" has to be tested rather than believed.
But the real lesson is not inside a single table — it is in questioning that table. The test-set ranking put SVM first; McNemar's test showed that lead amounted to one store, and 50-fold cross-validation put logistic regression ahead on average. The first table was not wrong. It was a photograph of one split.
What all the models share is more valuable still: price and shelving location are the two decisive variables whichever algorithm you use. When a finding shows up in three different methods, it belongs to the data rather than the model.
“The best model is not the one at the top of the accuracy table; it is the one that best answers the question the business is asking.”