R ile Makine Öğrenmesi: Veri Hazırlığı ve Keşif
Model kurmadan önce ne yapılır? Eksik gözlem analizi, dağılım kontrolü, normallik testleri ve tabakalı eğitim-test ayrımını gerçek bir veri seti üzerinde ele alıyorum.
- Makine Öğrenmesi
- Araçlar
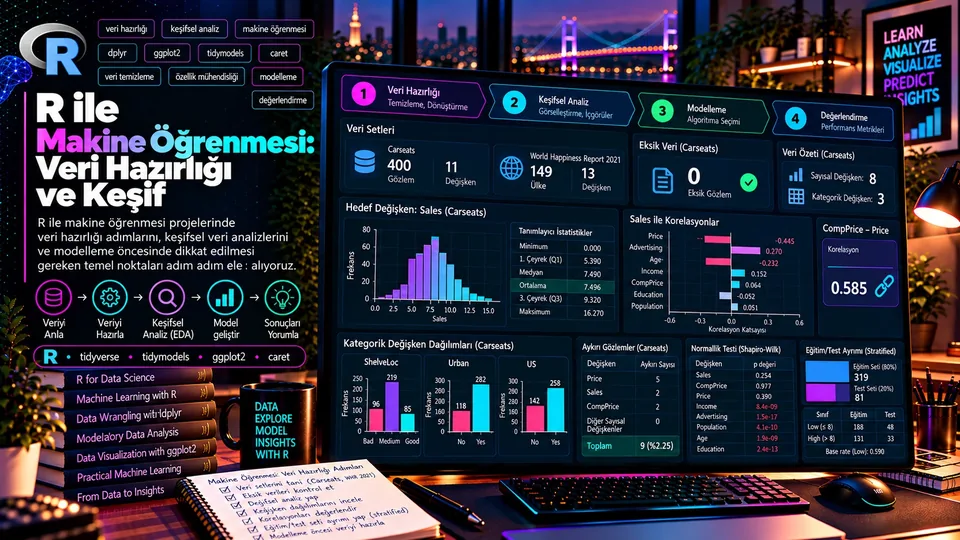
Makine öğrenmesi yazılarının çoğu modelden başlar. Oysa bir projede harcanan zamanın büyük bölümü model kurmadan önce geçer: veriyi tanımak, eksikleri bulmak, değişkenlerin nasıl dağıldığını görmek ve veriyi eğitim ile test olarak ayırmak.
Bu yazı dört bölümlük bir serinin ilki. Seri boyunca iki gerçek veri seti üzerinde çalışacağız: Carseats (400 mağazanın çocuk oto koltuğu satışları) ve World Happiness Report 2021 (149 ülkenin mutluluk skorları). Bu ilk yazıda modele hiç girmeden önce yapılması gerekenleri ele alıyorum.
“Model kurmadan önce verinin ne olduğunu bilmiyorsan, kurduğun şey bir model değil; bir tahmindir.”
1. İki Veri Seti
Seri boyunca iki veri seti kullanıyorum. İkisi de açık, ikisi de küçük; yani makinende aynı sonuçları üretebilirsin.
Carseats
400 mağaza, 11 değişken. An Introduction to Statistical Learning kitabının ISLR paketinden geliyor. Regresyonda hedef Sales, sınıflandırmada aynı değişkenin ikili hali.
World Happiness 2021
149 ülke, 13 değişken. Mutluluk skoru, kişi başı GSYİH, sosyal destek, sağlıklı yaşam beklentisi gibi göstergeler. Kümeleme ve PCA için kullanacağız.
| Değişken | Tür | Anlamı |
|---|---|---|
Sales | Sayısal | Mağaza başına satış (bin adet) — regresyonun hedefi |
CompPrice | Sayısal | Rakibin aynı lokasyondaki fiyatı |
Income | Sayısal | Bölgenin gelir düzeyi (bin $) |
Advertising | Sayısal | Yerel reklam bütçesi (bin $) |
Population | Sayısal | Bölge nüfusu (bin) |
Price | Sayısal | Ürünün mağazadaki fiyatı |
ShelveLoc | Kategorik | Raf konumu: Bad / Medium / Good |
Age | Sayısal | Bölgedeki ortalama nüfus yaşı |
Education | Sayısal | Bölgedeki eğitim düzeyi |
Urban, US | Kategorik | Mağaza kentsel mi, ABD'de mi |
library(tidyverse)
library(ISLR)

data(Carseats)
dim(Carseats)      # 400  11
str(Carseats)
summary(Carseats$Sales) Min. 1st Qu. Median Mean 3rd Qu. Max.
0.000 5.390 7.490 7.496 9.320 16.270Ortalama ile medyanın birbirine bu kadar yakın olması (7,496 ve 7,49) ilk ipucunu veriyor: Sales simetriğe yakın dağılıyor. Bunu birazdan sayıyla doğrulayacağız.
2. Eksik Gözlem Analizi
Eksik veri kontrolü, modelleme öncesi atlanmaması gereken ilk adım. R'da bunun için birkaç pratik yol var.
# En hizli yol: toplam ve sutun bazinda
sum(is.na(Carseats))                 # 0
colSums(is.na(Carseats))

# Gorsel olarak
library(VIM)
aggr(Carseats, numbers = TRUE, sortVars = TRUE)

library(Amelia)
missmap(Carseats)
Carseats'te hiç eksik gözlem yok — ders kitabından gelen temiz bir veri seti olduğu için beklenen bir sonuç. Gerçek projelerde durum böyle olmaz; o yüzden eksikliğin nasıl ele alınacağı kadar neden oluştuğu da önemli.
| Eksiklik türü | Ne demek? | Yaklaşım |
|---|---|---|
| MCAR — tamamen rastgele | Eksiklik hiçbir değişkenle ilişkili değil. | Silmek görece güvenli; veri kaybı tek maliyet. |
| MAR — gözlenene bağlı rastgele | Eksiklik başka bir değişkenle açıklanabiliyor. | Model tabanlı doldurma (örn. mice) uygun olabilir. |
| MNAR — rastgele değil | Eksiklik, eksik olan değerin kendisine bağlı. | En zoru; eksikliği ayrı bir bilgi olarak modellemek gerekebilir. |
3. Veriyi Keşfetmek
Sayısal özet kadar kategorik değişkenlerin dağılımı da önemli. Dengesiz bir kategori, hem modelin öğrenmesini hem de sonradan yapacağın tabakalı bölmeyi etkiler.
table(Carseats$ShelveLoc)
table(Carseats$Urban)
table(Carseats$US)| Değişken | Dağılım | Not |
|---|---|---|
ShelveLoc | Bad 96 · Medium 219 · Good 85 | Orta kategori baskın; uç kategoriler benzer büyüklükte. |
Urban | No 118 · Yes 282 | Mağazaların %70,5'i kentsel. |
US | No 142 · Yes 258 | %64,5 ABD içinde. |
Değişkenler birbiriyle nasıl ilişkili?
Tek tek dağılımlar kadar önemli olan bir şey daha var: değişkenlerin birbirine göre nasıl durduğu. Korelasyon matrisi hem hedefe en yakın değişkenleri gösterir hem de modelde sorun çıkarabilecek bağımlılıkları önceden haber verir.
sayisal <- Carseats[sapply(Carseats, is.numeric)]
ko <- cor(sayisal)

round(sort(ko[, "Sales"], decreasing = TRUE), 3)

# corrplot ile gorsellestirme:
library(corrplot)
corrplot(ko, method = "color", type = "upper", addCoef.col = "black")Tek bir değişken bile 0,5'i geçmiyor; en güçlü ilişki Price ile ve o bile −0,445. Bu, tek değişkenli bakışın yetersiz olduğunun ilk işareti. Regresyon yazısında aynı değişkenlerin birlikte satışın %87'sini açıkladığını göreceğiz — yani asıl bilgi değişkenlerin tek başına değil, bir arada taşıdığı şeyde.
Bağımsız değişkenler arasındaki ilişkilere de bakmak gerekiyor:
| Değişken çifti | Korelasyon | Yorum |
|---|---|---|
CompPrice – Price | 0,585 | Beklenen: rakip fiyatını artırınca mağaza da artırıyor. Tek dikkat çeken ilişki. |
Advertising – Population | 0,266 | Büyük bölgelere daha çok reklam bütçesi ayrılıyor. |
Population – Education | −0,106 | İhmal edilebilir. |
Price – Age | −0,102 | İhmal edilebilir. |
Price ve CompPrice katsayılarının birlikte hareket etmesini beklemek doğru olur.Aykırı değerler: var mı, silinmeli mi?
Aykırı değer analizi genellikle "bulduğunu sil" olarak uygulanıyor ve bu çoğu zaman yanlış. Önce ne kadar aykırı değer olduğunu görmek gerekiyor.
for (v in names(sayisal)) {
  x <- sayisal[[v]]
  q <- quantile(x, c(.25, .75)); i <- IQR(x)
  cat(v, sum(x < q[1] - 1.5*i | x > q[2] + 1.5*i), "\n")
}| Değişken | Alt sınır | Üst sınır | Aykırı sayısı |
|---|---|---|---|
Price | 53,5 | 177,5 | 5 (3 düşük, 2 yüksek) |
Sales | −0,50 | 15,21 | 2 (15,63 ve 16,27) |
CompPrice | 85,0 | 165,0 | 2 |
Income, Advertising, Population, Age, Education | — | 0 | |
400 gözlemde toplam dokuz aykırı değer, yani %2,25. Üstelik hiçbiri fiziksel olarak imkânsız değil: 16,27 bin adet satan bir mağaza mümkün, 177'nin üzerinde fiyatlanmış bir ürün de. Bunlar veri hatası değil, dağılımın uçları.
Hangi grafiğin hangi soruya cevap verdiği konusunu ayrı bir yazıda ele almıştım; burada tekrar etmek yerine kısa bir eşleme bırakıyorum.
Histogram
Tek bir sayısal değişkenin hangi aralıklarda yoğunlaştığını gösterir.
Kutu grafiği
Medyan, çeyrekler ve aykırı değerler; gruplar arası karşılaştırma için ideal.
Saçılım
İki sayısal değişken arasındaki ilişkinin yönü ve biçimi.
Korelasyon matrisi
Bütün sayısal değişkenlerin ikili ilişkilerine tek bakışta görmek.
4. Normallik, Çarpıklık ve Basıklık
Doğrusal regresyonun varsayımı değişkenlerin kendisinin değil, hata teriminin normal dağılmasıdır. Yine de değişkenlerin dağılımını baştan bilmek, hangi dönüşümün gerekebileceğini ve hangi grafiğin yanıltabileceğini önceden gösterir.
carpiklik <- function(x) mean((x - mean(x))^3) / sd(x)^3
basiklik  <- function(x) mean((x - mean(x))^4) / sd(x)^4

sayisal <- Carseats[sapply(Carseats, is.numeric)]

for (v in names(sayisal)) {
  sw <- shapiro.test(sayisal[[v]])
  cat(sprintf("%-12s carpiklik=%6.3f basiklik=%6.3f W=%.4f p=%.4g\n",
              v, carpiklik(sayisal[[v]]), basiklik(sayisal[[v]]),
              sw$statistic, sw$p.value))
}| Değişken | Çarpıklık | Basıklık | Shapiro-Wilk W | p | Sonuç |
|---|---|---|---|---|---|
| Sales | 0,184 | 2,891 | 0,9952 | 0,254 | Normallik reddedilemez |
| CompPrice | −0,042 | 3,011 | 0,9984 | 0,977 | Normallik reddedilemez |
| Price | −0,124 | 3,414 | 0,9959 | 0,390 | Normallik reddedilemez |
| Income | 0,049 | 1,904 | 0,9611 | 8,4e−09 | Normal değil (basık) |
| Advertising | 0,635 | 2,434 | 0,8735 | 1,5e−17 | Normal değil (sağa çarpık) |
| Population | −0,051 | 1,789 | 0,9520 | 4,1e−10 | Normal değil (basık) |
| Age | −0,077 | 1,855 | 0,9567 | 1,9e−09 | Normal değil (basık) |
| Education | 0,044 | 1,694 | 0,9242 | 2,4e−13 | Normal değil (basık) |
Tabloda dikkat çeken şey şu: çarpıklık değerleri sıfıra çok yakın olduğu hâlde beş değişken için normallik reddediliyor. Sebep basıklıkta: Income, Population, Age ve Education için basıklık 1,7–1,9 bandında, yani normal dağılımın 3 değerinin belirgin biçimde altında. Bunlar simetrik ama fazla basık, neredeyse düzgün (uniform) dağılıma yakın değişkenler. Simetri tek başına normallik demek değil.
5. Veriyi Eğitim ve Test Olarak Ayırmak
Bir modelin başarısını onu eğittiğin veriyle ölçersen, sonuç her zaman olduğundan iyi çıkar. Model o satırları zaten görmüştür. Gerçek performans, modelin hiç görmediği veriyle ölçülür.
- Tüm veri400 gözlem
- Böl%80 / %20
- EğitModel yalnızca eğitimi görür
- Test etGörülmemiş veri
- KararGerçekçi performans
Sınıflandırmada basit rastgele bölme yeterli olmayabilir. Sınıfların oranı eğitim ve test setinde korunmazsa, karşılaştırmalar bozulur. Bunun çözümü tabakalı (stratified) bölme: her sınıftan aynı oranda örnek almak.
df <- Carseats
df$Sales <- factor(ifelse(df$Sales <= 8, "Low", "High"),
                   levels = c("Low", "High"))

set.seed(5364)
idx <- unlist(lapply(levels(df$Sales), function(lv) {
  satirlar <- which(df$Sales == lv)
  sample(satirlar, size = floor(0.8 * length(satirlar)))
}))

train <- df[idx, ]
test  <- df[-idx, ]

table(train$Sales)   # Low 188  High 131
table(test$Sales)    # Low  48  High  33
Aynı işi caret paketindeki createDataPartition() de yapar; yukarıdaki açık yazım, arkada ne olduğunu göstermek için. Sonuç: 319 eğitim, 81 test gözlemi ve her iki sette de yaklaşık %59 Low / %41 High oranı.
Eşiği 8'e koymak masum bir karar mı?
Sınıflandırma için Sales değişkenini 8 bin adette ikiye böldük. Bu sayı veriden gelmiyor, bizden geliyor — ve taban oranı doğrudan belirliyor.
| Eşik | Low | High | Taban oran | Modelin aşması gereken çıta |
|---|---|---|---|---|
| 7,0 | 184 | 216 | 0,540 | Düşük — model kolayca geçer |
| 7,5 | 202 | 198 | 0,505 | En dengeli bölünme |
| 8,0 (seçilen) | 236 | 164 | 0,590 | Orta |
| 8,5 | 257 | 143 | 0,643 | Yüksek |
| 9,0 | 287 | 113 | 0,718 | Çok yüksek — dengesiz sınıf sorunu başlar |
Eşiği 7,5'e çekseydik taban oran %50,5 olurdu ve "%60 doğruluk" gerçekten bir başarı sayılırdı. 9'a çekseydik taban oran %71,8'e çıkar, aynı doğruluk değeri başarısızlık anlamına gelirdi. Yani doğruluk rakamı tek başına değil, hangi eşikle üretildiğiyle birlikte okunmalı.
İkinci bir mesele daha var: eşiğe yakın mağazalar. Sales değeri 7,5 ile 8,5 arasında olan 56 mağaza var — veri setinin %14'ü. Bu mağazalar "High" ile "Low" arasında anlamlı bir fark taşımıyor; yalnızca çizginin hangi tarafına düştükleri farklı.
set.seed() neden şart? Bölme rastgele; tohum sabitlenmezse her çalıştırmada farklı bir eğitim-test ayrımı ve farklı bir doğruluk elde edersin. Sonuçların tekrar üretilebilir olması için tohum mutlaka sabitlenmeli ve raporda belirtilmeli.6. Veri Sızıntısından Kaçınmak
Veri sızıntısı (data leakage), test setine ait bilginin modele farkında olmadan taşınmasıdır. Sonuç her zaman aynı: model raporda harika, gerçek hayatta vasat görünür.
| Sızıntı | Nasıl oluşur? | Doğrusu |
|---|---|---|
| Ölçekleme | Ortalama ve standart sapma tüm veriden hesaplanır. | Parametreler yalnızca eğitimden öğrenilir, teste uygulanır. |
| Eksik doldurma | Medyan tüm veri üzerinden alınır. | Eğitim medyanı hesaplanır, test aynı değerle doldurulur. |
| Değişken seçimi | En iyi değişkenler tüm veriye bakılarak seçilir. | Seçim yalnızca eğitim verisiyle yapılır. |
| Hedeften türetme | Hedefi içeren bir değişken modelde kalır. | Hedeften türeyen alanlar modelden çıkarılır. |
| Zaman serisi | Gelecek tarihli satırlar eğitime girer. | Bölme zamana göre yapılır, rastgele değil. |
Bu serideki sınıflandırma örneğinde gizli bir sızıntı riski vardı: Sales değişkeni ikiliye çevrilirken orijinal sayısal sütunun üzerine yazılması gerekiyor. Sayısal Sales veri setinde kalsaydı model hedefi doğrudan okur ve %100 doğruluk üretirdi.
7. Modele Geçmeden Önce Kontrol Listesi
Boyut ve tipler
Kaç satır, kaç sütun? Kategorik alanlar faktör olarak mı okundu?
Eksik gözlem
Nerede, ne kadar ve neden eksik? Doldurma bölmeden sonra mı yapılıyor?
Dağılımlar
Çarpıklık, basıklık ve aykırı değerler incelendi mi?
Hedef değişken
Sınıflar dengeli mi? Taban oran ne? Doğruluk bunu geçebilecek mi?
Bölme
Tabakalı mı? Tohum sabit mi? Oranlar iki sette de korunuyor mu?
Sızıntı
Ölçekleme, doldurma ve değişken seçimi yalnızca eğitimden mi öğreniliyor?
Sonuç
Bu yazıda tek bir model kurmadık ama bir sonraki adımın bütün zeminini hazırladık: veriyi tanıdık, eksik olmadığını doğruladık, değişkenlerin dağılımını ölçtük ve veriyi tekrar üretilebilir biçimde eğitim-test olarak ayırdık.
Burada elde ettiğimiz iki bilgi sonraki yazılarda doğrudan işimize yarayacak: Sales, CompPrice ve Price normal dağılıma uygun; sınıflandırmada taban oran yaklaşık %59. İkinci sayı özellikle önemli — çünkü bir modelin %60 doğruluk üretmesi, hiçbir şey öğrenmediği anlamına gelebilir.
“İyi bir model, iyi hazırlanmış veriyle başlar; iyi bir değerlendirme ise veriyi doğru böldüğün anda.”
Most machine learning articles start with the model. Yet in a real project most of the time is spent before any model exists: getting to know the data, finding what is missing, seeing how the variables are distributed, and splitting the data into training and test sets.
This is the first of a four-part series. Throughout the series we work with two real data sets: Carseats (child car seat sales at 400 stores) and the World Happiness Report 2021 (happiness scores for 149 countries). In this first post I cover everything that has to happen before a single model is fitted.
“If you do not know what the data is before you fit a model, what you built is not a model — it is a guess.”
1. Two Data Sets
Two data sets run through the whole series. Both are open and both are small, so you can reproduce every result on your own machine.
Carseats
400 stores, 11 variables, from the ISLR package that accompanies An Introduction to Statistical Learning. The regression target is Sales; for classification we use a binary version of the same variable.
World Happiness 2021
149 countries, 13 variables: happiness score, GDP per capita, social support, healthy life expectancy and more. We use it for clustering and PCA.
| Variable | Type | Meaning |
|---|---|---|
Sales | Numeric | Unit sales per store (thousands) — the regression target |
CompPrice | Numeric | Competitor's price at the same location |
Income | Numeric | Community income level (thousand $) |
Advertising | Numeric | Local advertising budget (thousand $) |
Population | Numeric | Regional population (thousands) |
Price | Numeric | Price charged at the store |
ShelveLoc | Categorical | Shelving location: Bad / Medium / Good |
Age | Numeric | Average age of the local population |
Education | Numeric | Education level at the location |
Urban, US | Categorical | Whether the store is urban, and whether it is in the US |
library(tidyverse)
library(ISLR)

data(Carseats)
dim(Carseats)      # 400  11
str(Carseats)
summary(Carseats$Sales) Min. 1st Qu. Median Mean 3rd Qu. Max.
0.000 5.390 7.490 7.496 9.320 16.270The mean and the median being this close (7.496 and 7.49) is the first clue: Sales is close to symmetric. We will confirm that with a number shortly.
2. Missing Data Analysis
Checking for missing data is the first step that must not be skipped before modelling. R offers several practical ways to do it.
# Quickest: total and per column
sum(is.na(Carseats))                 # 0
colSums(is.na(Carseats))

# Visually
library(VIM)
aggr(Carseats, numbers = TRUE, sortVars = TRUE)

library(Amelia)
missmap(Carseats)
Carseats has no missing values at all — expected for a clean textbook data set. Real projects are rarely like this, which is why why a value is missing matters as much as how you handle it.
| Type of missingness | What it means | Approach |
|---|---|---|
| MCAR — completely at random | Missingness is unrelated to any variable. | Deleting rows is relatively safe; losing data is the only cost. |
| MAR — at random given observed data | Missingness can be explained by another variable. | Model-based imputation (e.g. mice) may be appropriate. |
| MNAR — not at random | Missingness depends on the missing value itself. | The hardest case; missingness may need to be modelled as information. |
3. Exploring the Data
The distribution of the categorical variables matters as much as the numeric summary. An imbalanced category affects both what the model can learn and the stratified split you will do later.
table(Carseats$ShelveLoc)
table(Carseats$Urban)
table(Carseats$US)| Variable | Distribution | Note |
|---|---|---|
ShelveLoc | Bad 96 · Medium 219 · Good 85 | The middle category dominates; the extremes are similar in size. |
Urban | No 118 · Yes 282 | 70.5% of stores are urban. |
US | No 142 · Yes 258 | 64.5% are inside the US. |
How are the variables related to each other?
Individual distributions matter, but so does how the variables sit relative to one another. A correlation matrix shows which variables are closest to the target and warns early about dependencies that could cause trouble in the model.
numeric_cols <- Carseats[sapply(Carseats, is.numeric)]
co <- cor(numeric_cols)

round(sort(co[, "Sales"], decreasing = TRUE), 3)

# visualised with corrplot:
library(corrplot)
corrplot(co, method = "color", type = "upper", addCoef.col = "black")Not one variable clears 0.5; the strongest relationship is with Price and even that is −0.445. This is the first sign that a univariate view is not enough. In the regression post we will see these same variables explain 87% of sales together — the information lives in the combination, not in any single column.
The relationships among the predictors deserve a look as well:
| Variable pair | Correlation | Reading |
|---|---|---|
CompPrice – Price | 0.585 | As expected: when the competitor raises prices, the store follows. The only notable relationship. |
Advertising – Population | 0.266 | Larger regions get larger advertising budgets. |
Population – Education | −0.106 | Negligible. |
Price – Age | −0.102 | Negligible. |
Price and CompPrice coefficients to move together in the model.Outliers: are there any, and should they go?
Outlier analysis is often applied as "find them and delete them", which is usually wrong. The first step is simply to see how many there are.
for (v in names(numeric_cols)) {
  x <- numeric_cols[[v]]
  q <- quantile(x, c(.25, .75)); i <- IQR(x)
  cat(v, sum(x < q[1] - 1.5*i | x > q[2] + 1.5*i), "\n")
}| Variable | Lower bound | Upper bound | Outliers |
|---|---|---|---|
Price | 53.5 | 177.5 | 5 (3 low, 2 high) |
Sales | −0.50 | 15.21 | 2 (15.63 and 16.27) |
CompPrice | 85.0 | 165.0 | 2 |
Income, Advertising, Population, Age, Education | — | 0 | |
Nine outliers across 400 observations — 2.25%. None of them is physically impossible either: a store selling 16,270 units is plausible, and so is a product priced above 177. These are not data errors, they are the tails of the distribution.
Which chart answers which question is a topic I covered in a separate post; instead of repeating it, here is a short mapping.
Histogram
Shows where a single numeric variable concentrates.
Box plot
Median, quartiles and outliers; ideal for comparing groups.
Scatter plot
The direction and shape of the relationship between two numeric variables.
Correlation matrix
All pairwise relationships among the numeric variables at a glance.
4. Normality, Skewness and Kurtosis
The assumption in linear regression is that the error term is normally distributed, not the variables themselves. Still, knowing the distributions up front tells you which transformation might be needed and which chart could mislead you.
skewness <- function(x) mean((x - mean(x))^3) / sd(x)^3
kurtosis <- function(x) mean((x - mean(x))^4) / sd(x)^4

numeric_vars <- Carseats[sapply(Carseats, is.numeric)]

for (v in names(numeric_vars)) {
  sw <- shapiro.test(numeric_vars[[v]])
  cat(sprintf("%-12s skew=%6.3f kurt=%6.3f W=%.4f p=%.4g\n",
              v, skewness(numeric_vars[[v]]), kurtosis(numeric_vars[[v]]),
              sw$statistic, sw$p.value))
}| Variable | Skewness | Kurtosis | Shapiro-Wilk W | p | Conclusion |
|---|---|---|---|---|---|
| Sales | 0.184 | 2.891 | 0.9952 | 0.254 | Normality not rejected |
| CompPrice | −0.042 | 3.011 | 0.9984 | 0.977 | Normality not rejected |
| Price | −0.124 | 3.414 | 0.9959 | 0.390 | Normality not rejected |
| Income | 0.049 | 1.904 | 0.9611 | 8.4e−09 | Not normal (flat) |
| Advertising | 0.635 | 2.434 | 0.8735 | 1.5e−17 | Not normal (right-skewed) |
| Population | −0.051 | 1.789 | 0.9520 | 4.1e−10 | Not normal (flat) |
| Age | −0.077 | 1.855 | 0.9567 | 1.9e−09 | Not normal (flat) |
| Education | 0.044 | 1.694 | 0.9242 | 2.4e−13 | Not normal (flat) |
One thing stands out: although the skewness values are very close to zero, normality is rejected for five variables. The reason is kurtosis. For Income, Population, Age and Education it sits between 1.7 and 1.9, clearly below the value of 3 for a normal distribution. These variables are symmetric but far too flat — close to a uniform distribution. Symmetry alone does not mean normality.
5. Splitting into Training and Test Sets
If you measure a model with the data it was trained on, the result always looks better than it is — the model has already seen those rows. Real performance is measured on data the model has never seen.
- All data400 observations
- Split80% / 20%
- TrainModel sees training only
- TestUnseen data
- DecideRealistic performance
For classification a plain random split may not be enough. If the class ratio is not preserved in both sets, comparisons break down. The fix is a stratified split: sampling the same proportion from each class.
df <- Carseats
df$Sales <- factor(ifelse(df$Sales <= 8, "Low", "High"),
                   levels = c("Low", "High"))

set.seed(5364)
idx <- unlist(lapply(levels(df$Sales), function(lv) {
  rows <- which(df$Sales == lv)
  sample(rows, size = floor(0.8 * length(rows)))
}))

train <- df[idx, ]
test  <- df[-idx, ]

table(train$Sales)   # Low 188  High 131
table(test$Sales)    # Low  48  High  33
createDataPartition() from the caret package does the same job; the explicit version above shows what happens underneath. The result: 319 training and 81 test observations, with roughly 59% Low / 41% High in both.
Is putting the threshold at 8 an innocent decision?
For classification we split Sales in two at 8,000 units. That number does not come from the data, it comes from us — and it sets the base rate directly.
| Threshold | Low | High | Base rate | Bar the model must clear |
|---|---|---|---|---|
| 7.0 | 184 | 216 | 0.540 | Low — easily cleared |
| 7.5 | 202 | 198 | 0.505 | The most balanced split |
| 8.0 (chosen) | 236 | 164 | 0.590 | Moderate |
| 8.5 | 257 | 143 | 0.643 | High |
| 9.0 | 287 | 113 | 0.718 | Very high — class imbalance starts to bite |
Had we cut at 7.5, the base rate would be 50.5% and "60% accuracy" would count as a genuine result. Cut at 9 and the base rate rises to 71.8%, where the same accuracy means failure. An accuracy figure has to be read together with the threshold that produced it.
There is a second issue: the stores near the line. 56 stores have Sales between 7.5 and 8.5 — 14% of the dataset. Nothing meaningful separates them into "High" and "Low"; only which side of the line they happen to land on.
set.seed() is essential: the split is random, so without a fixed seed every run produces a different train/test partition and a different accuracy. For results to be reproducible, the seed must be fixed and stated in the report.6. Avoiding Data Leakage
Data leakage is information from the test set reaching the model unnoticed. The outcome is always the same: the model looks excellent in the report and mediocre in production.
| Leak | How it happens | The right way |
|---|---|---|
| Scaling | Mean and standard deviation computed on all data. | Parameters learned from training only, then applied to test. |
| Imputation | The median is taken over the whole data set. | Compute the training median and fill the test set with it. |
| Feature selection | Best variables chosen by looking at all the data. | Selection is done on the training set alone. |
| Target-derived features | A variable containing the target stays in the model. | Fields derived from the target are removed. |
| Time series | Future-dated rows end up in training. | Split by time, not at random. |
The classification example in this series carried a hidden leakage risk: when Sales is turned into a binary variable, the original numeric column must be overwritten. Had numeric Sales stayed in the data, the model would read the target directly and report 100% accuracy.
7. A Checklist Before Modelling
Shape and types
How many rows and columns? Were categorical fields read as factors?
Missing data
Where, how much, and why? Does imputation happen after the split?
Distributions
Have skewness, kurtosis and outliers been examined?
The target
Are the classes balanced? What is the base rate? Can accuracy beat it?
The split
Is it stratified? Is the seed fixed? Are the ratios preserved in both sets?
Leakage
Are scaling, imputation and selection learned from training only?
Conclusion
We did not fit a single model in this post, but we laid the whole foundation for the next step: we got to know the data, confirmed there are no missing values, measured how the variables are distributed, and split the data reproducibly into training and test sets.
Two facts from here will matter directly in the next posts: Sales, CompPrice and Price are consistent with a normal distribution, and the base rate in classification is roughly 59%. That second number is especially important — because a model reporting 60% accuracy may have learned nothing at all.
“A good model starts with well-prepared data; a good evaluation starts the moment you split it correctly.”