Keşifsel Veri Analizi (EDA) Nedir?
Veri setini tanımadan modele geçmek yerine; veriyi keşfetmenin, sorunları bulmanın ve analitik soruları doğru kurmanın temellerini inceliyorum.
- Araçlar
- İstatistik
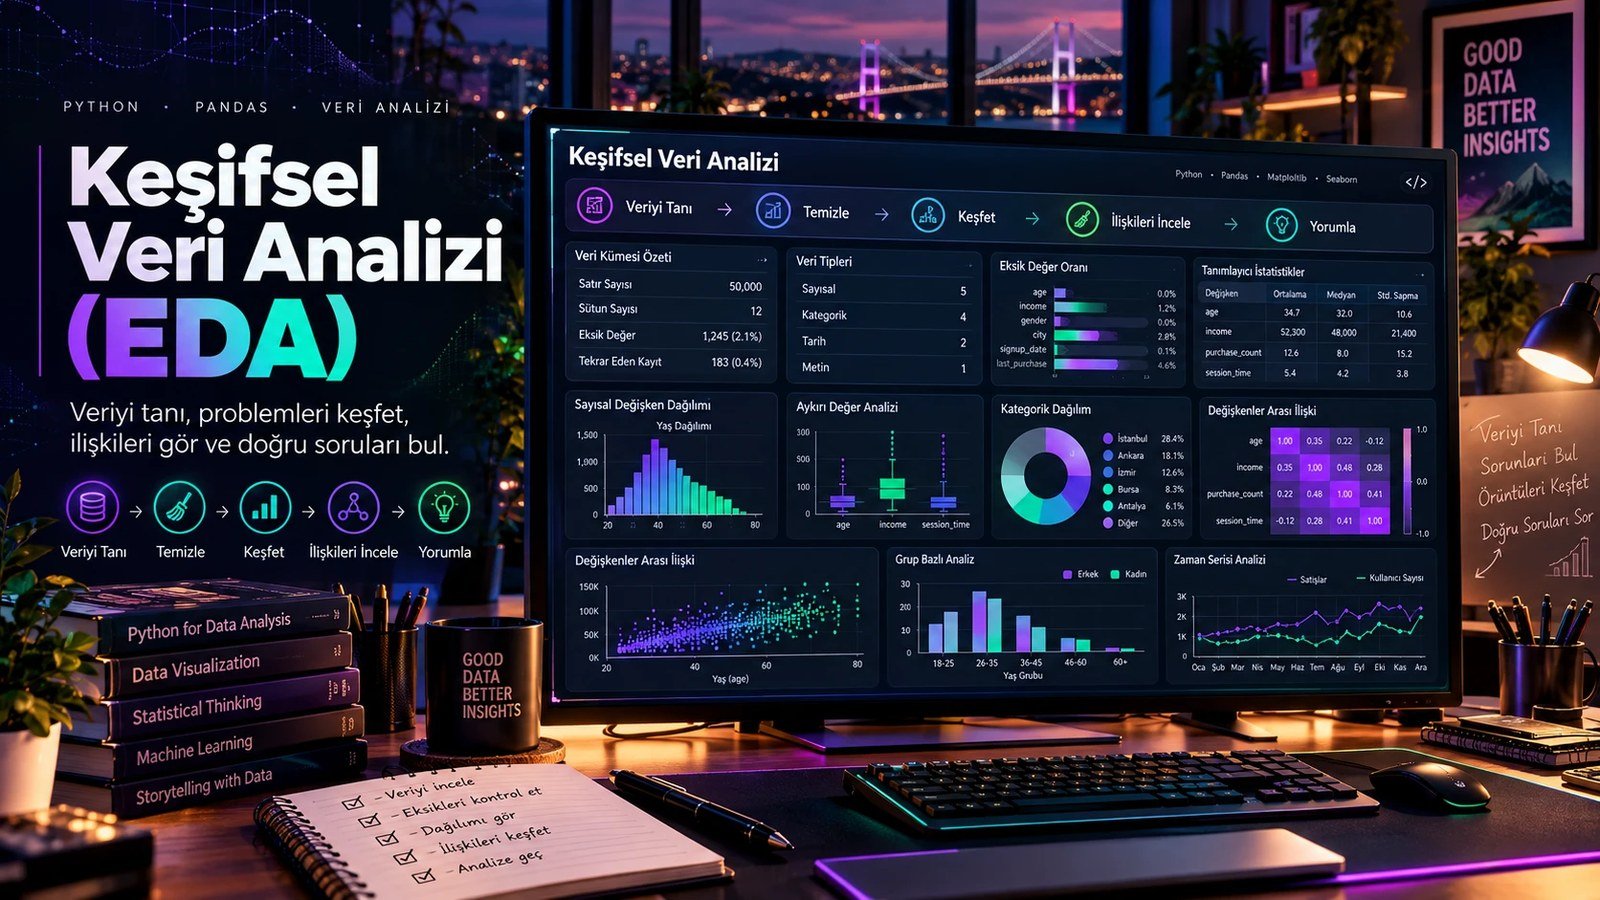
Veri analizi sürecinde model kurmak, grafik üretmek veya istatistiksel test uygulamak çoğu zaman işin görünen kısmıdır. Fakat bütün bunlardan önce yapılması gereken çok daha temel bir aşama var: veriyi tanımak.
Keşifsel Veri Analizi, yani Exploratory Data Analysis (EDA), bir veri setinin yapısını anlamak, eksik ve sıra dışı değerleri tespit etmek, değişkenler arasındaki ilişkileri keşfetmek ve analiz öncesinde veriden mümkün olduğunca fazla bilgi çıkarmak için kullanılan yaklaşımdır.
“İyi bir analiz, iyi bir soruyla başlar; iyi bir soru ise çoğu zaman veriyi keşfederken ortaya çıkar.”
EDA Neden Önemlidir?
Bir veri setini doğrudan modele vermek cazip görünebilir. Ancak verinin yapısını anlamadan yapılan analizler yanıltıcı sonuçlara yol açabilir. EDA, bu riski analiz başlamadan görünür hale getirir.
Eksik değerleri fark etmek
Hangi değişkende ne kadar eksik veri olduğunu ve bu eksikliğin analize etkisini görmek.
Hatalı kayıtları bulmak
Duplicate kayıtları, yanlış veri tiplerini veya mantıksız değerleri analiz öncesinde tespit etmek.
Verinin davranışını görmek
Ortalamaları, dağılımları, aykırı değerleri ve olası çarpıklıkları incelemek.
Örüntüleri keşfetmek
Değişkenlerin birbirleriyle nasıl hareket ettiğini görerek yeni sorular oluşturmak.
- Veriyi
Tanı - Temizle
- Keşfet
- İlişkileri
İncele - Yorumla
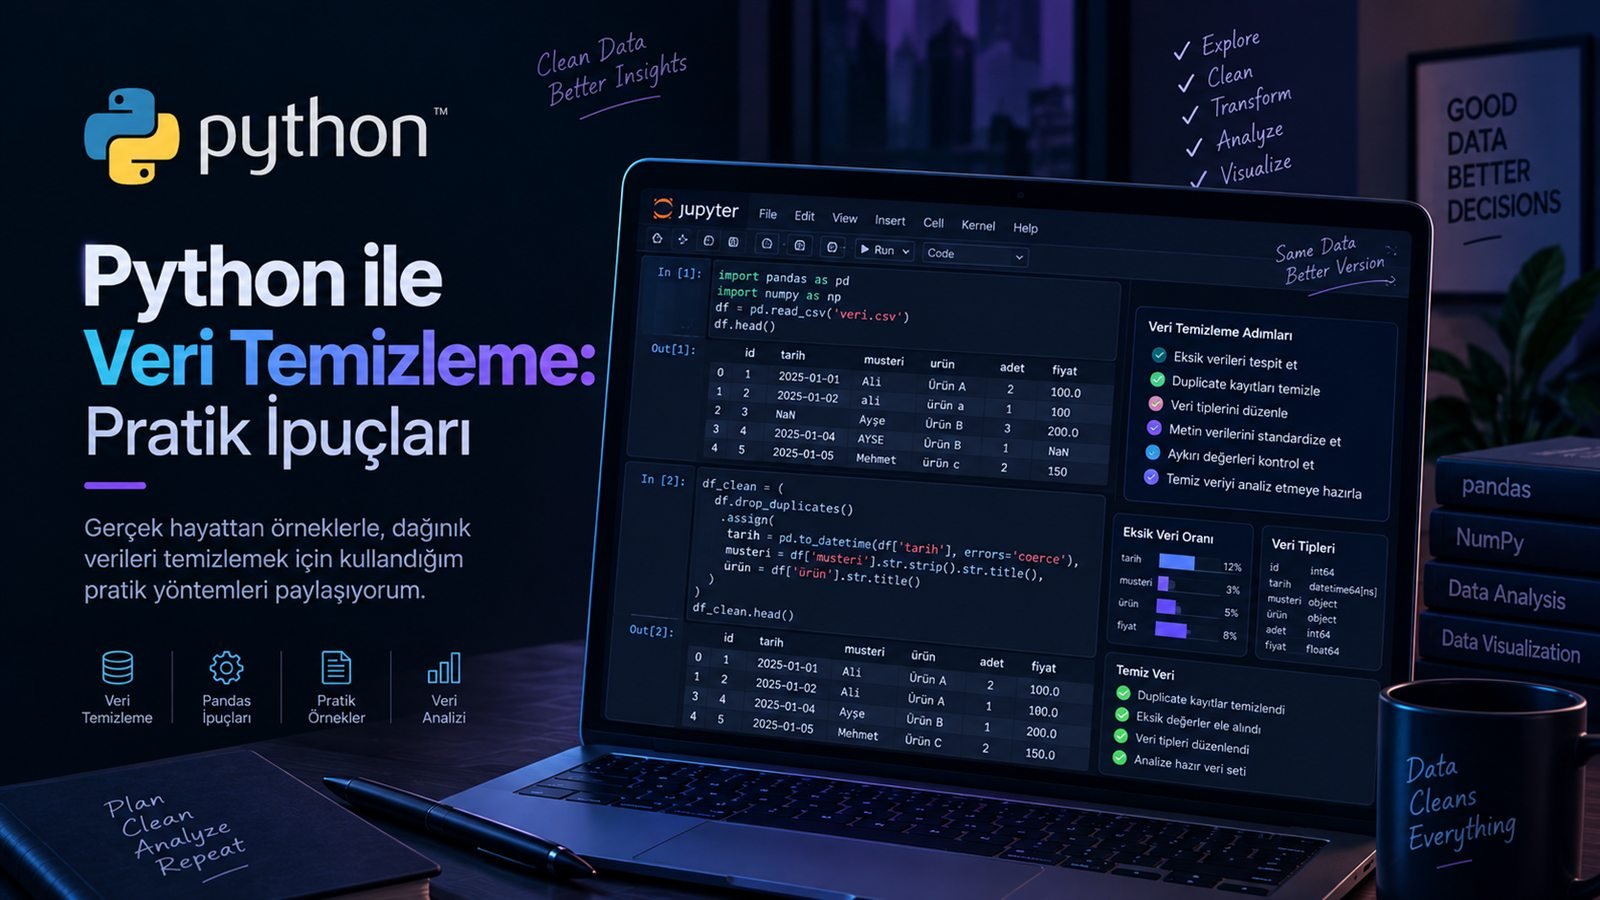
1. Veri Setini Tanımak
EDA'ya başlarken ilk olarak elimizde nasıl bir veri olduğunu anlamamız gerekir. Python tarafında bunun için pandas oldukça güçlü ve pratik bir araç.
import pandas as pd

df = pd.read_csv("satislar.csv")

print(df.shape)
print(df.head())
df.info()
print(df.dtypes)| Komut | Ne gösterir? |
|---|---|
df.shape | Satır ve sütun sayısını |
df.head() | İlk kayıtları |
df.tail() | Son kayıtları |
df.info() | Sütunları, veri tiplerini ve doluluk durumunu |
df.dtypes | Değişkenlerin veri tiplerini |
2. Temel İstatistikleri İncelemek
Veri setinin genel davranışını hızlıca görmek için describe() oldukça kullanışlı. Tek satırda merkezi eğilim, yayılım ve uç değerler hakkında fikir verir.
df.describe()

# Kategorik alanlar da dahil
df.describe(include="all")Ortalama
Değerlerin merkezi eğilimi hakkında fikir verir.
Medyan
Özellikle aykırı değerlerin etkisini anlamada yararlıdır.
Standart sapma
Değerlerin ortalama etrafında ne kadar yayıldığını gösterir.
Uç değerler
Dağılımın sınırlarını ve sıra dışı gözlemleri incelemeye yardımcı olur.
3. Eksik Değerleri Keşfetmek
EDA sırasındaki en önemli kontrollerden biri eksik veri analizi. Hangi sütunda ne kadar boşluk olduğunu bilmeden yapılan her hesaplama yanıltıcı olabilir.
# Sütun başına eksik değer sayısı
df.isna().sum()

# Oran olarak görmek daha okunaklı
df.isna().mean().sort_values(ascending=False)
Örneğin gelir sütununda çok sayıda eksik değer bulunuyorsa, bu değişkenin analizde nasıl kullanılacağına ayrıca karar vermek gerekir.
4. Duplicate Kayıtları Kontrol Etmek
Aynı kaydın birden fazla kez bulunması, özellikle farklı veri kaynakları birleştirildiğinde karşılaşılan sorunlardan biri.
# Duplicate sayısı
df.duplicated().sum()

# Duplicate kayıtları görüntüle
df[df.duplicated()]

# Gerekliyse kaldır
df = df.drop_duplicates()
Birbirine benzeyen iki kaydın gerçekten duplicate olup olmadığını kontrol etmek önemli; aynı görünen iki işlem farklı olaylar olabilir.
5. Aykırı Değerleri İncelemek
Aykırı değerler, veri setindeki genel dağılımdan belirgin biçimde ayrılan gözlemlerdir. Ancak istatistiksel olarak sıra dışı olmak, değerin hatalı olduğu anlamına gelmez.
Q1 = df["satis"].quantile(0.25)
Q3 = df["satis"].quantile(0.75)

IQR = Q3 - Q1
alt = Q1 - 1.5 * IQR
ust = Q3 + 1.5 * IQR

aykiri = df[(df["satis"] < alt) | (df["satis"] > ust)]6. Değişkenlerin Dağılımını Keşfetmek
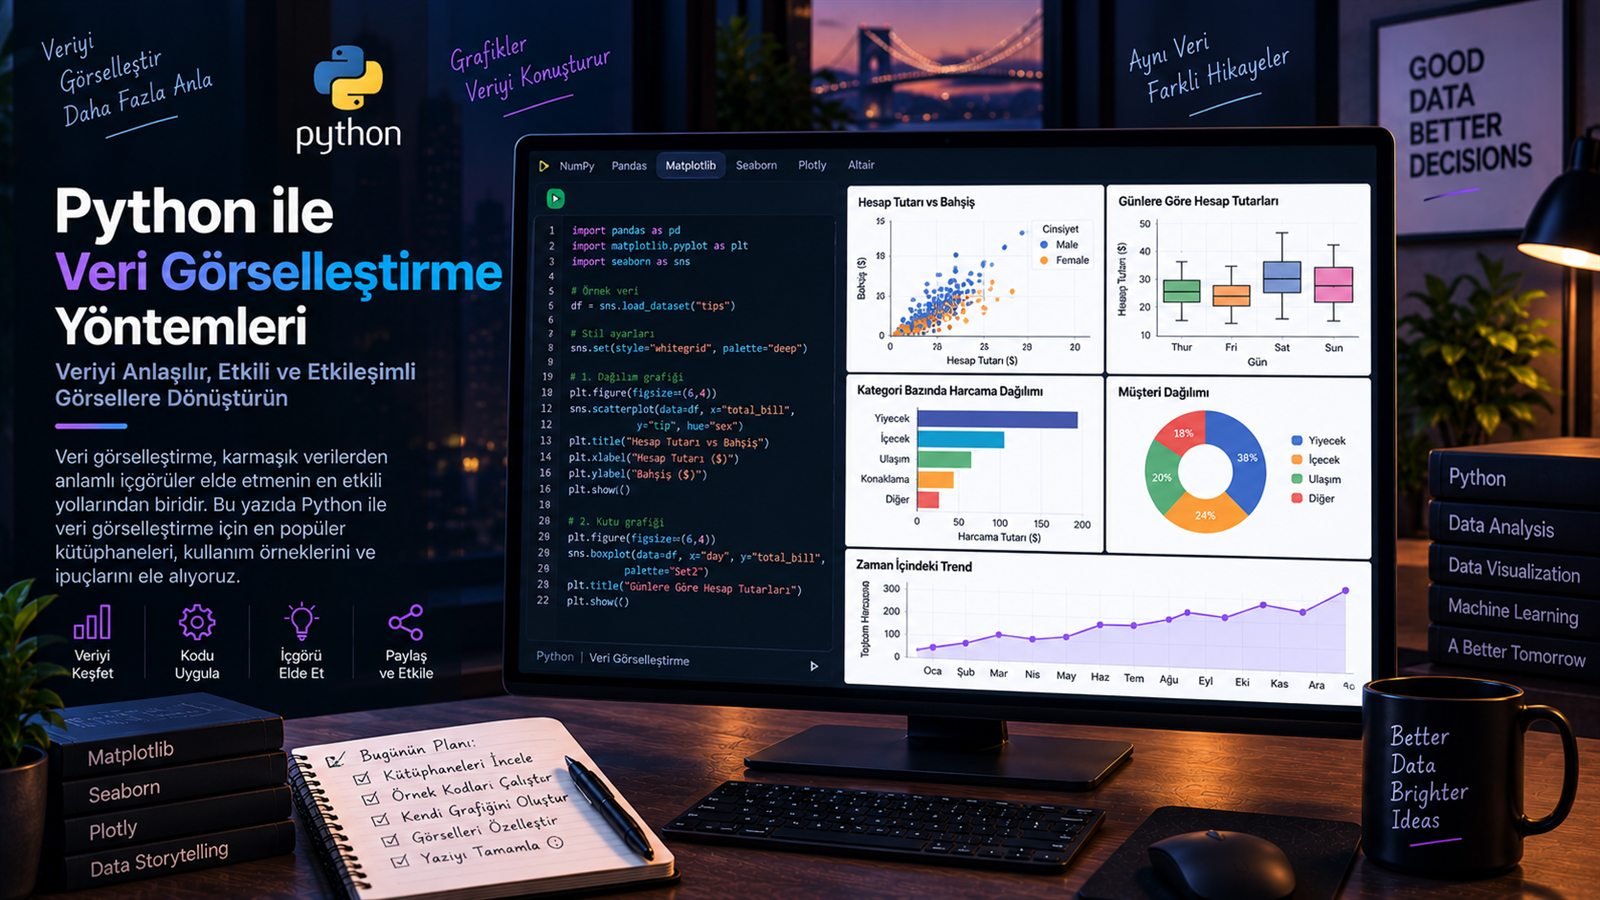
Bir değişkenin nasıl dağıldığını görmek için histogram, boxplot ve yoğunluk grafikleri kullanılabilir. Ortalama tek başına dağılımın şeklini anlatmaz.
Frekans
Değerlerin hangi aralıklarda yoğunlaştığını gösterir.
Dağılım
Medyanı, çeyrekleri ve olası aykırı değerleri birlikte görmeyi sağlar.
import matplotlib.pyplot as plt

df["satis"].hist(bins=30)
plt.show()
7. Kategorik Değişkenleri İncelemek
EDA sadece sayısal değişkenlerden oluşmaz. Kategorik alanların frekanslarını görmek de veri setini anlamak için önemli.
df["kategori"].value_counts()

# Oransal dağılım
df["kategori"].value_counts(normalize=True)
Bu analiz sayesinde veri setinin hangi kategorilerde yoğunlaştığını ve örneklemin dengeli olup olmadığını görebiliriz.
8. Değişkenler Arasındaki İlişkileri Keşfetmek
EDA'nın en değerli taraflarından biri, değişkenleri tek tek değil birlikte incelemek. Örneğin gelir ile satış arasında ilişki olup olmadığını sorgulayabiliriz.
df.plot(kind="scatter", x="gelir", y="satis")
plt.show()

# Sayısal değişkenler arası korelasyon
df.corr(numeric_only=True)9. Grup Bazında Analiz
Toplam değerler bazen veri setinin içindeki farklılıkları gizler. Bu yüzden kategoriler veya segmentler bazında analiz yapmak önemli.
df.groupby("kategori")["satis"].agg(["count", "mean", "median", "std"])EDA Sırasında Kendime Sorduğum Sorular
Boyut
Kaç satır ve kaç sütun var?
Sorunlar
Eksik, duplicate veya mantıksız değer var mı?
Veri tipleri
Değişken tipleri doğru mu?
Davranış
Değişkenler nasıl dağılıyor?
Örüntüler
Değişkenler arasında hangi örüntüler var?
Sonraki adım
Bu keşifler hangi yeni soruları doğuruyor?
Python ile Basit Bir EDA Akışı
Tüm temel kontrolleri küçük bir akışta birleştirebiliriz. Yeni bir veri seti geldiğinde ilk çalıştırdığım şablon bu:
import pandas as pd

df = pd.read_csv("satislar.csv")

print(df.shape)
print(df.head())
df.info()
print(df.isna().sum())
print(df.duplicated().sum())
print(df.describe())
print(df["kategori"].value_counts())
print(df.corr(numeric_only=True))
EDA Bir Sonuç Değil, Bir Başlangıçtır
EDA'nın amacı yalnızca “veri temiz” demek değil. Asıl amaç, verinin bize hangi soruları sormamız gerektiğini göstermesi.
Örneğin gelir ile satış arasında dikkat çekici bir ilişki bulabiliriz. Bu gözlem “Gelir arttıkça satış da artıyor mu?” veya “Bu ilişki her segmentte aynı mı?” gibi yeni sorular doğurur.
Bu nedenle EDA, basit bir veri kontrolünden çıkar ve analitik düşünme sürecinin başlangıç noktasına dönüşür.
Sonuç
Keşifsel Veri Analizi, veri analizi sürecinin en önemli aşamalarından biri. Çünkü model kurmadan, istatistiksel test uygulamadan veya dashboard hazırlamadan önce elimizdeki verinin gerçekten ne anlattığını anlamamız gerekiyor.
Python ve pandas bu süreçte güçlü araçlar sunuyor. head(), info(), describe(), isna(), duplicated(), groupby() ve korelasyon analizleri gibi temel fonksiyonlar bile veri seti hakkında çok şey anlatabiliyor.
EDA'nın özeti: Veriyi tanı → Sorunları bul → Dağılımları incele → İlişkileri keşfet → Soruları oluştur → Analize geç.
In a data analysis process, building a model, producing charts or running statistical tests is usually the visible part of the work. But there is a much more fundamental step that comes before all of it: getting to know the data.
Exploratory Data Analysis (EDA) is the approach used to understand the structure of a data set, spot missing and unusual values, discover relationships between variables and extract as much information as possible from the data before the analysis begins.
“A good analysis starts with a good question, and a good question usually appears while you are exploring the data.”
Why Does EDA Matter?
Feeding a data set straight into a model can look tempting. But analyses made without understanding the structure of the data can lead to misleading results. EDA makes that risk visible before the analysis starts.
Noticing missing values
Seeing how much data is missing in each variable and how that affects the analysis.
Finding faulty records
Detecting duplicates, wrong data types or implausible values before the analysis.
Seeing how data behaves
Examining means, distributions, outliers and possible skewness.
Discovering patterns
Seeing how variables move together and forming new questions from it.
- Know
the Data - Clean
- Explore
- Examine
Relationships - Interpret
1. Getting to Know the Data Set
When starting EDA, the first thing to understand is what kind of data we actually have. On the Python side, pandas is a powerful and practical tool for this.
import pandas as pd

df = pd.read_csv("sales.csv")

print(df.shape)
print(df.head())
df.info()
print(df.dtypes)| Command | What does it show? |
|---|---|
df.shape | The number of rows and columns |
df.head() | The first records |
df.tail() | The last records |
df.info() | Columns, data types and how many values are filled in |
df.dtypes | The data types of the variables |
2. Looking at Basic Statistics
To see the general behaviour of a data set quickly, describe() is very useful. In a single line it gives an idea about central tendency, spread and extreme values.
df.describe()

# Including categorical columns
df.describe(include="all")Average
Gives an idea about the central tendency of the values.
Median
Especially useful for understanding the effect of outliers.
Standard deviation
Shows how widely the values spread around the mean.
Extreme values
Helps examine the limits of the distribution and unusual observations.
3. Exploring Missing Values
One of the most important checks during EDA is missing data analysis. Any calculation made without knowing how many gaps each column has can be misleading.
# Number of missing values per column
df.isna().sum()

# Seeing it as a ratio is easier to read
df.isna().mean().sort_values(ascending=False)
If a column such as income has a large number of missing values, for example, you need a separate decision about how that variable will be used in the analysis.
4. Checking Duplicate Records
The same record appearing more than once is one of the problems you meet especially when different data sources are combined.
# Number of duplicates
df.duplicated().sum()

# Display the duplicate records
df[df.duplicated()]

# Remove them if needed
df = df.drop_duplicates()
It is important to check whether two similar-looking records really are duplicates; two transactions that look the same can be different events.
5. Examining Outliers
Outliers are observations that clearly separate from the general distribution in a data set. But being statistically unusual does not mean the value is wrong.
Q1 = df["sales"].quantile(0.25)
Q3 = df["sales"].quantile(0.75)

IQR = Q3 - Q1
lower = Q1 - 1.5 * IQR
upper = Q3 + 1.5 * IQR

outliers = df[(df["sales"] < lower) | (df["sales"] > upper)]6. Exploring the Distribution of Variables
Histograms, boxplots and density plots can be used to see how a variable is distributed. The mean alone does not describe the shape of a distribution.
Frequency
Shows the ranges in which the values concentrate.
Spread
Lets you see the median, the quartiles and possible outliers together.
import matplotlib.pyplot as plt

df["sales"].hist(bins=30)
plt.show()
7. Examining Categorical Variables
EDA is not only about numerical variables. Seeing the frequencies of categorical fields is also important for understanding the data set.
df["category"].value_counts()

# Proportional distribution
df["category"].value_counts(normalize=True)
This analysis shows which categories the data set concentrates in and whether the sample is balanced.
8. Discovering Relationships Between Variables
One of the most valuable sides of EDA is examining variables together rather than one by one. For example, we can ask whether there is a relationship between income and sales.
df.plot(kind="scatter", x="income", y="sales")
plt.show()

# Correlation between numerical variables
df.corr(numeric_only=True)9. Analysis by Group
Totals sometimes hide the differences inside a data set. That is why analysing by categories or segments matters.
df.groupby("category")["sales"].agg(["count", "mean", "median", "std"])The Questions I Ask Myself During EDA
Size
How many rows and columns are there?
Problems
Are there missing, duplicate or implausible values?
Data types
Are the variable types correct?
Behaviour
How are the variables distributed?
Patterns
Which patterns exist between the variables?
Next step
Which new questions do these findings raise?
A Simple EDA Flow in Python
All the basic checks can be combined into a small flow. This is the template I run first whenever a new data set arrives:
import pandas as pd

df = pd.read_csv("sales.csv")

print(df.shape)
print(df.head())
df.info()
print(df.isna().sum())
print(df.duplicated().sum())
print(df.describe())
print(df["category"].value_counts())
print(df.corr(numeric_only=True))
EDA Is Not a Result, It Is a Beginning
The purpose of EDA is not only to say “the data is clean”. The real purpose is for the data to show us which questions we should be asking.
We may find a striking relationship between income and sales, for example. That observation raises new questions such as “Do sales grow as income grows?” or “Is this relationship the same in every segment?”.
This is why EDA moves beyond a simple data check and becomes the starting point of analytical thinking.
Conclusion
Exploratory Data Analysis is one of the most important stages of the data analysis process. Before building a model, running a statistical test or preparing a dashboard, we need to understand what the data in front of us really says.
Python and pandas offer strong tools for this. Even basic functions such as head(), info(), describe(), isna(), duplicated(), groupby() and correlation analysis can tell a lot about a data set.
EDA in short: Know the data → Find the problems → Examine the distributions → Discover the relationships → Form the questions → Move to analysis.