R ile Denetimsiz Öğrenme: K-Means, Hiyerarşik Kümeleme ve PCA
149 ülkenin verisinde doğal gruplar var mı? K-means, hiyerarşik kümeleme ve PCA'yı uygulayıp sonuçların gerçekten orada olup olmadığını sorguluyorum.
- Makine Öğrenmesi
- İstatistik
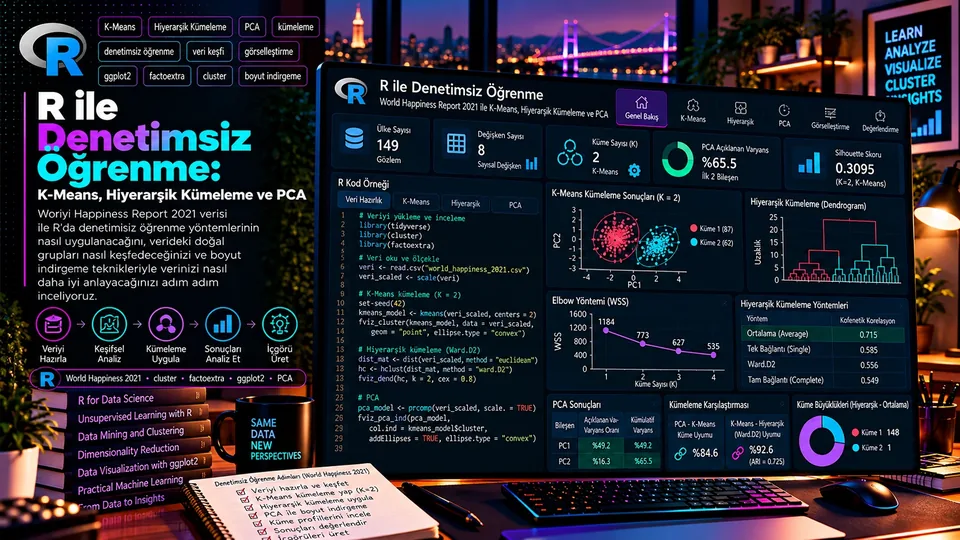
Önceki üç yazıda hedefi bilinen problemlerle çalıştık: satışı tahmin ettik, mağazaları High/Low olarak sınıflandırdık. Şimdi etiketin olmadığı tarafa geçiyoruz. Elimizde yalnızca 149 ülkenin göstergeleri var ve soru şu: bu ülkeler arasında doğal gruplar var mı?
Serinin son yazısında World Happiness Report 2021 verisi üzerinde K-means kümeleme, hiyerarşik kümeleme ve temel bileşen analizini (PCA) uyguluyorum.
“Denetimsiz öğrenmede doğru cevap yoktur; yalnızca savunulabilir yorumlar vardır.”
1. Veri ve Ölçekleme
World Happiness Report 2021, 149 ülke için mutluluk skoru ve onu açıklamak için kullanılan altı gösterge içeriyor. Analize sekiz sayısal değişkenle giriyoruz; güven aralığı sütunlarını (üst/alt sınır ve standart hata) dışarıda bırakıyoruz çünkü bunlar skorun kendisinden türüyor ve aynı bilgiyi üç kez sayarlar.
hap <- read.csv("world-happiness-report-2021.csv", sep = ";", dec = ",")

sayisal <- hap[sapply(hap, is.numeric)]
sayisal <- sayisal[, !names(sayisal) %in% c(
  "Standard.error.of.ladder.score", "upperwhisker", "lowerwhisker")]

X <- scale(na.omit(sayisal)) # 149 x 8Logged.GDP.per.capita 6–11 arasında, Ladder.score ise 2–8 arasında değişiyor; aynı ölçekte olmayan değişkenler mesafeyi orantısız biçimde etkiler. scale() her değişkeni ortalaması 0, standart sapması 1 olacak şekilde dönüştürür ve hepsine eşit söz hakkı verir.2. K-Means
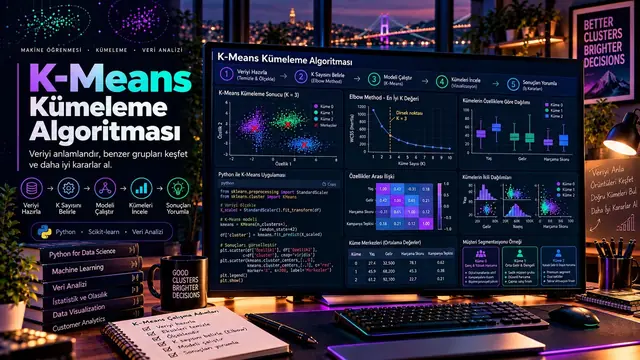
K-means, gözlemleri K kümeye ayırır ve her kümenin merkezini (centroid) iteratif olarak günceller. Tek bir parametresi var ama o parametre analizin tamamını belirliyor: K kaç olmalı?
library(factoextra)
library(cluster)

set.seed(123)
km <- kmeans(X, centers = 2, nstart = 25)

km$size          # 87 62
km$betweenss / km$totss   # 0.3472

fviz_cluster(km, data = X)
nstart = 25 neden önemli? K-means başlangıç merkezlerini rastgele seçer ve yerel bir optimuma takılabilir. nstart, algoritmayı farklı başlangıçlarla defalarca çalıştırıp en iyi çözümü seçer. Varsayılan değer 1'dir ve tek başına bırakıldığında sonuç tohuma göre belirgin biçimde değişebilir.3. Kaç Küme? Üç Ölçüt
K değerine karar vermek için tek bir doğru yöntem yok. Üç yaygın ölçüte birlikte bakmak en sağlıklısı.
Elbow (dirsek) yöntemi
Farklı K değerleri için küme içi kareler toplamı hesaplanır. K arttıkça bu değer her zaman düşer; aranan şey düşüşün belirgin biçimde yavaşladığı nokta.
En büyük düşüş 1'den 2'ye geçişte: 1184'ten 773'e, yani %35. İkinciden üçe geçişte düşüş %19'a, üçten dörde geçişte %15'e iniyor. Dirsek 2 ile 3 arasında.
Siluet skoru
Siluet, her gözlemin kendi kümesine ne kadar yakın ve diğer kümelerden ne kadar uzak olduğunu ölçer. −1 ile 1 arasında değer alır; yüksek olması daha iyi ayrışma demektir.
fviz_nbclust(X, kmeans, method = "silhouette")

# k=2 : 0.3095   <- en yuksek
# k=3 : 0.2696
# k=4 : 0.2692
# k=5 : 0.2666
# k=6 : 0.2230
Gap istatistiği
set.seed(123)
gap <- clusGap(X, FUN = kmeans, nstart = 25, K.max = 10, B = 50)
fviz_gap_stat(gap)
Gap istatistiği, gözlenen küme içi dağılımı rastgele üretilmiş referans verilerle karşılaştırır. Üç ölçütün birlikte işaret ettiği değer k = 2.
4. Kümeleri Yorumlamak
Algoritma "1" ve "2" etiketlerini verir; bu etiketlere anlam yüklemek analistin işidir. Yöntem her zaman aynı: küme merkezlerine bakmak.
| Değişken (ölçeklenmiş) | Küme 1 (87 ülke) | Küme 2 (62 ülke) |
|---|---|---|
| Ladder score (mutluluk) | +0,673 | −0,945 |
| Kişi başı GSYİH (log) | +0,618 | −0,868 |
| Sosyal destek | +0,643 | −0,902 |
| Sağlıklı yaşam beklentisi | +0,643 | −0,903 |
| Seçim özgürlüğü | +0,460 | −0,645 |
| Cömertlik | −0,134 | +0,189 |
| Yolsuzluk algısı | −0,206 | +0,289 |
Tablo kendini anlatıyor. Küme 1'deki 87 ülke mutluluk, gelir, sosyal destek, sağlık ve özgürlükte ortalamanın üzerinde; yolsuzluk algısı ise ortalamanın altında. Küme 2'deki 62 ülke bütün bu göstergelerde tersi konumda.
İlginç olan cömertlik: tek değişken o ve ters yönde çalışıyor. Küme 2'deki ülkeler, geliri ve mutluluk skoru düşük olmasına rağmen cömertlik göstergesinde ortalamanın üzerinde. Bu, kümelemenin "zengin–fakir" ayrımından ibaret olmadığını gösteren küçük ama anlamlı bir ayrıntı.
Toplam değişkenliğin yalnızca %34,7'si kümeler arasında açıklanıyor (betweenss / totss). Geri kalan %65,3 küme içi farklılık; yani her iki grup da kendi içinde oldukça heterojen.
Kümelerde hangi ülkeler var?
Merkezler kümelerin ortalama profilini verir, ama bir kümeyi gerçekten anlamak için içine bakmak gerekir. En kullanışlı yöntem her kümenin merkezine en yakın gözlemleri listelemek: bunlar kümenin "tipik" üyeleridir.
for (k in 1:2) {
  uyeler <- X[km$cluster == k, ]
  uzaklik <- apply(uyeler, 1, function(satir)
                     sqrt(sum((satir - km$centers[k, ])^2)))
  print(head(hap$Country.name[km$cluster == k][order(uzaklik)], 5))
}| Küme | Büyüklük | Merkeze en yakın beş ülke | Mutluluk skoru (ort.) |
|---|---|---|---|
| Küme 1 | 87 | Mauritius, Kazakistan, Uruguay, Polonya, Tayvan | 6,26 |
| Küme 2 | 62 | Etiyopya, Zambiya, Pakistan, Irak, Uganda | 4,52 |
İki kümenin mutluluk ortalaması arasındaki fark 1,74 puan ve %95 güven aralığı [1,53 – 1,95] (Welch t = 16,45; p < 0,001). Bu, kümelerin mutluluk skorunu kullanarak oluşturulduğu düşünülürse şaşırtıcı değil — ama farkın büyüklüğü, bölünmenin ne kadar belirgin olduğunu gösteriyor.
Daha ilginç olan sınırdaki ülkeler. Siluet değeri negatif olan gözlemler, kendi kümelerinden çok komşu kümeye benziyor demektir. Bu analizde böyle dört ülke var: Arnavutluk, Kuzey Makedonya, Türkiye ve Ukrayna.
Bu kümeler kararlı mı?
Kümeleme her veride bir sonuç üretir. Asıl soru, veri biraz değişseydi aynı kümelerin çıkıp çıkmayacağı. Standart test bootstrap kararlılığı: veriden tekrar tekrar örnek çekip kümelemeyi yeniden çalıştırmak ve orijinal kümelerin ne kadar korunduğunu Jaccard benzerliğiyle ölçmek.
jaccard <- function(a, b)
  length(intersect(a, b)) / length(union(a, b))

set.seed(7)
for (b in 1:200) {
  i <- sample(nrow(X), replace = TRUE)
  yeni <- kmeans(X[unique(i), ], centers = 2, nstart = 10)
  # her orijinal kume icin en iyi eslesen yeni kumenin Jaccard'i
}
# Kume 1: 0.9912 Kume 2: 0.9871| Küme | Ortalama Jaccard | 0,75'in üzerinde kalma oranı | Yorum |
|---|---|---|---|
| Küme 1 (87 ülke) | 0,991 | %100 | Son derece kararlı |
| Küme 2 (62 ülke) | 0,987 | %100 | Son derece kararlı |
Yaygın yorum kuralı şudur: 0,85'in üzeri "yüksek derecede kararlı", 0,75–0,85 arası "kararlı", 0,6'nın altı "güvenilmez". Her iki küme de 0,98'in üzerinde ve 200 bootstrap örneğinin tamamında 0,75'i geçiyor.
Peki k = 3 deseydik?
Üç ölçüt de k = 2'yi işaret etmişti, ama kararın ne kaybettirdiğini görmek için k = 3'e bakmaya değer.
| Küme | Büyüklük | Tipik ülkeler | Ayırt eden özellik |
|---|---|---|---|
| 1 | 44 | Pakistan, Etiyopya, Liberya, Uganda, Zambiya | Bütün refah göstergelerinde düşük (−1,0 ile −1,2) |
| 2 | 27 | Kanada, Avusturya, Almanya, Avustralya, İrlanda | Yüksek refah ve çok düşük yolsuzluk algısı (−1,54) |
| 3 | 78 | Karadağ, Dominik Cumhuriyeti, Ekvador, Mauritius, Moldova | Ortada; cömertlik düşük (−0,45), yolsuzluk algısı yüksek |
k = 3 çözümü açıklanan oranı %34,7'den %47,1'e çıkarıyor ve ortaya anlamlı bir orta grup koyuyor. Fakat yeni ayrımı yapan asıl değişken yolsuzluk algısı: ikinci küme, birinciden refahla değil kurumsal güvenle ayrılıyor.
5. Hiyerarşik Kümeleme
K-means'ten farklı olarak hiyerarşik kümeleme küme sayısını baştan sormaz. Her gözlemi kendi kümesi sayıp en yakın olanları birleştirerek bir ağaç (dendrogram) üretir; kesme noktasına sonradan karar verirsin.
Kritik seçim bağlantı yöntemi: iki küme arasındaki uzaklık nasıl tanımlanacak?
| Yöntem | Mesafe tanımı | Kofenetik korelasyon |
|---|---|---|
| Average | İki kümedeki tüm nokta çiftlerinin ortalaması | 0,715 |
| Single | En yakın iki nokta | 0,585 |
| Ward.D2 | Birleşmenin küme içi varyansa maliyeti | 0,556 |
| Complete | En uzak iki nokta | 0,549 |
d <- dist(X)

for (m in c("single", "complete", "average", "ward.D2")) {
  hc <- hclust(d, method = m)
  cat(m, cor(d, cophenetic(hc)), "\n")
}

# En yuksek kofenetik korelasyon: average
hc <- hclust(d, method = "average")
fviz_dend(hc, k = 2, cex = 0.5)average yöntemi 0,715 ile açık ara önde; ward.D2 görsel olarak daha dengeli ağaçlar üretse de bu veride mesafe yapısını daha çok bozuyor.Burada önemli bir ayrım var: en yüksek kofenetik korelasyon, "en iyi kümeleme" demek değil. Yalnızca ağacın mesafeleri en sadık biçimde temsil ettiğini söyler. Ward yöntemi çoğu uygulamada daha yorumlanabilir kümeler üretir; seçim amaca göre yapılmalı.
Peki bu ağaç k-means ile aynı şeyi mi söylüyor?
Yukarıdaki cümle genel bir uyarı gibi duruyor. Bu veride somut olarak sınanabilir: her iki yöntemin ağacını ikiye kesip k-means'in bulduğu bölünmeyle karşılaştırmak yeterli.
for (m in c("average", "ward.D2")) {
  hc <- hclust(d, method = m)
  print(table(kmeans = km$cluster, hiyerarsik = cutree(hc, 2)))
}| Yöntem | Kofenetik korelasyon | Kesme sonucu küme büyüklükleri | K-means ile uyum | Düzeltilmiş Rand |
|---|---|---|---|---|
| Average | 0,715 | 148 + 1 | %59,1 | 0,005 |
| Ward.D2 | 0,556 | 82 + 67 | %92,6 | 0,725 |
Sonuç çarpıcı. Kofenetik korelasyonu en yüksek olan average yöntemi ikiye kesildiğinde 148 ülkeyi bir kümeye, tek bir ülkeyi diğerine koyuyor. Mesafeleri sadakatle temsil ediyor ama kullanılabilir bir bölünme üretmiyor. Düzeltilmiş Rand indeksi 0,005 — yani k-means'le uyumu rastgele eşleşmeden farksız.
Ward.D2 ise en düşük kofenetik korelasyona sahip olmasına rağmen 82 + 67'lik dengeli bir bölünme veriyor ve k-means'in sonucuyla %92,6 örtüşüyor (ARI = 0,725). 149 ülkeden yalnızca 11'i farklı kümeye düşüyor.
Düzeltilmiş Rand indeksi (ARI) iki kümelemenin uyumunu ölçer: 1 tam örtüşme, 0 ise rastgele eşleşme düzeyinde benzerlik demektir. Küme etiketlerinin numaralarından bağımsız çalışır — Küme 1 ile Küme 2'nin yer değiştirmesi sonucu etkilemez.
6. Temel Bileşen Analizi (PCA)
Sekiz değişkenli bir veriyi iki boyutta görselleştirmek için bir yola ihtiyaç var. PCA, değişkenlerin doğrusal birleşimlerinden, mümkün olduğunca çok değişkenliği taşıyan yeni eksenler üretir.
pca <- prcomp(sayisal, center = TRUE, scale. = TRUE)
summary(pca)

fviz_eig(pca)                      # scree plot
fviz_pca_var(pca, repel = TRUE)   # degisken yukleri
fviz_pca_biplot(pca, habillage = factor(km$cluster))| Bileşen | Standart sapma | Açıklanan varyans | Kümülatif |
|---|---|---|---|
| PC1 | 1,983 | %49,2 | %49,2 |
| PC2 | 1,142 | %16,3 | %65,5 |
| PC3 | 1,083 | %14,7 | %80,1 |
| PC4 | 0,839 | %8,8 | %88,9 |
| PC5 | 0,713 | %6,4 | %95,3 |
İlk iki bileşen sekiz değişkenin taşıdığı bilginin %65,5'ini iki eksende topluyor. Üçüncüyü de eklersek %80'e çıkıyoruz. Bu, sekiz boyutlu veriyi iki boyutlu bir grafikte göstermenin makul bir yaklaşım olduğu anlamına geliyor — ama %34,5'lik bir bilginin grafikte görünmediğini de unutmamak gerekiyor.
| Değişken | PC1 yükü | PC2 yükü |
|---|---|---|
| Ladder score | −0,471 | +0,128 |
| Kişi başı GSYİH | −0,454 | −0,238 |
| Sağlıklı yaşam beklentisi | −0,449 | −0,187 |
| Sosyal destek | −0,429 | −0,186 |
| Seçim özgürlüğü | −0,340 | +0,348 |
| Yolsuzluk algısı | +0,250 | −0,395 |
| Dystopia | −0,082 | +0,296 |
| Cömertlik | +0,042 | +0,702 |
PC1 bir refah ekseni. Mutluluk, gelir, sağlık, sosyal destek ve özgürlük hepsi aynı yönde yükleniyor; yolsuzluk algısı ters yönde. Bu eksen tek başına değişkenliğin yarısını açıklıyor ve pratikte "gelişmişlik düzeyi" olarak okunabilir.
PC2 ise bir cömertlik ekseni. 0,702'lik yükle cömertlik bu bileşene hâkim; yolsuzluk algısı (−0,395) ve seçim özgürlüğü (+0,348) ona eşlik ediyor. Yani refahla açıklanamayan ikinci bir yapı var ve bu yapı toplumsal davranışla ilgili.
Kaç bileşen tutulmalı?
"İlk iki bileşen %65,5'ini açıklıyor" cümlesi bir gözlem, karar değil. Kaç bileşenin tutulacağına karar vermek için birkaç ölçüt var ve bu veride ikisi farklı cevap veriyor.
| Bileşen | Özdeğer | Açıklanan % | Kümülatif % | Kırık çubuk eşiği | Tutulsun mu? |
|---|---|---|---|---|---|
| PC1 | 3,933 | 49,16 | 49,16 | 2,718 | Evet (her iki ölçüt) |
| PC2 | 1,303 | 16,29 | 65,45 | 1,718 | Yalnızca Kaiser |
| PC3 | 1,173 | 14,67 | 80,11 | 1,218 | Yalnızca Kaiser |
| PC4 | 0,704 | 8,80 | 88,91 | 0,885 | Hayır |
| PC5 | 0,508 | 6,35 | 95,27 | 0,635 | Hayır |
| Ölçüt | Kuralı | Bu veride sonucu |
|---|---|---|
| Kaiser | Özdeğeri 1'den büyük bileşenleri tut. | 3 bileşen (3,93 · 1,30 · 1,17) |
| Scree (dirsek) | Eğrinin kırıldığı noktaya kadar tut. | PC1'den sonra belirgin düşüş → 1–2 bileşen |
| Kırık çubuk | Özdeğeri, rastgele bölünmede beklenen değeri aşanları tut. | 1 bileşen |
| Kümülatif oran | %70–80'e ulaşana kadar tut. | 3 bileşen (%80,1) |
Kaiser ölçütü üç bileşen diyor, kırık çubuk ölçütü bir. Bu çelişki tesadüf değil: Kaiser'in "özdeğer > 1" kuralı bilinen biçimde cömerttir ve gereğinden fazla bileşen tutma eğilimindedir. Kırık çubuk ölçütü ise özdeğerleri, bir çubuğun rastgele kırılmasından beklenen uzunluklarla karşılaştırır ve belirgin biçimde daha muhafazakârdır.
PCA'dan sonra kümelemek aynı sonucu verir mi?
Yaygın bir iş akışı var: önce PCA ile boyut indir, sonra bileşenler üzerinde kümele. Gürültüyü azalttığı ve mesafeleri daha anlamlı kıldığı söylenir. Bu veride test edilebilir.
Z <- pca$x[, 1:3]                 # ilk uc bilesen
set.seed(123)
km_pca <- kmeans(scale(Z), centers = 2, nstart = 25)

table(ham = km$cluster, pca = km_pca$cluster)
# uyum: %84.6
İlk üç bileşen üzerinde kümeleme, ham ölçeklenmiş veri üzerindeki kümelemeyle %84,6 örtüşüyor. 149 ülkeden 23'ü farklı kümeye düşüyor — azımsanacak bir fark değil.
Sebebi şu: ilk üç bileşen toplam değişkenliğin %80,1'ini taşıyor, geri kalan %19,9'u atıyor. Atılan kısım "gürültü" olabilir, ama kümeleme için anlamlı bilgi de olabilir. Bu veride atılan kısmın bir bölümü ikinci grubu kurumsal güvene göre ayıran bilgiydi.
7. Sık Yapılan Hatalar
| Hata | Neden problem? | Daha iyi yaklaşım |
|---|---|---|
| Ölçeklemeden kümelemek | Büyük ölçekli değişken mesafeyi domine eder. | scale() uygulamak, ardından sonucu kontrol etmek. |
| K'yı tek ölçütle seçmek | Elbow çoğu zaman net bir dirsek göstermez. | Elbow, siluet ve gap'i birlikte okumak. |
nstart varsayılanda bırakmak | Yerel optimuma takılma riski. | nstart = 25 gibi bir değer vermek. |
| Siluet değerini raporlamamak | Kümelerin ne kadar ayrıştığı bilinmez. | Skoru yazmak ve düşükse bunu açıkça söylemek. |
| Küme etiketlerini sabit sanmak | Numaralar her çalıştırmada değişebilir. | Kümeleri numaraya göre değil profile göre adlandırmak. |
| PCA'yı ölçeklemeden yapmak | Büyük varyanslı değişken ilk bileşeni ele geçirir. | prcomp(..., scale. = TRUE) kullanmak. |
Sonuç
Denetimsiz öğrenmede modelin doğruluğunu ölçecek bir test seti yok. Onun yerine iç tutarlılık ölçütleri (siluet, kofenetik korelasyon, açıklanan varyans) ve en önemlisi sonucun anlamlı olup olmadığı var.
Bu analizde üç yöntem de aynı yapıya işaret etti: 149 ülke, refah göstergelerine göre kabaca ikiye ayrılıyor ve bu ayrım toplam değişkenliğin üçte birini açıklıyor. PCA ise ikinci bir boyut gösterdi — refahla açıklanamayan, cömertlik etrafında şekillenen bir eksen. Bu, kümelemenin tek başına anlatmadığı bir bulgu.
Dört yazılık seri burada bitiyor. Veri hazırlığından başlayıp regresyon, sınıflandırma ve kümelemeye uzanan bu akışta tek bir ortak tema vardı: modeli kurmak kolay, ona güvenip güvenemeyeceğine karar vermek zor.
“Kümeleme her veride bir sonuç üretir. Asıl soru, ürettiği sonucun gerçekten orada olup olmadığıdır.”
In the previous three posts we worked on problems with a known target: we predicted sales and classified stores as High or Low. Now we move to the side where there are no labels. All we have are indicators for 149 countries, and the question is: are there natural groups among them?
In this final post of the series I apply K-means clustering, hierarchical clustering and principal component analysis (PCA) to the World Happiness Report 2021 data.
“In unsupervised learning there is no right answer; there are only defensible interpretations.”
1. The Data and Scaling
The World Happiness Report 2021 holds a happiness score and six explanatory indicators for 149 countries. We go in with eight numeric variables, leaving out the confidence interval columns (upper and lower whisker and the standard error) because they are derived from the score itself and would count the same information three times.
hap <- read.csv("world-happiness-report-2021.csv", sep = ";", dec = ",")

numeric_vars <- hap[sapply(hap, is.numeric)]
numeric_vars <- numeric_vars[, !names(numeric_vars) %in% c(
  "Standard.error.of.ladder.score", "upperwhisker", "lowerwhisker")]

X <- scale(na.omit(numeric_vars)) # 149 x 8Logged.GDP.per.capita ranges from 6 to 11 while Ladder.score ranges from 2 to 8; variables on different scales distort the distance disproportionately. scale() transforms each variable to mean 0 and standard deviation 1, giving them equal say.2. K-Means
K-means divides observations into K clusters and iteratively updates each cluster's centroid. It has a single parameter, and that parameter decides the whole analysis: what should K be?
library(factoextra)
library(cluster)

set.seed(123)
km <- kmeans(X, centers = 2, nstart = 25)

km$size          # 87 62
km$betweenss / km$totss   # 0.3472

fviz_cluster(km, data = X)nstart = 25 matters: K-means picks its starting centroids at random and can settle into a local optimum. nstart runs the algorithm repeatedly from different starts and keeps the best solution. The default is 1, and left alone the result can shift noticeably with the seed.3. How Many Clusters? Three Criteria
There is no single right way to choose K. Reading three common criteria together is the soundest approach.
The elbow method
The within-cluster sum of squares is computed for different values of K. It always falls as K grows; what you look for is the point where the fall clearly slows down.
The largest drop is from 1 to 2: 1184 down to 773, a fall of 35%. From two to three the drop is 19%, and from three to four 15%. The elbow sits between 2 and 3.
Silhouette score
The silhouette measures how close each observation is to its own cluster and how far from the others. It ranges from −1 to 1; higher means cleaner separation.
fviz_nbclust(X, kmeans, method = "silhouette")

# k=2 : 0.3095   <- highest
# k=3 : 0.2696
# k=4 : 0.2692
# k=5 : 0.2666
# k=6 : 0.2230
The gap statistic
set.seed(123)
gap <- clusGap(X, FUN = kmeans, nstart = 25, K.max = 10, B = 50)
fviz_gap_stat(gap)
The gap statistic compares the observed within-cluster dispersion against randomly generated reference data. All three criteria point to k = 2.
4. Interpreting the Clusters
The algorithm hands you labels "1" and "2"; giving them meaning is the analyst's job. The method is always the same: look at the cluster centres.
| Variable (scaled) | Cluster 1 (87 countries) | Cluster 2 (62 countries) |
|---|---|---|
| Ladder score (happiness) | +0.673 | −0.945 |
| GDP per capita (log) | +0.618 | −0.868 |
| Social support | +0.643 | −0.902 |
| Healthy life expectancy | +0.643 | −0.903 |
| Freedom to make life choices | +0.460 | −0.645 |
| Generosity | −0.134 | +0.189 |
| Perceptions of corruption | −0.206 | +0.289 |
The table speaks for itself. The 87 countries in cluster 1 sit above average on happiness, income, social support, health and freedom, and below average on perceived corruption. The 62 countries in cluster 2 are the mirror image on every one of those indicators.
The interesting one is generosity: it is the only variable running the other way. Countries in cluster 2 score above average on generosity despite lower income and happiness. It is a small but meaningful detail showing that the clustering is not simply a rich–poor divide.
Only 34.7% of the total variation is explained between the clusters (betweenss / totss). The remaining 65.3% is within-cluster variation — both groups are quite heterogeneous internally.
Which countries are in each cluster?
Centroids give a cluster's average profile, but understanding a cluster means looking inside it. The most useful move is to list the observations closest to each centroid: those are the cluster's "typical" members.
for (k in 1:2) {
  members <- X[km$cluster == k, ]
  d <- apply(members, 1, function(row)
              sqrt(sum((row - km$centers[k, ])^2)))
  print(head(hap$Country.name[km$cluster == k][order(d)], 5))
}| Cluster | Size | Five countries closest to the centre | Mean ladder score |
|---|---|---|---|
| Cluster 1 | 87 | Mauritius, Kazakhstan, Uruguay, Poland, Taiwan | 6.26 |
| Cluster 2 | 62 | Ethiopia, Zambia, Pakistan, Iraq, Uganda | 4.52 |
The gap between the two mean happiness scores is 1.74 points, with a 95% confidence interval of [1.53, 1.95] (Welch t = 16.45, p < 0.001). Given that the clusters were built using the ladder score, that is no surprise — but the size of the gap shows how pronounced the split is.
The border countries are more interesting. An observation with a negative silhouette resembles its neighbouring cluster more than its own. There are four of them here: Albania, North Macedonia, Turkey and Ukraine.
Are these clusters stable?
Clustering returns a result on any dataset. The real question is whether the same clusters would appear if the data changed slightly. The standard check is bootstrap stability: resample the data repeatedly, rerun the clustering, and measure how well the original clusters survive using Jaccard similarity.
jaccard <- function(a, b)
  length(intersect(a, b)) / length(union(a, b))

set.seed(7)
for (b in 1:200) {
  i <- sample(nrow(X), replace = TRUE)
  new <- kmeans(X[unique(i), ], centers = 2, nstart = 10)
  # best-matching Jaccard for each original cluster
}
# Cluster 1: 0.9912 Cluster 2: 0.9871| Cluster | Mean Jaccard | Share above 0.75 | Reading |
|---|---|---|---|
| Cluster 1 (87 countries) | 0.991 | 100% | Highly stable |
| Cluster 2 (62 countries) | 0.987 | 100% | Highly stable |
The usual rule of thumb: above 0.85 is "highly stable", 0.75–0.85 is "stable", below 0.6 is unreliable. Both clusters sit above 0.98 and clear 0.75 in all 200 bootstrap samples.
And if we had chosen k = 3?
All three criteria pointed at k = 2, but it is worth seeing what that decision costs.
| Cluster | Size | Typical countries | Distinguishing feature |
|---|---|---|---|
| 1 | 44 | Pakistan, Ethiopia, Liberia, Uganda, Zambia | Low on every welfare indicator (−1.0 to −1.2) |
| 2 | 27 | Canada, Austria, Germany, Australia, Ireland | High welfare and very low perceived corruption (−1.54) |
| 3 | 78 | Montenegro, Dominican Republic, Ecuador, Mauritius, Moldova | In between; low generosity (−0.45), high perceived corruption |
The k = 3 solution lifts the explained share from 34.7% to 47.1% and produces a meaningful middle group. But the variable doing the new separating is perceived corruption: the second cluster is set apart from the third by institutional trust rather than by wealth.
5. Hierarchical Clustering
Unlike K-means, hierarchical clustering does not ask for the number of clusters up front. It treats every observation as its own cluster, merges the closest ones, and produces a tree (a dendrogram); you decide where to cut afterwards.
The critical choice is the linkage method: how is the distance between two clusters defined?
| Method | Distance definition | Cophenetic correlation |
|---|---|---|
| Average | Mean over all pairs of points in the two clusters | 0.715 |
| Single | The two closest points | 0.585 |
| Ward.D2 | The cost of merging in within-cluster variance | 0.556 |
| Complete | The two farthest points | 0.549 |
d <- dist(X)

for (m in c("single", "complete", "average", "ward.D2")) {
  hc <- hclust(d, method = m)
  cat(m, cor(d, cophenetic(hc)), "\n")
}

# Highest cophenetic correlation: average
hc <- hclust(d, method = "average")
fviz_dend(hc, k = 2, cex = 0.5)average leads clearly at 0.715; ward.D2 produces more visually balanced trees but distorts the distance structure more on this data.There is an important distinction here: the highest cophenetic correlation does not mean "the best clustering". It only says the tree represents the distances most faithfully. Ward's method produces more interpretable clusters in many applications; the choice should follow the purpose.
But does this tree say the same thing as k-means?
That sentence reads like a general warning. On this dataset it can be tested directly: cut each tree into two and compare the result with the split k-means found.
for (m in c("average", "ward.D2")) {
  hc <- hclust(d, method = m)
  print(table(kmeans = km$cluster, hierarchical = cutree(hc, 2)))
}| Method | Cophenetic correlation | Cluster sizes after the cut | Agreement with k-means | Adjusted Rand |
|---|---|---|---|---|
| Average | 0.715 | 148 + 1 | 59.1% | 0.005 |
| Ward.D2 | 0.556 | 82 + 67 | 92.6% | 0.725 |
The result is striking. Cut in two, the average method — the one with the highest cophenetic correlation — puts 148 countries in one cluster and a single country in the other. It represents the distances faithfully while producing no usable split. Its adjusted Rand index against k-means is 0.005, no better than chance agreement.
Ward.D2, despite having the lowest cophenetic correlation, yields a balanced 82 + 67 split that overlaps 92.6% with the k-means solution (ARI = 0.725). Only 11 of the 149 countries land in a different cluster.
The adjusted Rand index (ARI) measures agreement between two clusterings: 1 is a perfect match, 0 is the level of similarity you would get by chance. It is invariant to the cluster labels — swapping "Cluster 1" and "Cluster 2" does not change it.
6. Principal Component Analysis
Visualizing eight-variable data in two dimensions needs a method. PCA builds new axes from linear combinations of the variables, carrying as much variation as possible.
pca <- prcomp(numeric_vars, center = TRUE, scale. = TRUE)
summary(pca)

fviz_eig(pca)                      # scree plot
fviz_pca_var(pca, repel = TRUE)   # variable loadings
fviz_pca_biplot(pca, habillage = factor(km$cluster))| Component | Standard deviation | Variance explained | Cumulative |
|---|---|---|---|
| PC1 | 1.983 | 49.2% | 49.2% |
| PC2 | 1.142 | 16.3% | 65.5% |
| PC3 | 1.083 | 14.7% | 80.1% |
| PC4 | 0.839 | 8.8% | 88.9% |
| PC5 | 0.713 | 6.4% | 95.3% |
The first two components gather 65.5% of the information in eight variables onto two axes. Adding the third takes us to 80%. That makes a two-dimensional plot a reasonable way to show eight-dimensional data — while remembering that 34.5% of the information is not visible in it.
| Variable | PC1 loading | PC2 loading |
|---|---|---|
| Ladder score | −0.471 | +0.128 |
| GDP per capita | −0.454 | −0.238 |
| Healthy life expectancy | −0.449 | −0.187 |
| Social support | −0.429 | −0.186 |
| Freedom to make life choices | −0.340 | +0.348 |
| Perceptions of corruption | +0.250 | −0.395 |
| Dystopia | −0.082 | +0.296 |
| Generosity | +0.042 | +0.702 |
PC1 is a prosperity axis. Happiness, income, health, social support and freedom all load in the same direction, with perceived corruption against them. This single axis explains half the variation and reads in practice as "level of development".
PC2 is a generosity axis. With a loading of 0.702, generosity dominates this component, accompanied by perceived corruption (−0.395) and freedom of choice (+0.348). In other words, there is a second structure that prosperity does not explain, and it concerns social behaviour.
How many components should we keep?
"The first two components explain 65.5%" is an observation, not a decision. Several criteria exist for choosing how many to keep, and on this data two of them disagree.
| Component | Eigenvalue | Explained % | Cumulative % | Broken-stick threshold | Keep? |
|---|---|---|---|---|---|
| PC1 | 3.933 | 49.16 | 49.16 | 2.718 | Yes (both criteria) |
| PC2 | 1.303 | 16.29 | 65.45 | 1.718 | Kaiser only |
| PC3 | 1.173 | 14.67 | 80.11 | 1.218 | Kaiser only |
| PC4 | 0.704 | 8.80 | 88.91 | 0.885 | No |
| PC5 | 0.508 | 6.35 | 95.27 | 0.635 | No |
| Criterion | Rule | Answer on this data |
|---|---|---|
| Kaiser | Keep components with an eigenvalue above 1. | 3 components (3.93, 1.30, 1.17) |
| Scree (elbow) | Keep up to the point where the curve bends. | Sharp drop after PC1 → 1–2 components |
| Broken stick | Keep eigenvalues that exceed what a random split would give. | 1 component |
| Cumulative share | Keep until you reach 70–80%. | 3 components (80.1%) |
Kaiser says three components, the broken stick says one. The clash is not accidental: the "eigenvalue > 1" rule is known to be generous and tends to retain more components than it should. The broken-stick criterion compares eigenvalues with the lengths expected from randomly breaking a stick, and is markedly more conservative.
Does clustering after PCA give the same answer?
A common workflow is to reduce dimensions with PCA first and cluster on the components afterwards, on the grounds that it removes noise and makes distances more meaningful. That claim is testable here.
Z <- pca$x[, 1:3]                 # first three components
set.seed(123)
km_pca <- kmeans(scale(Z), centers = 2, nstart = 25)

table(raw = km$cluster, pca = km_pca$cluster)
# agreement: 84.6%
Clustering on the first three components overlaps 84.6% with clustering on the raw scaled data. Twenty-three of the 149 countries land in a different cluster — not a trivial difference.
The reason is straightforward: the first three components carry 80.1% of the total variation and discard the remaining 19.9%. What gets discarded may be noise, but it may equally be information the clustering needed. On this data, part of what was dropped is exactly what separated the second group on institutional trust.
7. Common Mistakes
| Mistake | Why it is a problem | A better approach |
|---|---|---|
| Clustering without scaling | The large-scale variable dominates the distance. | Apply scale(), then check the result. |
| Choosing K by one criterion | The elbow often shows no clear bend. | Read elbow, silhouette and gap together. |
Leaving nstart at the default | Risk of settling in a local optimum. | Set a value such as nstart = 25. |
| Not reporting the silhouette | Nobody knows how separated the clusters are. | State the score, and say so plainly when it is low. |
| Treating cluster labels as fixed | The numbers can change on every run. | Name clusters by profile, not by number. |
| Running PCA without scaling | A high-variance variable captures the first component. | Use prcomp(..., scale. = TRUE). |
Conclusion
In unsupervised learning there is no test set to measure accuracy against. In its place you have internal consistency measures — silhouette, cophenetic correlation, explained variance — and, above all, whether the result makes sense.
All three methods pointed to the same structure here: 149 countries divide roughly in two along prosperity indicators, and that split explains about a third of the total variation. PCA then revealed a second dimension that prosperity does not account for, organized around generosity — a finding the clustering alone does not tell you.
This four-part series ends here. From data preparation through regression, classification and clustering, one theme ran through all of it: fitting a model is easy; deciding whether to trust it is hard.
“Clustering produces a result on any data. The real question is whether that result was actually there.”