R ile Çoklu Doğrusal Regresyon: Modelden Tahmine
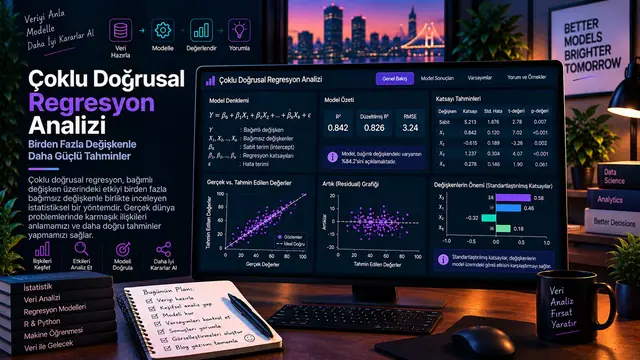
lm() ile model kurmaktan katsayı yorumuna, varsayım kontrolünden test setindeki gerçek performansa kadar çoklu doğrusal regresyonu R'da adım adım uyguluyorum.
- Makine Öğrenmesi
- İstatistik
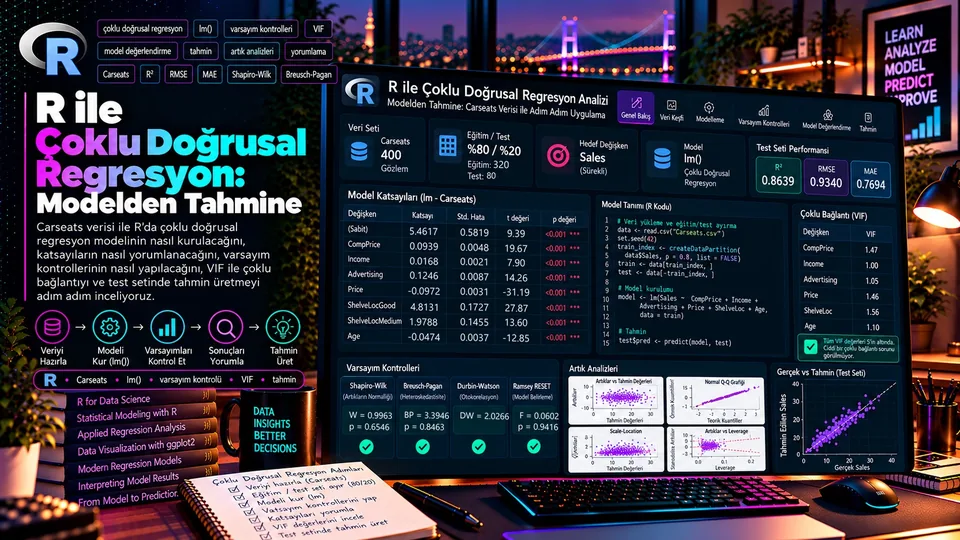
Bir regresyon modelini R'da kurmak tek satır. Asıl iş o satırdan sonra başlıyor: katsayılar ne anlatıyor, varsayımlar sağlanıyor mu, model görmediği veride ne kadar iyi çalışıyor?
Serinin bu ikinci yazısında ilk yazıda hazırladığımız Carseats verisi üzerinde çoklu doğrusal regresyon kuruyorum: modelden katsayı yorumuna, varsayım kontrolünden test setindeki gerçek performansa kadar.
“Yüksek R² iyi bir model demek değildir; yalnızca modelin eğitim verisine iyi uyduğu anlamına gelir.”
1. Modeli Kurmak
Çoklu doğrusal regresyonun genel biçimi şu:
Carseats verisinde hedef Sales, yani mağaza başına satış. Veriyi %80 eğitim / %20 test olarak ayırıp modeli yalnızca eğitim setiyle kuruyoruz.
library(ISLR)
data(Carseats)

set.seed(5364)
idx <- sample(seq_len(nrow(Carseats)), size = floor(0.8 * nrow(Carseats)))
train <- Carseats[idx, ]
test  <- Carseats[-idx, ]

lm_fit <- lm(Sales ~ CompPrice + Income + Advertising + Price + ShelveLoc + Age,
             data = train)

summary(lm_fit)Coefficients:
Estimate Std. Error t value Pr(>|t|)
(Intercept) 5.461708 0.581852 9.387 < 2e-16 ***
CompPrice 0.093870 0.004771 19.674 < 2e-16 ***
Income 0.016768 0.002122 7.902 4.76e-14 ***
Advertising 0.124613 0.008737 14.263 < 2e-16 ***
Price -0.097200 0.003116 -31.192 < 2e-16 ***
ShelveLocGood 4.813149 0.172728 27.866 < 2e-16 ***
ShelveLocMedium 1.978825 0.145542 13.596 < 2e-16 ***
Age -0.047426 0.003690 -12.852 < 2e-16 ***
Residual standard error: 1.044 on 312 degrees of freedom
Multiple R-squared: 0.8719, Adjusted R-squared: 0.869
F-statistic: 303.4 on 7 and 312 DF, p-value: < 2.2e-16Modelin tamamı anlamlı: F istatistiği 303,4 ve p-değeri 2,2e−16'dan küçük. Yedi değişkenin yedisi de tek tek anlamlı. Düzeltilmiş R² 0,869, yani eğitim setindeki satış değişkenliğinin yaklaşık %87'si bu yedi değişkenle açıklanıyor.
2. Katsayıları Yorumlamak
Modelin denklem hâli şöyle:
Her katsayı, diğer değişkenler sabitken ilgili değişkendeki bir birimlik artışın satışa etkisini gösterir.
| Değişken | Katsayı | Yorum |
|---|---|---|
Price | −0,097 | Fiyat 1 birim artınca satış ~0,097 bin adet düşüyor. En güçlü negatif etki. |
CompPrice | +0,094 | Rakibin fiyatı arttıkça bizim satışımız artıyor — beklenen yönde. |
ShelveLoc (Good) | +4,813 | Raf konumu "Bad" yerine "Good" olduğunda satış ortalama 4,81 bin adet daha yüksek. |
ShelveLoc (Medium) | +1,979 | Aynı karşılaştırma "Medium" için; etki "Good"un yaklaşık %41'i. |
Advertising | +0,125 | Reklam bütçesindeki her bin dolar satışa ~0,125 bin adet katkı veriyor. |
Age | −0,047 | Bölgenin ortalama yaşı arttıkça satış hafifçe düşüyor. |
Income | +0,017 | Gelir düzeyinin etkisi anlamlı ama küçük. |
ShelveLoc üç seviyeli bir faktör ama tabloda yalnızca iki katsayı var. Çünkü R, alfabetik olarak ilk seviyeyi (Bad) referans kategori seçer ve diğerlerini ona göre kodlar. Yani 4,813 "Good'un mutlak etkisi" değil, "Good, Bad'e göre ne kadar fazla" demektir. Referansı değiştirmek istersen relevel() kullanabilirsin.Buradaki en çarpıcı bulgu raf konumu: pazarlama bütçesini artırmak yerine ürünü iyi bir rafa koymak, bu modele göre çok daha büyük bir fark yaratıyor. 4,81 bin adetlik etkiyi reklamla yakalamak için yaklaşık 39 bin dolarlık ek bütçe gerekirdi.
Hangi değişken daha önemli?
Tablodaki katsayılara bakıp "en büyük etki raf konumunda" demek doğru. Ama Advertising (0,125) ile Income (0,017) arasında kıyas yapmak değil. Her katsayı kendi biriminde ölçülüyor: biri bin dolarlık reklam bütçesi, diğeri bin dolarlık gelir, üçüncüsü yıl. Birimler farklıyken sayıların büyüklüğü karşılaştırılamaz.
Çözüm, bütün sayısal değişkenleri ortak bir ölçeğe çekip modeli yeniden kurmak. Standartlaştırılmış katsayı şu sorunun cevabıdır: ilgili değişken bir standart sapma arttığında satış kaç standart sapma değişiyor?
olcekli <- train
sayisal <- c("Sales", "CompPrice", "Income",
             "Advertising", "Price", "Age")
olcekli[sayisal] <- lapply(olcekli[sayisal], scale)

round(coef(lm(Sales ~ CompPrice + Income + Advertising +
Price + ShelveLoc + Age, data = olcekli))[-1], 3)| Değişken | Ham katsayı | Standartlaştırılmış | Sıra |
|---|---|---|---|
ShelveLoc (Good) | +4,813 | +1,669 | 1 |
Price | −0,097 | −0,791 | 2 |
ShelveLoc (Medium) | +1,979 | +0,686 | 3 |
CompPrice | +0,094 | +0,496 | 4 |
Advertising | +0,125 | +0,292 | 5 |
Age | −0,047 | −0,265 | 6 |
Income | +0,017 | +0,162 | 7 |
Sıralama ham katsayılarınkinden farklı. Ham tabloda CompPrice (0,094) ile Price (−0,097) neredeyse eşit görünüyordu; standartlaştırınca Price'ın etkisi CompPrice'ınkinin yaklaşık 1,6 katı çıkıyor. Sebebi basit: rakibin fiyatı daha dar bir aralıkta değişiyor, dolayısıyla pratikte yarattığı fark daha küçük.
Reklamın yeri de netleşiyor. Ham katsayısı Income'ınkinin yedi katı ama standartlaştırılmış etkisi yalnızca 1,8 katı — çünkü gelir çok daha geniş bir aralıkta oynuyor. "Katsayısı büyük" ile "etkisi büyük" aynı şey değil.
ShelveLoc bir kukla değişken; onu standartlaştırmak anlamsız olurdu. Tablodaki +1,669 şu demek: raf konumu Bad yerine Good olduğunda satış 1,67 standart sapma artıyor. Bu, herhangi bir sayısal değişkende bir standart sapmalık değişimin yaratacağı etkiden büyük — raf konumu hikâyesi standartlaştırılmış ölçekte daha da güçleniyor.3. Varsayım Kontrolü
Doğrusal regresyonun dört temel varsayımı var ve hiçbiri "modelin çalışması" ile ilgili değil — hepsi katsayılara ve p-değerlerine güvenip güvenemeyeceğinle ilgili.
Doğrusallık
Bağımsız değişkenlerle hedef arasındaki ilişki doğrusal olmalı.
Hataların normalliği
Artıklar normal dağılmalı — değişkenlerin kendisi değil.
Sabit varyans
Artıkların yayılımı tahmin değerine göre değişmemeli.
Bağımsızlık
Artıklar birbirinden bağımsız olmalı; otokorelasyon bulunmamalı.
par(mfrow = c(2, 2))
plot(lm_fit)
par(mfrow = c(1, 1))

# Artiklarin normalligi
shapiro.test(residuals(lm_fit))

# Otokorelasyon
library(lmtest)
dwtest(lm_fit)

# Degisen varyans
bptest(lm_fit)
plot(lm_fit) dört grafik üretir ve her biri bir varsayıma bakar:
| Grafik | Neye bakar? | İstenen görünüm |
|---|---|---|
| Residuals vs Fitted | Doğrusallık | Yatay bant; eğrilik veya huni yok. |
| Q-Q Residuals | Artıkların normalliği | Noktalar köşegen çizgi üzerinde. |
| Scale-Location | Sabit varyans | Yatay çizgi; yayılım tahmine göre değişmiyor. |
| Residuals vs Leverage | Etkili gözlemler | Cook uzaklığı sınırlarını aşan nokta yok. |
Grafikten teste: varsayımları sayıyla sınamak
Dört grafik iyi bir ilk bakış, ama göz kararıdır. "Bu bant yeterince yatay mı?" sorusunun cevabı bakan kişiye göre değişir. Her varsayımın bir de resmi testi var ve raporda sayı yazmak, grafiğe bakıp "sorun görünmüyor" demekten daha savunulabilir.
e <- residuals(lm_fit)

# 1) Hatalarin normalligi
shapiro.test(e)                 # W = 0.9963, p = 0.6546

# 2) Sabit varyans - Breusch-Pagan (LM = n * R2)
yardimci <- lm(I(e^2) ~ CompPrice + Income + Advertising +
                 Price + ShelveLoc + Age, data = train)
LM <- length(e) * summary(yardimci)$r.squared     # 3.3946
pchisq(LM, df = 7, lower.tail = FALSE)          # 0.8463

# 3) Bagimsizlik - Durbin-Watson
sum(diff(e)^2) / sum(e^2)                     # 2.0266

# 4) Model bicimi - Ramsey RESET
yhat <- fitted(lm_fit)
genis <- lm(Sales ~ CompPrice + Income + Advertising + Price +
              ShelveLoc + Age + I(yhat^2) + I(yhat^3), data = train)
anova(lm_fit, genis) # F = 0.060, p = 0.9416| Varsayım | Test | İstatistik | p-değeri | Karar |
|---|---|---|---|---|
| Hataların normalliği | Shapiro-Wilk | W = 0,9963 | 0,655 | Normallik reddedilemez |
| Sabit varyans | Breusch-Pagan | LM = 3,395 (sd = 7) | 0,846 | Değişen varyans yok |
| Bağımsızlık | Durbin-Watson | d = 2,027 | — | 2'ye çok yakın; otokorelasyon yok |
| Model biçimi | Ramsey RESET | F = 0,060 (2; 310) | 0,942 | Eksik doğrusal olmayan terim yok |
Dördü de temiz. Artıkların çarpıklığı 0,124, basıklığı 3,013 — normal dağılımın 0 ve 3 referans değerlerine neredeyse birebir oturuyor. Yani bu modelde katsayılara ve p-değerlerine güvenmek için bir engel yok.
Peki varsayımlardan biri sağlanmasaydı ne yapardık? Her birinin standart bir cevabı var:
| Sorun | Belirtisi | Yaygın çözüm |
|---|---|---|
| Doğrusal olmayan ilişki | RESET anlamlı; Residuals vs Fitted grafiğinde eğrilik. | Polinom terim, log dönüşümü veya spline eklemek. |
| Değişen varyans | Breusch-Pagan anlamlı; artıklarda huni görüntüsü. | Hedefi log'lamak, ağırlıklı EKK veya sağlam (HC) standart hatalar. |
| Normal olmayan artıklar | Shapiro anlamlı; Q-Q grafiğinde kuyruk sapması. | Aykırı değerleri incelemek; büyük örneklemde bootstrap güven aralığı. |
| Otokorelasyon | Durbin-Watson 2'den belirgin uzak. | Zaman boyutunu modele katmak; ARIMA veya karma model. |
| Etkili gözlem | Cook uzaklığı yüksek birkaç nokta. | Veri hatası mı diye bakmak; modeli o gözlemler olmadan da raporlamak. |
Çoklu doğrusal bağlantı
Bağımsız değişkenler birbiriyle yüksek ilişkiliyse katsayılar kararsızlaşır: işaretleri değişebilir, standart hataları şişer. Ölçüsü VIF:
Burada R²j, j'inci değişkenin diğer tüm bağımsız değişkenlerle kurulan regresyonundaki R² değeridir. Pratik eşik genellikle 5 veya 10.
library(car)
vif(lm_fit)

# Sonuc:
# CompPrice   1.546
# Income      1.022
# Advertising 1.018
# Price       1.568
# Age         1.033
Bütün değerler 1,0–1,6 aralığında, yani eşiklerin çok altında. Bu veri setinde çoklu doğrusal bağlantı sorunu yok — katsayılar güvenle yorumlanabilir.
4. Test Setinde Tahmin
Model eğitim verisinde iyi görünüyor. Asıl soru: hiç görmediği 80 mağazada ne yapıyor?
tahmin <- predict(lm_fit, newdata = test)

rmse <- sqrt(mean((test$Sales - tahmin)^2))
mae  <- mean(abs(test$Sales - tahmin))
r2   <- 1 - sum((test$Sales - tahmin)^2) /
             sum((test$Sales - mean(test$Sales))^2)

cat(sprintf("RMSE=%.4f MAE=%.4f R2=%.4f\n", rmse, mae, r2))
# RMSE=0.9340 MAE=0.7694 R2=0.8639| Ölçü | Eğitim | Test | Yorum |
|---|---|---|---|
| R² | 0,8719 | 0,8639 | Fark 0,008 — aşırı öğrenme yok. |
| RMSE | 1,0308 | 0,9340 | Test hatası eğitimden bile düşük. |
| MAE | — | 0,7694 | Ortalama sapma ~770 adet. |
Test hatasının eğitim hatasından düşük çıkması ilk bakışta tuhaf görünür ama normaldir: 80 gözlemlik bir test setinde rastlantısal olarak "kolay" mağazalar toplanmış olabilir. Önemli olan iki değerin birbirine yakın olması — aralarında büyük fark olsaydı aşırı öğrenmeden şüphelenirdik.
Sales değişkeninin ortalaması 7,5 ve standart sapması yaklaşık 2,8. Yani model, ortalama satışın yaklaşık %12'si kadar bir hatayla tahmin yapıyor ve hedefin kendi değişkenliğinin üçte birinin altında bir hata üretiyor.Tek bir mağaza için tahmin ne kadar belirsiz?
RMSE bütün test setinin ortalama hatasını verir. Ama masada oturan soru genellikle şudur: "Şu mağaza için tahminin ne?" Tek bir sayı bu soruya eksik cevap verir; sayının etrafındaki belirsizliği de söylemek gerekir. R iki farklı aralık üretir ve ikisi aynı şey değildir.
ornek <- data.frame(CompPrice = 125, Income = 70, Advertising = 10,
                     Price = 115, ShelveLoc = "Good", Age = 50)

predict(lm_fit, ornek, interval = "confidence")
#      fit      lwr      upr
# 1 10.879   10.634   11.125

predict(lm_fit, ornek, interval = "prediction")
#      fit      lwr      upr
# 1 10.879 8.811 12.948| Aralık | Neyi tahmin eder? | %95 aralık | Genişlik |
|---|---|---|---|
| Güven aralığı | Bu profildeki mağazaların ortalama satışı | 10,63 – 11,12 | 0,49 |
| Tahmin aralığı | Tek bir mağazanın satışı | 8,81 – 12,95 | 4,14 |
Fark sekiz kattan fazla ve sebebi matematiksel: güven aralığı yalnızca katsayı tahminlerindeki belirsizliği taşır. Tahmin aralığı buna bir de indirgenemez hatayı ekler — modelin asla açıklayamayacağı, mağazaya özgü rastgelelik. Bu modelde artık standart hatası σ = 1,044; tahmin aralığının yaklaşık 2 × 1,96 × 1,044 ≈ 4,09'luk genişliği oradan geliyor.
5. Modeli Geliştirmek
İlk modelde yedi değişken var; oysa Carseats'te on tane bağımsız değişken bulunuyor. Eksik olanlar — Population, Education, Urban ve US — bilerek dışarıda bırakıldı: tam modelde hiçbiri anlamlı çıkmıyordu.
| Yaklaşım | Ne yapar? | Dikkat |
|---|---|---|
Adım adım seçim (step()) | AIC'ye göre değişken ekler/çıkarır. | Aynı veriyle hem seçim hem değerlendirme yapılırsa iyimser sonuç verir. |
Ridge / Lasso (glmnet) | Katsayıları cezalandırarak küçültür. | Çoklu bağlantı varsa veya değişken sayısı fazlaysa değerli. |
| Çapraz doğrulama | Performansı tek bir bölünmeye bağlamaz. | Küçük veri setlerinde tek test setinden çok daha güvenilir. |
| Etkileşim terimleri | Değişkenlerin birlikte etkisini modeller. | Yorumlanabilirlik hızla düşer; gerekçesi olmalı. |
library(caret)

ctrl <- trainControl(method = "cv", number = 10)

cv_fit <- train(Sales ~ CompPrice + Income + Advertising + Price + ShelveLoc + Age,
                data = train,
                method = "lm",
                trControl = ctrl)

cv_fit$results
Çapraz doğrulama, performansı tek bir rastgele bölünmeye bağlı olmaktan çıkarır. 400 gözlemlik bir veri setinde tek test setinin verdiği sayı, seçilen tohuma göre belirgin biçimde oynayabilir.
Bu veri setinde 10 katlı çapraz doğrulamayı çalıştırınca ortaya çıkan tablo şu:
| Ölçü | Ortalama | Standart sapma | En iyi kat | En kötü kat |
|---|---|---|---|---|
| RMSE | 1,0280 | 0,1006 | 0,8325 | 1,1682 |
| R² | 0,8595 | 0,0434 | — | — |
Dikkat çeken şey şu: tek test setinde ölçtüğümüz RMSE 0,934'tü — çapraz doğrulama dağılımının iyimser ucunda. On katın en iyisi 0,833, en kötüsü 1,168; aradaki 0,34'lük fark tamamen hangi gözlemlerin teste düştüğünden geliyor. Yani "test RMSE'si 0,934" cümlesi yanlış değil ama şanslı bir bölünmenin ürünü.
Dışarıda bıraktığımız dört değişken gerçekten gereksiz mi?
"Hiçbiri anlamlı çıkmadı" demek yeterli bir gerekçe değil; tek tek anlamsız olan değişkenler birlikte anlamlı olabilir. Doğru araç iç içe (nested) F testi: küçük model büyük modelin kısıtlanmış hâli olduğuna göre, eklenen dört değişken açıklama gücüne topluca katkı yapıyor mu?
tam <- lm(Sales ~ ., data = train)
anova(lm_fit, tam)

# Res.Df    RSS Df Sum of Sq      F Pr(>F)
#    312 340.02
#    308 334.82  4    5.2008 1.1961 0.3125

AIC(lm_fit, tam) # 945.54 vs 948.61| Ölçü | Yedi değişkenli model | Tam model (on değişken) |
|---|---|---|
| Artık kareler toplamı | 340,02 | 334,82 |
| Düzeltilmiş R² | 0,8690 | 0,8694 |
| AIC | 945,54 | 948,61 |
| F testi | F = 1,196 (4; 308) · p = 0,313 | |
p = 0,313; dört değişken birlikte de anlamlı bir katkı yapmıyor. Düzeltilmiş R² yalnızca 0,0004 artıyor, AIC ise kötüleşiyor. Küçük modeli tercih etmek burada bir üslup tercihi değil, verinin söylediği şey.
6. Sık Yapılan Hatalar
| Hata | Neden problem? | Daha iyi yaklaşım |
|---|---|---|
| R²'ye tek başına bakmak | Değişken ekledikçe her zaman artar. | Düzeltilmiş R² ve test hatasını birlikte değerlendirmek. |
| Varsayımları kontrol etmemek | Katsayı ve p-değerleri güvenilmez olur. | plot(lm_fit) ve VIF'i rutine almak. |
| Katsayıyı nedensellik sanmak | Regresyon ilişkiyi ölçer, nedeni değil. | "İlişkili" ile "sebep oluyor"u ayırmak. |
| Referans kategoriyi atlamak | Kategorik katsayılar yanlış yorumlanır. | Hangi seviyenin referans olduğunu kontrol etmek. |
| Eğitim verisiyle değerlendirmek | Performans olduğundan iyi görünür. | predict(newdata = test) kullanmak. |
| Model dışına tahmin yapmak | Veri aralığı dışında model geçerli değildir. | Tahminleri gözlenen aralıkla sınırlamak. |
Sonuç
Çoklu doğrusal regresyon, makine öğrenmesinin en basit modellerinden biri ama yorumlanabilirliği onu hâlâ değerli kılıyor. Bu örnekte model eğitim setinde %87, test setinde %86 açıklayıcılık üretti ve varsayımların hepsi sağlandı.
Asıl iş çıktısı ise katsayılarda: raf konumunu iyileştirmek, bu veride reklam bütçesini artırmaktan çok daha güçlü bir kaldıraç. Bir modelin değeri ürettiği R²'de değil, hangi kararı desteklediğinde.
“Modeli kurmak bir satır; ona güvenip güvenemeyeceğine karar vermek bütün bir bölüm.”
Fitting a regression model in R takes one line. The real work starts after that line: what do the coefficients say, do the assumptions hold, and how well does the model perform on data it has never seen?
In this second post of the series I fit a multiple linear regression on the Carseats data we prepared in the first post — from the model to coefficient interpretation, and from assumption checks to real performance on the test set.
“A high R² does not mean a good model; it only means the model fits the training data well.”
1. Fitting the Model
The general form of multiple linear regression is:
In the Carseats data the target is Sales, unit sales per store. We split 80% training / 20% test and fit the model on the training set only.
library(ISLR)
data(Carseats)

set.seed(5364)
idx <- sample(seq_len(nrow(Carseats)), size = floor(0.8 * nrow(Carseats)))
train <- Carseats[idx, ]
test  <- Carseats[-idx, ]

lm_fit <- lm(Sales ~ CompPrice + Income + Advertising + Price + ShelveLoc + Age,
             data = train)

summary(lm_fit)Coefficients:
Estimate Std. Error t value Pr(>|t|)
(Intercept) 5.461708 0.581852 9.387 < 2e-16 ***
CompPrice 0.093870 0.004771 19.674 < 2e-16 ***
Income 0.016768 0.002122 7.902 4.76e-14 ***
Advertising 0.124613 0.008737 14.263 < 2e-16 ***
Price -0.097200 0.003116 -31.192 < 2e-16 ***
ShelveLocGood 4.813149 0.172728 27.866 < 2e-16 ***
ShelveLocMedium 1.978825 0.145542 13.596 < 2e-16 ***
Age -0.047426 0.003690 -12.852 < 2e-16 ***
Residual standard error: 1.044 on 312 degrees of freedom
Multiple R-squared: 0.8719, Adjusted R-squared: 0.869
F-statistic: 303.4 on 7 and 312 DF, p-value: < 2.2e-16The model as a whole is significant: F = 303.4 with a p-value below 2.2e−16. All seven variables are individually significant too. Adjusted R² is 0.869, so roughly 87% of the variation in sales in the training set is explained by these seven variables.
2. Interpreting the Coefficients
Written out, the model is:
Each coefficient shows the effect of a one-unit increase in that variable on sales, holding the other variables constant.
| Variable | Coefficient | Interpretation |
|---|---|---|
Price | −0.097 | A one-unit price increase lowers sales by ~0.097 thousand units. The strongest negative effect. |
CompPrice | +0.094 | As the competitor's price rises, our sales rise — the expected direction. |
ShelveLoc (Good) | +4.813 | Moving shelving from "Bad" to "Good" is worth 4.81 thousand units on average. |
ShelveLoc (Medium) | +1.979 | The same comparison for "Medium"; about 41% of the "Good" effect. |
Advertising | +0.125 | Every thousand dollars of local advertising adds ~0.125 thousand units. |
Age | −0.047 | Sales fall slightly as the average local age rises. |
Income | +0.017 | Income level has a significant but small effect. |
ShelveLoc has three levels but only two coefficients appear. R takes the alphabetically first level (Bad) as the reference category and codes the others against it. So 4.813 is not "the absolute effect of Good" but "how much more Good is than Bad". Use relevel() to change the reference.The striking finding here is shelving location: according to this model, putting the product on a good shelf makes a far bigger difference than raising the advertising budget. Matching a 4.81 thousand-unit effect through advertising alone would take roughly 39 thousand dollars of extra spend.
Which variable matters most?
Reading the table and saying "shelf location has the largest effect" is fair. Comparing Advertising (0.125) with Income (0.017) is not. Each coefficient is measured in its own unit: one is a thousand dollars of advertising budget, another a thousand dollars of income, a third is years. When the units differ, the size of the numbers cannot be compared.
The fix is to put every numeric variable on a common scale and refit. A standardised coefficient answers a different question: when this variable rises by one standard deviation, how many standard deviations does sales move?
scaled <- train
numeric_vars <- c("Sales", "CompPrice", "Income",
                   "Advertising", "Price", "Age")
scaled[numeric_vars] <- lapply(scaled[numeric_vars], scale)

round(coef(lm(Sales ~ CompPrice + Income + Advertising +
Price + ShelveLoc + Age, data = scaled))[-1], 3)| Variable | Raw coefficient | Standardised | Rank |
|---|---|---|---|
ShelveLoc (Good) | +4.813 | +1.669 | 1 |
Price | −0.097 | −0.791 | 2 |
ShelveLoc (Medium) | +1.979 | +0.686 | 3 |
CompPrice | +0.094 | +0.496 | 4 |
Advertising | +0.125 | +0.292 | 5 |
Age | −0.047 | −0.265 | 6 |
Income | +0.017 | +0.162 | 7 |
The ordering is not the one the raw table suggested. There CompPrice (0.094) and Price (−0.097) looked almost equal; on a common scale Price turns out to be roughly 1.6 times stronger. The reason is simple: the competitor's price varies over a narrower range, so in practice it moves sales less.
Advertising lands in its proper place too. Its raw coefficient is seven times that of Income, but its standardised effect is only 1.8 times larger — because income varies over a far wider range. "Large coefficient" and "large effect" are not the same claim.
ShelveLoc is a dummy, and standardising it would make no sense. The +1.669 in the table reads as: moving shelf location from Bad to Good raises sales by 1.67 standard deviations. That is more than a one-standard-deviation move in any numeric variable buys — the shelf story gets stronger, not weaker, on the standardised scale.3. Checking the Assumptions
Linear regression has four core assumptions, and none of them is about whether the model "works" — they are all about whether you can trust the coefficients and p-values.
Linearity
The relationship between predictors and target should be linear.
Normal errors
The residuals should be normally distributed — not the variables themselves.
Constant variance
Residual spread should not change with the fitted value.
Independence
Residuals should be independent; no autocorrelation.
par(mfrow = c(2, 2))
plot(lm_fit)
par(mfrow = c(1, 1))

# Normality of residuals
shapiro.test(residuals(lm_fit))

# Autocorrelation
library(lmtest)
dwtest(lm_fit)

# Heteroscedasticity
bptest(lm_fit)
plot(lm_fit) produces four plots, each addressing one assumption:
| Plot | What it checks | What you want to see |
|---|---|---|
| Residuals vs Fitted | Linearity | A flat band; no curvature or funnel. |
| Q-Q Residuals | Normality of residuals | Points along the diagonal line. |
| Scale-Location | Constant variance | A horizontal line; spread independent of the fitted value. |
| Residuals vs Leverage | Influential observations | No point beyond the Cook's distance contours. |
From plots to tests: checking assumptions with numbers
The four plots are a good first look, but they are a judgement call. Whether a band is "flat enough" depends on who is looking. Each assumption also has a formal test, and writing a number in the report is easier to defend than "nothing looked wrong".
e <- residuals(lm_fit)

# 1) Normality of errors
shapiro.test(e)                 # W = 0.9963, p = 0.6546

# 2) Constant variance - Breusch-Pagan (LM = n * R2)
aux <- lm(I(e^2) ~ CompPrice + Income + Advertising +
            Price + ShelveLoc + Age, data = train)
LM <- length(e) * summary(aux)$r.squared          # 3.3946
pchisq(LM, df = 7, lower.tail = FALSE)          # 0.8463

# 3) Independence - Durbin-Watson
sum(diff(e)^2) / sum(e^2)                     # 2.0266

# 4) Functional form - Ramsey RESET
yhat <- fitted(lm_fit)
wider <- lm(Sales ~ CompPrice + Income + Advertising + Price +
              ShelveLoc + Age + I(yhat^2) + I(yhat^3), data = train)
anova(lm_fit, wider) # F = 0.060, p = 0.9416| Assumption | Test | Statistic | p-value | Verdict |
|---|---|---|---|---|
| Normality of errors | Shapiro-Wilk | W = 0.9963 | 0.655 | Normality not rejected |
| Constant variance | Breusch-Pagan | LM = 3.395 (df = 7) | 0.846 | No heteroscedasticity |
| Independence | Durbin-Watson | d = 2.027 | — | Very close to 2; no autocorrelation |
| Functional form | Ramsey RESET | F = 0.060 (2, 310) | 0.942 | No missing non-linear term |
All four are clean. The residuals have a skewness of 0.124 and a kurtosis of 3.013 — essentially the 0 and 3 of a normal distribution. Nothing stands in the way of trusting the coefficients and their p-values here.
And if one of the assumptions had failed? Each has a standard answer:
| Problem | Symptom | Common remedy |
|---|---|---|
| Non-linear relationship | RESET significant; curvature in Residuals vs Fitted. | Polynomial terms, a log transform or splines. |
| Heteroscedasticity | Breusch-Pagan significant; funnel shape in the residuals. | Log the target, weighted least squares, or robust (HC) standard errors. |
| Non-normal residuals | Shapiro significant; tails drifting off the Q-Q line. | Inspect outliers; use bootstrap intervals in large samples. |
| Autocorrelation | Durbin-Watson clearly away from 2. | Bring the time dimension into the model; ARIMA or mixed models. |
| Influential observations | A few points with high Cook's distance. | Check for data errors; report the model with and without them. |
Multicollinearity
When predictors are strongly related to one another the coefficients become unstable: signs can flip and standard errors inflate. The measure is VIF:
Here R²j is the R² from regressing the j-th predictor on all the others. The common thresholds are 5 or 10.
library(car)
vif(lm_fit)

# Result:
# CompPrice   1.546
# Income      1.022
# Advertising 1.018
# Price       1.568
# Age         1.033
Every value sits between 1.0 and 1.6, far below the thresholds. There is no multicollinearity problem in this data set — the coefficients can be interpreted with confidence.
4. Predicting on the Test Set
The model looks good on training data. The real question: what does it do on 80 stores it has never seen?
pred <- predict(lm_fit, newdata = test)

rmse <- sqrt(mean((test$Sales - pred)^2))
mae  <- mean(abs(test$Sales - pred))
r2   <- 1 - sum((test$Sales - pred)^2) /
             sum((test$Sales - mean(test$Sales))^2)

cat(sprintf("RMSE=%.4f MAE=%.4f R2=%.4f\n", rmse, mae, r2))
# RMSE=0.9340 MAE=0.7694 R2=0.8639| Measure | Training | Test | Reading |
|---|---|---|---|
| R² | 0.8719 | 0.8639 | A gap of 0.008 — no overfitting. |
| RMSE | 1.0308 | 0.9340 | Test error is even lower than training error. |
| MAE | — | 0.7694 | Average deviation of ~770 units. |
A test error below the training error looks odd at first but is perfectly normal: in a test set of 80 observations, "easy" stores can land together by chance. What matters is that the two numbers are close — a large gap would point to overfitting.
Sales has a mean of about 7.5 and a standard deviation of roughly 2.8. So the model predicts with an error of about 12% of average sales, and under a third of the target's own variability.How uncertain is a single store's prediction?
RMSE gives the average error across the whole test set. But the question on the table is usually narrower: "what do you predict for this store?" A single number answers it incompletely; the uncertainty around that number belongs in the answer too. R produces two different intervals, and they are not the same thing.
new_store <- data.frame(CompPrice = 125, Income = 70, Advertising = 10,
                         Price = 115, ShelveLoc = "Good", Age = 50)

predict(lm_fit, new_store, interval = "confidence")
#      fit      lwr      upr
# 1 10.879   10.634   11.125

predict(lm_fit, new_store, interval = "prediction")
#      fit      lwr      upr
# 1 10.879 8.811 12.948| Interval | What it estimates | 95% range | Width |
|---|---|---|---|
| Confidence | Average sales for stores with this profile | 10.63 – 11.12 | 0.49 |
| Prediction | Sales of one specific store | 8.81 – 12.95 | 4.14 |
The gap is more than eightfold, and the reason is mathematical: the confidence interval carries only the uncertainty in the estimated coefficients. The prediction interval adds the irreducible error on top — the store-specific randomness the model can never explain. Here the residual standard error is σ = 1.044, and the prediction interval's width of roughly 2 × 1.96 × 1.044 ≈ 4.09 comes straight from it.
5. Improving the Model
The first model has seven variables, while Carseats offers ten predictors. The missing ones — Population, Education, Urban and US — were left out deliberately: none of them was significant in the full model.
| Approach | What it does | Watch out for |
|---|---|---|
Stepwise selection (step()) | Adds and removes variables by AIC. | Selecting and evaluating on the same data gives optimistic results. |
Ridge / Lasso (glmnet) | Shrinks coefficients through a penalty. | Valuable with multicollinearity or many predictors. |
| Cross-validation | Stops performance depending on a single split. | Far more reliable than one test set on small data. |
| Interaction terms | Models the joint effect of variables. | Interpretability drops quickly; there should be a reason. |
library(caret)

ctrl <- trainControl(method = "cv", number = 10)

cv_fit <- train(Sales ~ CompPrice + Income + Advertising + Price + ShelveLoc + Age,
                data = train,
                method = "lm",
                trControl = ctrl)

cv_fit$results
Cross-validation stops performance from hanging on a single random split. With 400 observations, the number a single test set reports can move noticeably with the chosen seed.
Running 10-fold cross-validation on this dataset gives the following picture:
| Measure | Mean | Std. deviation | Best fold | Worst fold |
|---|---|---|---|---|
| RMSE | 1.0280 | 0.1006 | 0.8325 | 1.1682 |
| R² | 0.8595 | 0.0434 | — | — |
One detail stands out: the RMSE we measured on the single test set was 0.934 — at the optimistic end of the cross-validated distribution. The best of the ten folds comes in at 0.833, the worst at 1.168, and the 0.34 between them is purely a matter of which observations landed in the test fold. "Test RMSE is 0.934" is not wrong, but it is the product of a lucky split.
Were those four excluded variables really useless?
"None of them was significant" is not a sufficient argument; variables that are individually insignificant can matter jointly. The right tool is a nested F test: since the smaller model is a restricted version of the larger one, do the four extra variables add explanatory power as a group?
full <- lm(Sales ~ ., data = train)
anova(lm_fit, full)

# Res.Df    RSS Df Sum of Sq      F Pr(>F)
#    312 340.02
#    308 334.82  4    5.2008 1.1961 0.3125

AIC(lm_fit, full) # 945.54 vs 948.61| Measure | Seven-variable model | Full model (ten variables) |
|---|---|---|
| Residual sum of squares | 340.02 | 334.82 |
| Adjusted R² | 0.8690 | 0.8694 |
| AIC | 945.54 | 948.61 |
| F test | F = 1.196 (4, 308) · p = 0.313 | |
p = 0.313: the four variables add nothing as a group either. Adjusted R² rises by 0.0004 while AIC actually gets worse. Preferring the smaller model here is not a stylistic choice — it is what the data says.
6. Common Mistakes
| Mistake | Why it is a problem | A better approach |
|---|---|---|
| Looking only at R² | It always rises as variables are added. | Use adjusted R² together with test error. |
| Skipping the assumptions | Coefficients and p-values become unreliable. | Make plot(lm_fit) and VIF routine. |
| Reading a coefficient as causation | Regression measures association, not cause. | Separate "associated with" from "causes". |
| Ignoring the reference category | Categorical coefficients get misread. | Check which level is the reference. |
| Evaluating on training data | Performance looks better than it is. | Use predict(newdata = test). |
| Extrapolating | The model does not hold outside the observed range. | Keep predictions within the observed range. |
Conclusion
Multiple linear regression is one of the simplest models in machine learning, but its interpretability keeps it valuable. Here the model explained 87% of the variation on the training set and 86% on the test set, with every assumption satisfied.
The real business output is in the coefficients: improving shelving location is a far stronger lever in this data than increasing the advertising budget. A model's worth lies not in the R² it reports but in the decision it supports.
“Fitting the model is one line; deciding whether to trust it is a whole chapter.”