Hipotez Testi Nedir? p-Value ve İstatistiksel Anlamlılık
Veride gözlenen fark gerçek bir etkiyi mi gösteriyor, yoksa örnekleme dalgalanmasıyla açıklanabilir mi? Hipotez testinin mantığını, p-value'nun ne olup ne olmadığını ve sonuçların gerçek kararlarla ilişkisini anlatıyorum.
- İstatistik
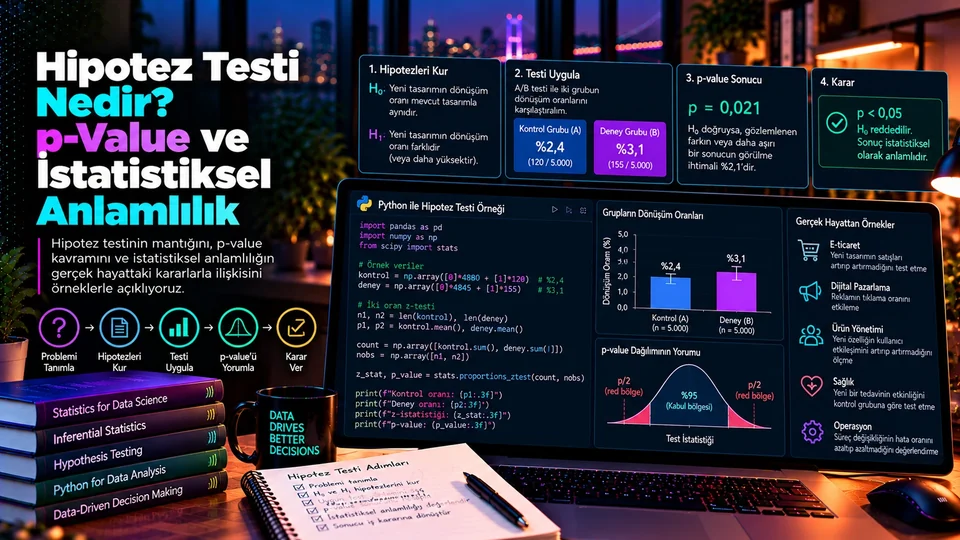
Hipotez testi neyi yanıtlar?
Bir ürün değişikliğinin dönüşümü artırıp artırmadığını, yeni bir eğitim yönteminin başarıya katkı sağlayıp sağlamadığını ya da üretim sürecindeki ortalama ölçümün hedefe uyup uymadığını araştırmak isteyebiliriz. Çoğu durumda tüm nüfusu ölçemeyiz; bir örneklemden yola çıkar ve belirsizliği hesaba katarız.
Hipotez testi, veriyi önceden tanımlanmış bir olasılık modeli altında değerlendirir. Sıfır hipotezi (H₀) genellikle “etki yok” veya “fark yok” varsayımıdır. Alternatif hipotez (H₁), araştırılan farkın ya da etkinin var olduğunu ifade eder.
Test süreci: veriden karara
- Soruyu
Netleştir - Hipotezleri
Kur - Tasarımı
Belirle - α'yı
Seç - Veriyi
Topla - p-value'yu
Yorumla - Kararı
Ver
- Soruyu netleştirin: hangi ölçüm, hangi gruplar, hangi zaman aralığı?
- Hipotezleri kurun: H₀ ve H₁; testin yönlü mü iki yönlü mü olacağı.
- Ölçütü ve tasarımı belirleyin: sonuç değişkeni, örnekleme yöntemi, test ve analiz planı.
- Anlamlılık düzeyini seçin: α, veriyi görmeden önce belirlenen yanlış pozitif toleransı.
- Veriyi toplayın ve test istatistiğini hesaplayın: gerekli varsayımları kontrol edin.
- p-value ve belirsizliği yorumlayın: etki büyüklüğü ve güven aralığıyla birlikte.
- İş kararını verin: istatistiksel bulguyu maliyet, fayda ve riskle birleştirin.
Sıralama tesadüfi değil: dördüncü adıma kadar hiçbir veri görülmez. α'yı ve analiz planını sonuçları gördükten sonra seçmek, testin tüm istatistiksel güvencesini ortadan kaldırır.
p-value tam olarak nedir?
p-value; sıfır hipotezi ve testin varsayımları doğru kabul edildiğinde, gözlenen test istatistiği kadar veya ondan daha uç bir sonucun elde edilme olasılığıdır. İki yönlü testte her iki yöndeki uç sonuçlar hesaba katılır.
Örneğin p = 0,03; H₀ ve model varsayımları geçerliyken, en az gözlenen kadar uç bir veri örüntüsünün %3 olasılıkla görüleceği anlamına gelir. Bu sayı tek başına H₀'ın yanlış olduğunu kanıtlamaz — yalnızca verinin H₀ ile pek uyumlu olmadığını söyler.
p-value eşiği ve α
Önceden α = 0,05 seçilmişse, p < 0,05 sonucu “istatistiksel olarak anlamlı” diye raporlanabilir. Ama bu bir karar kuralıdır; doğanın etkileri anlamlı ve anlamsız diye ikiye ayırdığı bir sınır değildir. p = 0,049 ile p = 0,051 arasında bilimsel açıdan keskin bir uçurum yoktur; ikisi de aynı şeyi, neredeyse aynı güçte söyler.
Uygulamalı örnek: A/B testi
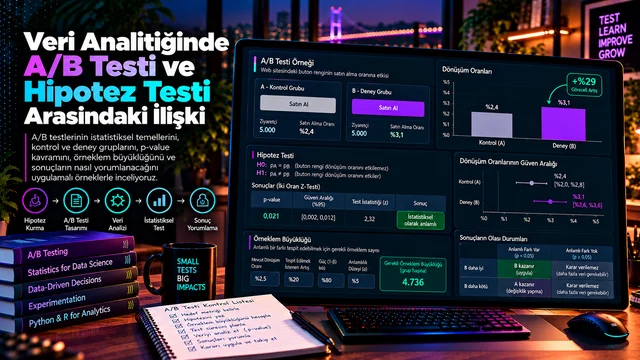
Bir e-ticaret sitesi iki tasarımı karşılaştırsın. Kontrol grubunda 10.000 ziyaretçinin 500'ü, yeni tasarımda 10.000 ziyaretçinin 560'ı satın alma yapsın. Dönüşüm oranları sırasıyla %5,0 ve %5,6; gözlenen mutlak fark 0,6 yüzde puanı.
from statsmodels.stats.proportion import proportions_ztest

basarilar = [560, 500]        # yeni, kontrol
ziyaretler = [10000, 10000]

z, p = proportions_ztest(basarilar, ziyaretler)
fark = basarilar[0] / ziyaretler[0] - basarilar[1] / ziyaretler[1]

print(f"Oran farkı: {fark:.1%}; p-value: {p:.4f}")
Bu veriyle iki oran z-testi z ≈ 1,89 ve p ≈ 0,058 verir — yani yaygın 0,05 eşiğinin hemen üstünde. Fark 0,6 yüzde puan ve göreli olarak %12'lik bir artış olmasına rağmen sonuç “istatistiksel olarak anlamlı” sayılmaz. Bu örnek, eşiğin ne kadar keskin bir ayrım yarattığını iyi gösteriyor: p = 0,058 ile p = 0,048 arasındaki kanıt farkı neredeyse yoktur, ama raporlama dili tamamen değişir. Üstelik ürün ekibinin asıl soruları bunlar bile değil: fark ne kadar güvenilir, başka dönemlerde sürer mi ve getireceği ek gelir uygulama maliyetini karşılar mı?
Testin doğru yorumlanması için grupların rastgele atanması, her kullanıcının yalnızca bir grupta yer alması, ölçümün tutarlı olması ve analizin planlandığı gibi yürütülmesi gerekir. Örnekleme ya da olay kaydı tarafında bir hata varsa p-value o sorunu çözmez — sadece üzerini örter.
İstatistiksel anlamlılık ≠ pratik önem
İstatistiksel anlamlılık, verinin belirli bir model altında H₀ ile ne kadar uyumlu olduğunu özetler. Pratik önem ise etkinin gerçek dünyadaki büyüklüğünü ve değerini sorar. Bir sonuç birinde güçlü, diğerinde değersiz olabilir.
| Durum | Nasıl düşünmeli? |
|---|---|
| Büyük örneklem, çok küçük etki | p küçük çıkabilir; etki geliştirme maliyetini karşılamayabilir. |
| Küçük örneklem, umut verici etki | Belirsizlik geniştir; karar için daha fazla veri gerekir. |
| İstatistiksel olarak anlamlı fark | Etki büyüklüğü, güven aralığı ve uygulama riski yine incelenmeli. |
| Anlamlı çıkmayan sonuç | “Etki kesinlikle yok” demek değildir; testin gücü yetersiz olabilir. |
Sonucu her zaman oran farkı veya ortalama farkı gibi anlaşılır bir etki ölçüsüyle ve güven aralığıyla raporlayın. Güven aralığı, verilerle uyumlu etki değerlerinin ne kadar geniş bir aralıkta olduğunu gösterir; p-value tek başına bu resmi hiçbir zaman vermez.
Tip I hata, Tip II hata ve güç
Tip I hata
Gerçekte etki yokken “var” sonucuna varmak. Uzun vadede oranı α ile sınırlandırılır.
Tip II hata
Gerçek bir etkiyi yakalayamamak. Olasılığı β ile gösterilir.
Test gücü
Belirli büyüklükteki gerçek bir etkiyi saptama olasılığı. Örneklem büyüdükçe artar.
Örneklem büyüklüğü, beklenen etkinin boyutu, verideki değişkenlik ve seçilen α birlikte gücü belirler. Düşük güçlü bir deney iki ayrı şekilde yanıltır: gerçek etkiyi kaçırır, kaçırmadığı durumlarda ise etkiyi olduğundan büyük gösterme eğilimindedir.
Testi sık sık kontrol edip p-value eşiğin altına indiği anda durdurmak yanlış pozitif riskini ciddi biçimde artırır. Analiz planını ve örneklem hedefini önceden belirlemek, bu riski ortadan kaldıran en basit önlemdir.
Yaygın yorumlama hataları
- “p = 0,03 ise H₀'ın doğru olma ihtimali %3'tür” demek.
- “İstatistiksel olarak anlamlıysa etki büyüktür ya da önemlidir” varsaymak.
- p ≥ α sonucunu “iki grup kesinlikle eşittir” diye sunmak.
- Birçok metriği test edip yalnızca anlamlı çıkanı raporlamak.
- İlişkiyi doğrudan nedensellik saymak veya model varsayımlarını hiç kontrol etmemek.
Gerçek hayatta karara nasıl bağlanır?
Önce iki maliyeti ayrı ayrı düşünün: yanlış pozitifin maliyeti ne, gerçek bir etkiyi kaçırmanın maliyeti ne? Bu ikisi çoğu projede eşit değildir ve hangisinden daha çok korktuğunuz α ile güç hedefinizi belirlemeli.
Sonra etki büyüklüğünü, güven aralığını, veri kalitesini, tasarımın güvenilirliğini ve uygulamanın maliyet/faydasını aynı masaya koyun. Kritik kararlarda tek bir p-value'ya yaslanmak yerine bağımsız tekrar, sağlamlık kontrolleri ve alan bilgisi arayın.
Önceden belirlendi mi?
Hipotez, yön ve α veriyi görmeden sabitlenmiş olmalı.
Tasarım net mi?
Örnekleme ve ölçüm planı yazılı; atama birimi analiz birimiyle uyumlu.
Varsayımlar
Bağımsızlık, dağılım ve ölçek varsayımları gözden geçirildi mi?
Etki büyüklüğü
p-value yanında mutlak ve göreli fark raporlandı mı?
Çoklu test
Kaç metrik ve kaç segment test edildi; düzeltme planı var mı?
İş etkisi
Maliyet, fayda ve sınırlamalar raporda açıkça yazıldı mı?
p-value, cevabın tamamı değil bir parçası
Hipotez testi, belirsizlik altındaki veriyi sistematik biçimde değerlendirmeye yarar. İyi kurulmuş bir test, “gözlediğim fark şansla açıklanabilir mi?” sorusuna disiplinli bir cevap verir.
Ama p-value soruya verilen yanıtın yalnızca bir parçasıdır. Sağlam bir karar için tasarım, etki büyüklüğü, güven aralığı, varsayımlar ve gerçek dünyadaki sonuçlar birlikte değerlendirilmelidir. Tek bir sayıya indirgenen her istatistiksel sonuç, er ya da geç yanlış bir kararın gerekçesi olur.
What does a hypothesis test answer?
We may want to know whether a product change raised conversion, whether a new teaching method improved results, or whether the average measurement in a production process meets its target. In most cases we cannot measure the whole population; we start from a sample and account for the uncertainty.
A hypothesis test evaluates the data under a probability model defined in advance. The null hypothesis (H₀) is usually the assumption of “no effect” or “no difference”. The alternative hypothesis (H₁) states that the difference or effect under investigation does exist.
From data to decision
- Clarify the
Question - Set
Hypotheses - Fix the
Design - Choose
α - Collect
Data - Interpret the
p-value - Decide
- Clarify the question: which measurement, which groups, which time window?
- Set the hypotheses: H₀ and H₁, and whether the test is one- or two-sided.
- Fix the metric and the design: outcome variable, sampling method, test and analysis plan.
- Choose the significance level: α, the false-positive tolerance set before seeing any data.
- Collect the data and compute the statistic: check the assumptions it requires.
- Interpret the p-value and the uncertainty: together with effect size and a confidence interval.
- Make the business decision: combine the statistical finding with cost, benefit and risk.
The order is not accidental: no data is seen until step four. Choosing α and the analysis plan after looking at the results destroys the entire statistical guarantee the test provides.
What exactly is a p-value?
The p-value is the probability of obtaining a result as extreme as, or more extreme than, the observed test statistic — assuming the null hypothesis and the test's assumptions hold. In a two-sided test, extremes in both directions count.
For instance p = 0.03 means that, with H₀ and the model assumptions holding, a data pattern at least as extreme as the one observed would be seen 3% of the time. That number alone does not prove H₀ is false — it only says the data is not very compatible with it.
The threshold and α
If α = 0.05 was chosen beforehand, a result of p < 0.05 may be reported as “statistically significant”. But this is a decision rule; it is not a boundary at which nature divides effects into meaningful and meaningless. There is no sharp scientific gulf between p = 0.049 and p = 0.051; both say the same thing with almost the same strength.
A worked example: an A/B test
Suppose an e-commerce site compares two designs. In the control group 500 of 10,000 visitors purchase; with the new design, 560 of 10,000 do. The conversion rates are 5.0% and 5.6%, an observed absolute difference of 0.6 percentage points.
from statsmodels.stats.proportion import proportions_ztest

basarilar = [560, 500]        # new, control
ziyaretler = [10000, 10000]

z, p = proportions_ztest(basarilar, ziyaretler)
fark = basarilar[0] / ziyaretler[0] - basarilar[1] / ziyaretler[1]

print(f"Difference: {fark:.1%}; p-value: {p:.4f}")
On this data the two-proportion z-test gives z ≈ 1.89 and p ≈ 0.058 — just above the conventional 0.05 threshold. Even though the difference is 0.6 percentage points, a relative lift of 12%, the result does not count as “statistically significant”. The example shows how sharp a line the threshold draws: there is almost no difference in evidence between p = 0.058 and p = 0.048, yet the reporting language changes completely. And the product team's real questions are not even these: how reliable is the difference, will it hold in other periods, and does the extra revenue cover the cost of implementing it?
For the test to be interpreted correctly, groups must be randomly assigned, each user must appear in only one group, measurement must be consistent, and the analysis must run as planned. If something is wrong in the sampling or the event logging, the p-value does not fix that problem — it only hides it.
Statistical significance ≠ practical importance
Statistical significance summarises how compatible the data is with H₀ under a given model. Practical importance asks about the size and worth of the effect in the real world. A result can be strong on one and worthless on the other.
| Situation | How to think about it |
|---|---|
| Large sample, very small effect | p may be small; the effect may not cover the development cost. |
| Small sample, promising effect | The uncertainty is wide; a decision needs more data. |
| A statistically significant difference | Effect size, confidence interval and implementation risk still need review. |
| A non-significant result | Does not mean “there is definitely no effect”; the test may be underpowered. |
Always report the result with an intelligible effect measure — a difference in proportions or in means — and a confidence interval. The interval shows how wide a range of effect values is compatible with the data; the p-value alone never gives you that picture.
Type I error, Type II error and power
Type I error
Concluding there is an effect when there is none. Its long-run rate is bounded by α.
Type II error
Failing to detect a real effect. Its probability is denoted β.
Statistical power
The probability of detecting a true effect of a given size. It rises with sample size.
Sample size, the expected size of the effect, the variability in the data and the chosen α together determine power. An underpowered experiment misleads in two separate ways: it misses real effects, and in the cases where it does not, it tends to overstate them.
Checking the test frequently and stopping the moment the p-value drops below the threshold inflates the false-positive risk considerably. Fixing the analysis plan and the target sample size in advance is the simplest way to remove that risk.
Common misinterpretations
- Saying “if p = 0.03 then there is a 3% chance H₀ is true”.
- Assuming “if it is statistically significant, the effect is large or important”.
- Presenting p ≥ α as “the two groups are definitely equal”.
- Testing many metrics and reporting only the one that came out significant.
- Treating an association directly as causation, or never checking the model assumptions.
How does it turn into a real decision?
First consider two costs separately: what does a false positive cost, and what does missing a real effect cost? In most projects these are not equal, and which one you fear more should drive your α and your power target.
Then put effect size, confidence interval, data quality, the reliability of the design and the cost/benefit of implementation on the same table. For critical decisions, look for independent replication, robustness checks and domain knowledge rather than leaning on a single p-value.
Fixed in advance?
Hypothesis, direction and α must be settled before the data is seen.
Is the design clear?
Sampling and measurement plan written down; unit of assignment matches unit of analysis.
Assumptions
Have independence, distribution and scale assumptions been reviewed?
Effect size
Are absolute and relative differences reported next to the p-value?
Multiple testing
How many metrics and segments were tested; is there a correction plan?
Business impact
Are cost, benefit and limitations written explicitly in the report?
The p-value is part of the answer, not all of it
Hypothesis testing exists to evaluate data under uncertainty in a systematic way. A well-constructed test gives a disciplined answer to the question “could the difference I observed be explained by chance?”
But the p-value is only one part of that answer. A sound decision weighs the design, the effect size, the confidence interval, the assumptions and the real-world consequences together. Any statistical result reduced to a single number eventually becomes the justification for a wrong decision.