A/B Testi ve Hipotez Testi Arasındaki İlişki
p-value gerçekte ne söyler, ne söylemez? A/B testinin istatistiksel temellerini kuruyorum: hipotez kurma, etki büyüklüğü, güven aralığı, örneklem hesabı ve istatistiksel anlamlılıkla iş anlamlılığı arasındaki fark.
- İstatistik
- Araçlar
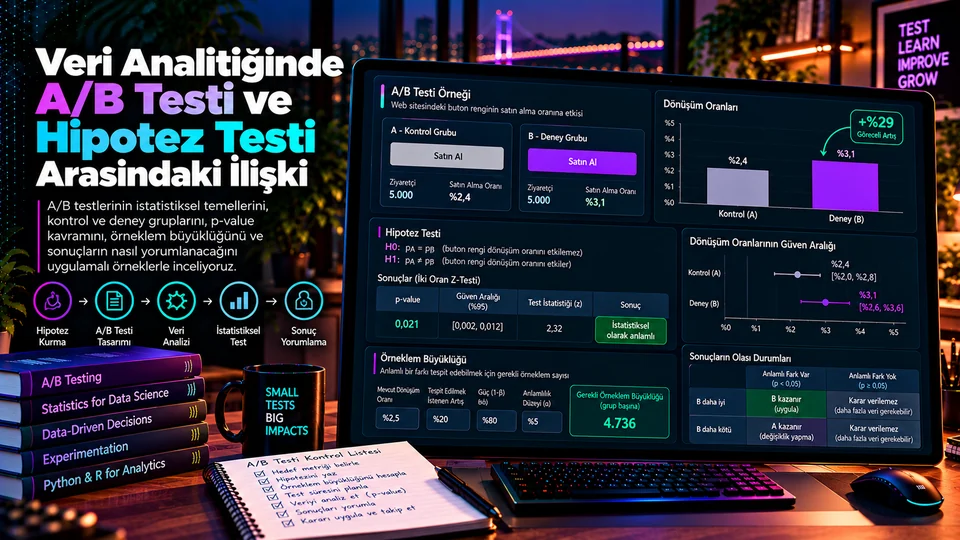
A/B testi ve hipotez testi aynı şey mi?
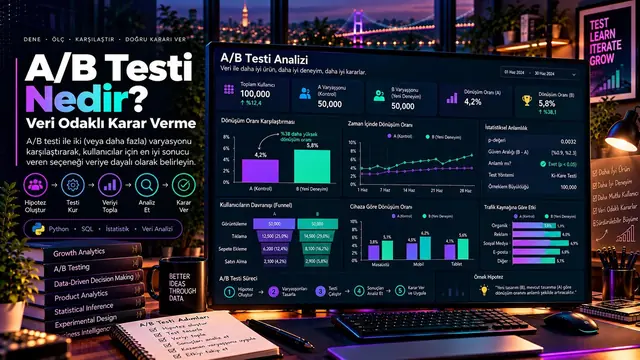
A/B testi bir deney tasarımıdır; hipotez testi ise o deneyden elde edilen veriyi istatistiksel olarak değerlendirmek için kullanılan yöntemlerden biridir. A/B testinde kullanıcılar iki farklı deney koşuluna atanır ve önceden belirlenmiş bir metrik karşılaştırılır.
Örneğin bir e-ticaret sitesi mevcut ürün sayfasını (A: kontrol) yeni tasarımla (B: deney) karşılaştırır. Temel soru, B tasarımının dönüşüm oranında anlamlı ve iş açısından değerli bir değişim yaratıp yaratmadığıdır.
- İş
Sorusu - Hipotezler
- Rastgele
Atama - Veri
Toplama - İstatistiksel
Yorum
Kontrol ve deney grupları
Kontrol grubu
Mevcut deneyimi veya standart uygulamayı görür. Karşılaştırma için referans noktasıdır.
Deney grubu
Test edilmek istenen değişikliği görür. Sonuçları kontrol grubuyla karşılaştırılır.
Gruplar uygun biçimde rastgele atanırsa, bilinen ve bilinmeyen kullanıcı özelliklerinin ortalamada dengelenmesi hedeflenir. Böylece sonuçtaki farkı test edilen değişikliğe bağlamak güvenilir hâle gelir. Rastgele atama yoksa gruplar arasındaki fark tasarımdan değil, kullanıcı profillerinden kaynaklanıyor olabilir.
Deney başlamadan önce tanımlanması gerekenler
- Ana metrik: satın alma dönüşüm oranı veya kullanıcı başına gelir gibi tek bir birincil ölçü.
- Deney birimi: kullanıcı, hesap, oturum ya da mağaza — atamanın yapıldığı birim.
- Hipotez ve yön: fark mı aranıyor, yoksa B'nin A'dan iyi olması mı bekleniyor?
- Örneklem büyüklüğü ve süre: kaç gözlem gerektiği ve deneyin ne zaman biteceği.
- Koruyucu metrikler: iade, hata oranı, sayfa hızı veya şikâyet gibi olası olumsuz etkiler.
H₀ ve H₁: hipotezler nasıl kurulur?
Hipotez testi, veriye bakmadan önce tanımlanan iki iddia arasında değerlendirme yapar.
| Hipotez | Örnek | Anlamı |
|---|---|---|
| H₀ — sıfır hipotezi | pA = pB | Grupların gerçek dönüşüm oranları arasında fark yoktur. |
| H₁ — alternatif hipotez | pA ≠ pB | Grupların gerçek dönüşüm oranları farklıdır. |
İki yönlü test, farkın hangi yönde olacağını önceden sınırlamadan her iki yöndeki değişimi değerlendirir. Tek yönlü test ise yalnızca önceden belirlenmiş bir yöndeki kanıtı sınar. Tek yönlü test, sonucu gördükten sonra p-değerini küçültmek için seçilmemelidir — bu, istatistiksel bir hile olur.
Tip I ve Tip II hata
Tip I hata
Gerçekte fark yokken sıfır hipotezini reddetmek. α = 0,05 sık kullanılan bir eşiktir, evrensel bir zorunluluk değil.
Tip II hata
Gerçek bir fark varken onu tespit edememek. Test gücü yaklaşık 1 − β olarak ifade edilir.
Test gücü, belirli büyüklükteki gerçek bir etkinin tespit edilme olasılığıdır. Gücü artırmak için daha büyük örneklem, daha düşük ölçüm gürültüsü veya daha belirgin bir etki gerekir. Düşük güçlü bir deney yalnızca “bir şey bulamamakla” kalmaz; bulduğu etkiyi de abartma eğilimindedir.
p-value ne anlama gelir?
P-değeri; sıfır hipotezi ve testin varsayımları doğru kabul edildiğinde, gözlenen sonuç kadar veya daha uç bir test istatistiği elde etme olasılığıdır.
p = 0,03 bulmak, sıfır hipotezi altında bu kadar uç bir sonuç görme olasılığının %3 olduğu anlamına gelir. Bu, “H₀'ın doğru olma olasılığı %3” veya “B'nin başarılı olma olasılığı %97” demek değildir. İkisi de en sık yapılan yorum hatasıdır.
Sonucu nasıl yorumlamalı?
- p ≤ α ise, testin varsayımları altında H₀'a karşı istatistiksel kanıt bulunduğu söylenebilir.
- p > α ise H₀ reddedilemez; bu, grupların kesinlikle aynı olduğu anlamına gelmez.
- P-değerini her zaman etki büyüklüğü, güven aralığı, örneklem büyüklüğü ve deney tasarımıyla birlikte raporlayın.
Etki büyüklüğü ve güven aralığı
A/B testinde yalnızca “fark var mı?” değil, “fark ne kadar büyük ve hangi değerler makul?” sorusu da önemlidir. Dönüşüm oranlarında mutlak fark ile göreli artış farklı şeyler anlatır ve raporlarda sık sık birbirine karıştırılır.
Mutlak fark
A: %10, B: %11 ise fark 1 yüzde puandır.
Göreli artış
(%11 − %10) / %10 = %10 göreli artış. Aynı sonuç, çok daha etkileyici duruyor.
Güven aralığı, kullanılan yöntemin uzun dönemli tekrar örnekleme özellikleri altında parametre için bir belirsizlik aralığı verir. Dönüşüm farkı +1 yüzde puan ve %95 güven aralığı +0,2 ile +1,8 yüzde puan ise, sıfır fark bu aralığın dışındadır. Yorum yine de model ve tasarım varsayımlarına bağlıdır.
Karar verirken en küçük anlamlı etkiyi (minimum detectable effect, MDE) deney öncesinde belirlemek yararlıdır. +0,1 yüzde puanlık bir fark istatistiksel olarak ayırt edilebilir olsa bile geliştirme ve bakım maliyetini karşılamayabilir.
Kaç kullanıcıya ihtiyaç var?
Örneklem büyüklüğü; başlangıç dönüşüm oranına, tespit edilmek istenen minimum etkiye, anlamlılık düzeyine ve test gücüne bağlıdır. Bu değerler deney başlamadan önce belirlenmelidir.
| Parametre | Ne ifade eder? | Tipik tercih |
|---|---|---|
| α | Tip I hata için kabul edilen eşik. | Çoğu durumda 0,05. |
| Güç (1 − β) | Belirli bir gerçek etkiyi yakalama olasılığı. | Genellikle %80 veya %90. |
| Başlangıç oranı | Kontrol grubunda beklenen dönüşüm. | Geçmiş veriden tahmin edilir. |
| MDE | İş açısından anlamlı en küçük fark. | İş hedefiyle belirlenir. |
Daha küçük etkileri güvenilir biçimde tespit etmek belirgin biçimde daha büyük örneklem gerektirir. Hesaplama, kullanılacak teste ve varsayımlara göre yapılmalıdır; genel geçer bir “şu kadar kullanıcı yeter” sayısı yoktur.
Python ile basit bir A/B testi
Senaryo: A grubunda 10.000 kullanıcıdan 1.000'i, B grubunda 10.000 kullanıcıdan 1.100'ü satın alma yapıyor — yani %10 ve %11. Aşağıdaki kod iki oran için iki yönlü z-testi uygular. Bağımsız kullanıcılar ve uygun örnekleme varsayımları altında kullanılabilecek klasik bir yaklaşımdır.
from statsmodels.stats.proportion import proportions_ztest

basarili = [1000, 1100]
toplam   = [10000, 10000]

z_istatistigi, p_degeri = proportions_ztest(
    count=basarili,
    nobs=toplam,
    alternative="two-sided"
)

oran_a = basarili[0] / toplam[0]
oran_b = basarili[1] / toplam[1]
mutlak_fark  = oran_b - oran_a
goreli_artis = mutlak_fark / oran_a

print(f"A dönüşüm oranı: {oran_a:.1%}")
print(f"B dönüşüm oranı: {oran_b:.1%}")
print(f"Mutlak fark: {mutlak_fark:.1%}")
print(f"Göreli artış: {goreli_artis:.1%}")
print(f"z: {z_istatistigi:.3f}, p: {p_degeri:.4f}")
Bu örnekte B'nin gözlenen dönüşümü A'dan 1 yüzde puan yüksektir. İki oran z-testi, sıfır hipotezi altında havuzlanmış oranı kullanarak test istatistiğini hesaplar.
Sonucu raporlama
Rapor şunları içermelidir: grup başına kullanıcı sayısı, her grubun dönüşüm oranı, mutlak fark, göreli değişim, p-değeri, fark için güven aralığı ve deneyin önceden belirlenmiş kurallara uyup uymadığı. Karar yalnızca p-değerine dayandırılmamalıdır.
Sık yapılan hatalar ve yanlılık kaynakları
- Erken durdurma: her gün p-değerine bakıp ilk anlamlı sonuçta bitirmek yanlış pozitif riskini büyütür.
- Çoklu karşılaştırma: çok sayıda metrik, segment veya varyant test etmek tesadüfen anlamlı sonuç bulma olasılığını yükseltir. Birincil metriği ve düzeltme stratejisini önceden belirleyin.
- Örneklem oranı uyumsuzluğu (SRM): planlanan atama oranıyla gözlenen oran arasında açıklanamayan fark varsa, sonuçları yorumlamadan önce deney altyapısını araştırın.
- Segmentleri sonradan seçmek: sonucu gördükten sonra ilginç alt gruplar aramak keşif için yararlıdır ama doğrulayıcı kanıt sayılmaz.
- Ölçüm sorunları: dönüşüm olaylarının bir grupta eksik kaydedilmesi tüm sonucu bozar.
- Taşma etkisi: kullanıcıların birbirini etkilediği veya aynı kişinin iki gruba girdiği durumlarda bağımsızlık varsayımı çöker.
İstatistiksel anlamlılık mı, iş anlamlılığı mı?
İstatistiksel anlamlılık, gözlenen verinin sıfır hipoteziyle ne kadar uyumlu olduğuna dair kanıt sağlar. İş anlamlılığı ise değişimin gelir, maliyet, kullanıcı deneyimi veya stratejik hedefler açısından değerini sorgular. İkisi aynı şey değildir ve çoğu zaman aynı yönü göstermez.
| Sonuç | Olası yorum | Önerilen yaklaşım |
|---|---|---|
| Anlamlı, etki yeterince büyük | Değişiklik faydalı olabilir. | Koruyucu metrikleri ve uygulama maliyetini kontrol ederek ilerleyin. |
| Anlamlı, etki çok küçük | Gerçek bir fark olabilir, ticari etkisi sınırlıdır. | Net faydayı ve bakım maliyetini hesaplayın. |
| Anlamlı değil, aralık geniş | Veri kesin karar için yetersiz. | Belirsizliği MDE ile karşılaştırın; gerekiyorsa yeni deney tasarlayın. |
| Anlamlı değil, aralık dar | İş açısından önemli bir etki olasılığı düşük. | Önceden belirlenmiş eşdeğerlik veya non-inferiority çerçevesini değerlendirin. |
“İstatistiksel olarak anlamlı değil” sonucunu “iki tasarım eşit” diye sunmayın. Eşdeğerlik iddiası için önceden belirlenmiş kabul edilebilir fark aralığı ve buna uygun bir test yaklaşımı gerekir. Kanıtın yokluğu, yokluğun kanıtı değildir.
Deney başlamadan önce kontrol listesi
- Ana hipotez ve birincil metrik önceden belirlendi mi?
- Rastgele atama birimi ve kullanıcıların grupta kalma kuralı net mi?
- Örneklem büyüklüğü, α, güç ve MDE gerekçelendirildi mi?
- Deney süresi ve durdurma kuralı önceden tanımlandı mı?
- Takip ve koruyucu metrikler seçildi mi?
- Örneklem oranı uyumsuzluğu ve olay kaydı sorunları kontrol edilecek mi?
- Etki büyüklüğü ve güven aralığı p-değeriyle birlikte raporlanacak mı?
- Çoklu testler ve alt grup analizleri için bir plan var mı?
A/B testi, doğru soruyu doğru deneyle yanıtlamaktır
A/B testi, ürün ve pazarlama kararlarını deneysel kanıtla destekleyen bir yöntemdir. Hipotez testi, kontrol ve deney grupları arasındaki gözlenen farkı istatistiksel belirsizlik içinde yorumlamaya yardımcı olur. Ancak güvenilir bir karar için yalnızca p-değeri yeterli değildir.
İyi bir A/B testi; açık hipotez, rastgele atama, doğru metrik, önceden planlanmış örneklem büyüklüğü, güven aralığı, etki büyüklüğü ve deney kalitesi kontrollerini bir araya getirir. Sonuçlar hem istatistiksel hem de iş bağlamında değerlendirilmelidir.
Are A/B testing and hypothesis testing the same thing?
An A/B test is an experimental design; a hypothesis test is one of the methods used to evaluate the data that experiment produces. In an A/B test, users are assigned to two different conditions and a predefined metric is compared.
An e-commerce site might compare its current product page (A: control) with a new design (B: treatment). The core question is whether design B produces a change in conversion rate that is both statistically meaningful and worth something to the business.
- Business
Question - Hypotheses
- Random
Assignment - Data
Collection - Statistical
Interpretation
Control and treatment groups
Control group
Sees the current experience or standard practice. It is the reference point for comparison.
Treatment group
Sees the change being tested. Its results are compared against the control.
When groups are properly randomised, the aim is for known and unknown user characteristics to balance out on average. That makes it credible to attribute the difference in outcome to the change being tested. Without randomisation, a difference between groups may come from the user profiles rather than the design.
What to define before the experiment starts
- Primary metric: a single main measure, such as purchase conversion rate or revenue per user.
- Unit of experimentation: user, account, session or store — whatever assignment happens on.
- Hypothesis and direction: are you looking for any difference, or specifically for B to beat A?
- Sample size and duration: how many observations are needed and when the experiment ends.
- Guardrail metrics: returns, error rate, page speed or complaints — the possible negative effects.
H₀ and H₁: how are hypotheses set up?
A hypothesis test evaluates two claims defined before looking at the data.
| Hypothesis | Example | Meaning |
|---|---|---|
| H₀ — null hypothesis | pA = pB | There is no difference between the groups' true conversion rates. |
| H₁ — alternative hypothesis | pA ≠ pB | The groups' true conversion rates differ. |
A two-sided test evaluates change in both directions without restricting it in advance. A one-sided test examines evidence only in a predetermined direction. A one-sided test must not be chosen after seeing the result in order to shrink the p-value — that is statistical sleight of hand.
Type I and Type II error
Type I error
Rejecting the null when there is in fact no difference. α = 0.05 is a common threshold, not a universal requirement.
Type II error
Failing to detect a real difference. Statistical power is expressed roughly as 1 − β.
Power is the probability of detecting a true effect of a given size. Raising it requires a larger sample, less measurement noise or a bigger effect. An underpowered experiment does not merely fail to find things; it also tends to exaggerate the effects it does find.
What does a p-value mean?
The p-value is the probability of obtaining a test statistic as extreme as, or more extreme than, the one observed — assuming the null hypothesis and the test's assumptions hold.
Finding p = 0.03 means there is a 3% chance of seeing a result this extreme under the null. It does not mean “there is a 3% chance H₀ is true” or “B has a 97% chance of succeeding”. Both are the most common misreadings.
How to interpret the result
- If p ≤ α, there is statistical evidence against H₀ under the test's assumptions.
- If p > α, H₀ cannot be rejected; that does not mean the groups are definitely identical.
- Always report the p-value alongside effect size, confidence interval, sample size and experimental design.
Effect size and confidence intervals
In an A/B test, “is there a difference?” is not the only question — “how big is it, and which values are plausible?” matters just as much. In conversion rates, absolute difference and relative lift mean different things and are frequently confused in reports.
Absolute difference
If A is 10% and B is 11%, the difference is 1 percentage point.
Relative lift
(11% − 10%) / 10% = a 10% relative lift. The same result, sounding far more impressive.
A confidence interval gives a range of uncertainty for the parameter under the long-run repeated-sampling properties of the method used. If the conversion difference is +1 percentage point with a 95% interval of +0.2 to +1.8 points, zero difference lies outside that range. The interpretation still depends on the model and design assumptions.
It helps to set the minimum detectable effect (MDE) before the experiment. A difference of +0.1 percentage points may be statistically distinguishable and still fail to cover the development and maintenance cost.
How many users do you need?
Sample size depends on the baseline conversion rate, the minimum effect you want to detect, the significance level and the statistical power. These values must be fixed before the experiment starts.
| Parameter | What it represents | Typical choice |
|---|---|---|
| α | Accepted threshold for Type I error. | 0.05 in most cases. |
| Power (1 − β) | Probability of catching a true effect of a given size. | Usually 80% or 90%. |
| Baseline rate | Expected conversion in the control group. | Estimated from historical data. |
| MDE | Smallest difference that matters to the business. | Set from the business goal. |
Detecting smaller effects reliably requires a markedly larger sample. The calculation must follow the test and assumptions you will actually use; there is no universal “this many users is enough” number.
A simple A/B test in Python
The scenario: 1,000 of 10,000 users in group A convert, and 1,100 of 10,000 in group B — 10% and 11%. The code below runs a two-sided z-test for two proportions, a classic approach under assumptions of independent users and appropriate sampling.
from statsmodels.stats.proportion import proportions_ztest

basarili = [1000, 1100]
toplam   = [10000, 10000]

z_istatistigi, p_degeri = proportions_ztest(
    count=basarili,
    nobs=toplam,
    alternative="two-sided"
)

oran_a = basarili[0] / toplam[0]
oran_b = basarili[1] / toplam[1]
mutlak_fark  = oran_b - oran_a
goreli_artis = mutlak_fark / oran_a

print(f"A conversion rate: {oran_a:.1%}")
print(f"B conversion rate: {oran_b:.1%}")
print(f"Absolute difference: {mutlak_fark:.1%}")
print(f"Relative lift: {goreli_artis:.1%}")
print(f"z: {z_istatistigi:.3f}, p: {p_degeri:.4f}")
Here B's observed conversion is one percentage point above A's. The two-proportion z-test computes the statistic using a pooled rate under the null hypothesis.
Reporting the result
A report should contain: users per group, each group's conversion rate, the absolute difference, the relative change, the p-value, a confidence interval for the difference, and whether the experiment followed its predefined rules. The decision should not rest on the p-value alone.
Common mistakes and sources of bias
- Early stopping: checking the p-value daily and ending at the first significant result inflates false positive risk.
- Multiple comparisons: testing many metrics, segments or variants raises the chance of a significant result by luck. Fix the primary metric and a correction strategy in advance.
- Sample ratio mismatch (SRM): if the observed allocation differs from the planned one without explanation, investigate the experiment infrastructure before interpreting anything.
- Picking segments afterwards: finding interesting subgroups after seeing the result is useful for exploration but is not confirmatory evidence.
- Measurement problems: conversion events under-recorded in one group corrupt the whole result.
- Spillover: when users influence each other, or the same person enters both groups, the independence assumption collapses.
Statistical significance or business significance?
Statistical significance provides evidence about how compatible the observed data is with the null hypothesis. Business significance asks what the change is worth in revenue, cost, user experience or strategic terms. They are not the same thing, and they often do not point the same way.
| Outcome | Possible reading | Suggested approach |
|---|---|---|
| Significant, effect large enough | The change may be beneficial. | Proceed after checking guardrail metrics and implementation cost. |
| Significant, effect very small | A real difference, with limited commercial impact. | Compute the net benefit and the maintenance cost. |
| Not significant, wide interval | The data is insufficient for a firm decision. | Compare the uncertainty with the MDE; design a new experiment if needed. |
| Not significant, narrow interval | A business-relevant effect is unlikely. | Consider a predefined equivalence or non-inferiority framework. |
Do not present “not statistically significant” as “the two designs are equal”. A claim of equivalence requires a predefined acceptable range of difference and a test approach suited to it. Absence of evidence is not evidence of absence.
A checklist before the experiment starts
- Are the main hypothesis and the primary metric defined in advance?
- Is the unit of randomisation clear, along with the rule keeping users in their group?
- Are the sample size, α, power and MDE justified?
- Are the duration and the stopping rule defined beforehand?
- Have tracking and guardrail metrics been chosen?
- Will sample ratio mismatch and event-logging issues be checked?
- Will effect size and confidence intervals be reported alongside the p-value?
- Is there a plan for multiple tests and subgroup analyses?
An A/B test answers the right question with the right experiment
A/B testing supports product and marketing decisions with experimental evidence. Hypothesis testing helps interpret the observed difference between control and treatment within statistical uncertainty. But a p-value alone is not enough for a trustworthy decision.
A good A/B test brings together a clear hypothesis, randomisation, the right metric, a pre-planned sample size, confidence intervals, effect size and experiment-quality checks. Results should be assessed in both statistical and business terms.