Python ile Otomatik Veri Analizi
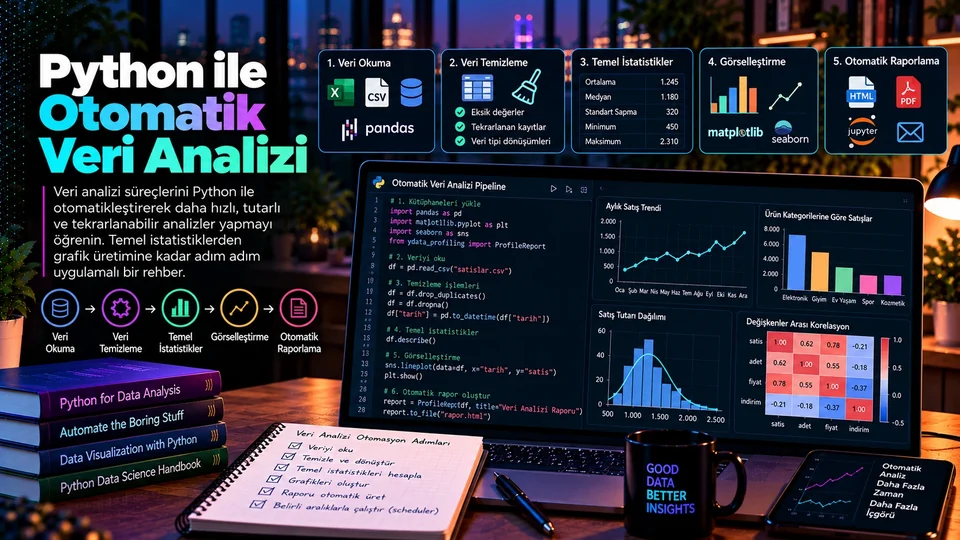
Veriyi yükleyin, kaliteyi ölçün, özetleyin, görselleştirin ve raporu tek bir tekrarlanabilir iş akışıyla dışa aktarın. Her yeni dosyanın aynı ölçütlerle incelendiği bir akış nasıl kurulur, adım adım anlatıyorum.
- Araçlar
Analizi iş akışına dönüştürmek
Otomatik veri analizi; tekrar eden yükleme, kalite kontrolü, özet ve raporlama adımlarını tanımlı ve yeniden çalıştırılabilir hâle getirir. Günlük satış, anket veya kullanım verilerinde ciddi zaman kazandırır. Kazandırmadığı tek şey yorum: bağlamı okumak ve şaşırtıcı bulguları araştırmak yine analistin işidir.
siparis_tarihi, bolge, adet ve birim_fiyat sütunlarını içeren bir CSV. Kod örnekleri bu şemaya göre yazıldı.1. Veriyi yükleyin ve inceleyin
Kodlamayı ve tarih sütunlarını açıkça tanımlayın. Boyutu, örnek satırları ve veri tiplerini daha ilk adımda gözden geçirin.
from pathlib import Path
import pandas as pd

dosya = Path("veri/siparisler.csv")
df = pd.read_csv(dosya, parse_dates=["siparis_tarihi"], encoding="utf-8")
print(df.shape, df.head(), df.dtypes)

beklenen = {"siparis_tarihi", "bolge", "adet", "birim_fiyat"}
eksik = beklenen - set(df.columns)
if eksik:
    raise ValueError(f"Beklenen sütunlar yok: {sorted(eksik)}")
Buradaki şema kontrolü küçük ama kritik: kaynak dosya sessizce değiştiğinde, eksik alanlarla üretilmiş bir raporu haftalar sonra fark etmek yerine betiği ilk satırda durdurur.
2. Veri kalitesini kontrol edin
Eksik alanları, tekrar eden kayıtları, sütun türlerini ve iş kurallarına aykırı değerleri ölçün. Bu adım analizin kendisi değil, analize güvenip güvenemeyeceğinizin cevabıdır.
profil = pd.DataFrame({
    "tur": df.dtypes.astype("string"),
    "eksik_sayi": df.isna().sum(),
    "eksik_yuzde": (df.isna().mean() * 100).round(1),
    "benzersiz": df.nunique(),
})
tekrar = df.duplicated().sum()

print(profil.sort_values("eksik_yuzde", ascending=False))
print(f"Yinelenen satır: {tekrar}")
print(df.describe(include="all").T)3. Eksik değerleri yönetin
Yöntem, sütunun anlamına ve boşluğun nedenine bağlıdır. Eksik bir tarih ile eksik bir serbest metin notu aynı problem değildir.
| Durum | Yaklaşım | Dikkat |
|---|---|---|
| Az sayıda kritik alan eksik | İncele; gerekçeliyse satırı çıkar | Örneklem kaybı |
| Sayısal ölçüm | Medyan veya iş kuralı | Dağılımı daraltır |
| Kategorik alan | “Bilinmiyor” ya da kaynağa dönüş | Eksiklik kendisi bir bilgi olabilir |
| Tarih | Kaynağı düzelt, kararı belgele | Rastgele tarih uydurmayın |
eksik_ozeti = pd.DataFrame({
    "sayi": df.isna().sum(),
    "yuzde": (df.isna().mean() * 100).round(1),
}).query("sayi > 0").sort_values("yuzde", ascending=False)

df["bolge"] = df["bolge"].fillna("Bilinmiyor")
Hangi sütunu neden doldurduğunuzu yazılı olarak saklayın ve ham veriyi asla üzerine yazmayın. Altı ay sonra “bu kolonda neden hiç boş yok?” sorusunu soran kişi büyük ihtimalle siz olacaksınız.
4. Tanımlayıcı istatistikler
Ortalamayı ve standart sapmayı medyan ve çeyreklerle birlikte okuyun. Çarpık dağılımlarda — satış verisi neredeyse her zaman çarpıktır — ortalama tek başına yanıltır.
sayisal = df[["adet", "birim_fiyat"]]
ozet = sayisal.describe().T
ozet["medyan"] = sayisal.median()

df["ciro"] = df["adet"] * df["birim_fiyat"]
print(ozet.round(2), df["ciro"].sum())
Buradaki ciro tanımı bilinçli olarak sade: adet × birim fiyat. Gerçek projede indirim, vergi, iadeler ve para birimi dönüşümü bu formüle girer — ve her biri sayıyı değiştirir. Formülü iş tarafıyla bir kez netleştirip koda yorum olarak yazın.
5. Gruplu analiz
Bölge veya ürün bazında birden çok ölçüyü aynı anda üretin. Toplam ve ortalama farklı soruları yanıtlar: biri hacmi, diğeri tipik sipariş büyüklüğünü anlatır.
bolge = (df.groupby("bolge", dropna=False)
    .agg(siparis=("ciro", "size"),
         toplam_adet=("adet", "sum"),
         toplam_ciro=("ciro", "sum"),
         ort_ciro=("ciro", "mean"))
    .sort_values("toplam_ciro", ascending=False))

aylik = (df.set_index("siparis_tarihi")["ciro"]
    .resample("MS").sum().rename("ciro").reset_index())
dropna=False yazmak önemli: varsayılan davranış eksik bölgeli satırları gruplamadan tamamen düşürür ve toplam ciro sessizce küçülür. resample("MS") ay başlarına göre toplar ve aradaki ayları atlamaz: hiç sipariş olmayan bir ay seriye 0 olarak girer, eksik satır olarak değil. Çoğu zaman istenen davranış budur, ama grafikte “o ay satış olmadı” ile “o ay veri gelmedi” aynı görünür — ikisini ayırmanız gerekiyorsa ay başına kayıt sayısını ayrıca kontrol edin.
6. Grafikleri üretin
Başlık ve eksen adları ölçümün ne olduğunu açıklasın. Görseli kaydedip kapatmak, uzun süren toplu işlerde belleğin şişmesini önler.
import matplotlib.pyplot as plt
import seaborn as sns
from pathlib import Path

sns.set_theme(style="whitegrid", palette="viridis")
fig, ax = plt.subplots(figsize=(8, 4))

sns.barplot(data=bolge.reset_index(), x="bolge", y="toplam_ciro", ax=ax)
ax.set(title="Bölgelere göre ciro", xlabel="Bölge", ylabel="Ciro (TL)")

Path("cikti").mkdir(exist_ok=True)
fig.tight_layout()
fig.savefig("cikti/bolge_cirosu.png", dpi=160)
plt.close(fig)
Birimleri eksen adında belirtin, etiketleri okunaklı tutun ve rengi tek başına bilgi taşıyıcısı olarak kullanmayın. Renk körlüğü bir yana, rapor siyah-beyaz çıktı alındığında grafiğin hâlâ okunabilir olması gerekir.
7. Yeniden kullanılabilir fonksiyonlar
Küçük ve tek amaçlı fonksiyonlar, analizi dosyalar arasında taşımayı kolaylaştırır. Asıl kazanç kod kısalığı değil; aynı hesabın iki yerde iki farklı şekilde yapılmasını engellemesidir.
def sayisal_ozet(veri: pd.DataFrame) -> pd.DataFrame:
    """Sayısal sütunların özetini ve eksik sayısını döndürür."""
    sayilar = veri.select_dtypes(include="number")
    if sayilar.empty:
        raise ValueError("Sayısal sütun yok.")
    sonuc = sayilar.describe().T
    sonuc["eksik"] = sayilar.isna().sum()
    return sonuc.round(2)
Dosya yollarını, sütun adlarını ve eşikleri parametreleştirin; fonksiyonun içine gömmeyin. Beklenmeyen girdide sessizce boş sonuç döndürmek yerine açıklayıcı bir hata verin — yukarıdaki ValueError gibi.
8. Raporu dışa aktarın
Tabloları ayrı Excel sayfalarına, grafikleri PNG dosyalarına yazın. Yanına kaynağı, dönemi, uygulanan filtreleri ve metodoloji notlarını da ekleyin.
cikti = Path("cikti")
cikti.mkdir(parents=True, exist_ok=True)

with pd.ExcelWriter(cikti / "veri_analiz_raporu.xlsx") as yazar:
    profil.to_excel(yazar, sheet_name="Kalite")
    ozet.to_excel(yazar, sheet_name="Istatistik")
    bolge.to_excel(yazar, sheet_name="Bolge")
    aylik.to_excel(yazar, sheet_name="Aylik", index=False)
Dosya adına rapor dönemini ekleyin; rapor.xlsx adında on tane dosya hiçbir işe yaramaz. Betiği tek komutla çalıştırılabilir yapın ve girdi/çıktı yollarını dışarıdan verin.
İş akışı kontrol listesi
- Girdiyi
Doğrula - Yükle ve
Dönüştür - Kaliteyi
Ölç - Kararları
Belgele - Analiz
Et - Raporla
- Gözden
Geçir
Ham veriyi koru
Hiçbir temizleme adımı kaynak dosyanın üzerine yazmasın; tüm dönüşümler kopya üzerinde ilerlesin.
Kaliteyi raporla
Eksik ve tekrar bulgularını gizlemeyin; raporun ilk sayfası kalite profili olsun.
İş kurallarını görünür kıl
Ciro, iade ve indirim tanımları kodda yorum olarak değil, raporda da yazılı olsun.
Birimleri belirt
TL mi, adet mi, yüzde mi? Eksen ve sütun adlarında birimi açıkça yazın.
Çıktıları adlandır
Dosya adında dönem ve kapsam geçsin; tarihsiz çıktılar bir hafta sonra birbirine karışır.
Şaşırtıcıyı araştır
Beklenmedik bir sıçrama önce veri hatası olarak değerlendirilmeli, sonra bulgu olarak sunulmalı.
Küçük başlayın, sonra sağlamlaştırın
Önce yalnızca dosyayı okuyup kalite profilini ve kısa bir özet raporu üreten küçük bir akış kurun. Çalıştığından emin olduktan sonra tekrarlanan adımları fonksiyonlara taşıyın, şema ve eşik kontrollerini güçlendirin.
Bu sırayla ilerlemenin nedeni basit: baştan mükemmel bir otomasyon kurmaya çalışmak, çoğu zaman hiç bitmeyen bir betikle sonuçlanır. Çalışan küçük bir akış ise ilk günden zaman kazandırmaya başlar ve her yeni dosya aynı ölçütlerle, daha az manuel emekle incelenir.
Turning analysis into a workflow
Automated data analysis makes the repeating steps — loading, quality checks, summaries and reporting — defined and re-runnable. On daily sales, survey or usage data it saves serious time. The one thing it does not save is interpretation: reading the context and investigating surprising findings is still the analyst's job.
siparis_tarihi (order date), bolge (region), adet (quantity) and birim_fiyat (unit price). The code follows that schema.1. Load the data and look at it
Declare the encoding and the date columns explicitly. Review the shape, a few sample rows and the dtypes at the very first step.
from pathlib import Path
import pandas as pd

dosya = Path("veri/siparisler.csv")
df = pd.read_csv(dosya, parse_dates=["siparis_tarihi"], encoding="utf-8")
print(df.shape, df.head(), df.dtypes)

beklenen = {"siparis_tarihi", "bolge", "adet", "birim_fiyat"}
eksik = beklenen - set(df.columns)
if eksik:
    raise ValueError(f"Missing expected columns: {sorted(eksik)}")
That schema check is small but critical: when the source file changes quietly, it stops the script on the first line instead of letting you discover weeks later that a report was built on missing fields.
2. Check data quality
Measure missing fields, duplicate records, column types and values that break the business rules. This step is not the analysis itself — it is the answer to whether you can trust the analysis.
profil = pd.DataFrame({
    "tur": df.dtypes.astype("string"),
    "eksik_sayi": df.isna().sum(),
    "eksik_yuzde": (df.isna().mean() * 100).round(1),
    "benzersiz": df.nunique(),
})
tekrar = df.duplicated().sum()

print(profil.sort_values("eksik_yuzde", ascending=False))
print(f"Duplicate rows: {tekrar}")
print(df.describe(include="all").T)3. Handle missing values
The method depends on what the column means and why the gap is there. A missing date and a missing free-text note are not the same problem.
| Situation | Approach | Watch out for |
|---|---|---|
| A few critical fields missing | Inspect; drop the row if justified | Loss of sample |
| Numeric measurement | Median or a business rule | Narrows the distribution |
| Categorical field | “Unknown”, or go back to the source | The gap itself may be information |
| Date | Fix the source, document the decision | Never invent a date |
eksik_ozeti = pd.DataFrame({
    "sayi": df.isna().sum(),
    "yuzde": (df.isna().mean() * 100).round(1),
}).query("sayi > 0").sort_values("yuzde", ascending=False)

df["bolge"] = df["bolge"].fillna("Unknown")
Keep a written record of which column you filled and why, and never overwrite the raw data. The person asking “why are there no blanks in this column?” six months from now will most likely be you.
4. Descriptive statistics
Read the mean and standard deviation together with the median and quartiles. On skewed distributions — and sales data is almost always skewed — the mean alone misleads.
sayisal = df[["adet", "birim_fiyat"]]
ozet = sayisal.describe().T
ozet["medyan"] = sayisal.median()

df["ciro"] = df["adet"] * df["birim_fiyat"]
print(ozet.round(2), df["ciro"].sum())
The revenue definition here is deliberately plain: quantity × unit price. In a real project, discounts, tax, returns and currency conversion all enter that formula — and each one changes the number. Settle the definition with the business side once, and write it into the code as a comment.
5. Grouped analysis
Produce several measures at once by region or product. Totals and averages answer different questions: one describes volume, the other the typical order size.
bolge = (df.groupby("bolge", dropna=False)
    .agg(siparis=("ciro", "size"),
         toplam_adet=("adet", "sum"),
         toplam_ciro=("ciro", "sum"),
         ort_ciro=("ciro", "mean"))
    .sort_values("toplam_ciro", ascending=False))

aylik = (df.set_index("siparis_tarihi")["ciro"]
    .resample("MS").sum().rename("ciro").reset_index())
Writing dropna=False matters: the default drops rows with a missing region from the grouping entirely, and the total revenue quietly shrinks. resample("MS") aggregates by month start and does not skip the months in between: a month with no orders enters the series as 0, not as a missing row. That is usually what you want, but on a chart “no sales that month” and “no data that month” look identical — if you need to tell them apart, check the record count per month separately.
6. Produce the charts
Let the title and axis labels explain what is being measured. Saving and closing the figure keeps memory under control in long batch jobs.
import matplotlib.pyplot as plt
import seaborn as sns
from pathlib import Path

sns.set_theme(style="whitegrid", palette="viridis")
fig, ax = plt.subplots(figsize=(8, 4))

sns.barplot(data=bolge.reset_index(), x="bolge", y="toplam_ciro", ax=ax)
ax.set(title="Revenue by region", xlabel="Region", ylabel="Revenue (TRY)")

Path("cikti").mkdir(exist_ok=True)
fig.tight_layout()
fig.savefig("cikti/bolge_cirosu.png", dpi=160)
plt.close(fig)
Put the unit in the axis label, keep labels legible, and never let colour alone carry the information. Colour blindness aside, the chart still has to be readable when the report is printed in black and white.
7. Reusable functions
Small, single-purpose functions make it easy to move the analysis between files. The real gain is not shorter code; it is preventing the same calculation from being done two different ways in two places.
def sayisal_ozet(veri: pd.DataFrame) -> pd.DataFrame:
    """Return a summary of the numeric columns plus missing counts."""
    sayilar = veri.select_dtypes(include="number")
    if sayilar.empty:
        raise ValueError("No numeric columns.")
    sonuc = sayilar.describe().T
    sonuc["eksik"] = sayilar.isna().sum()
    return sonuc.round(2)
Parameterise file paths, column names and thresholds instead of burying them inside the function. On unexpected input, raise an explanatory error rather than silently returning an empty result — like the ValueError above.
8. Export the report
Write tables to separate Excel sheets and charts to PNG files. Alongside them, record the source, the period, the filters applied and the methodology notes.
cikti = Path("cikti")
cikti.mkdir(parents=True, exist_ok=True)

with pd.ExcelWriter(cikti / "veri_analiz_raporu.xlsx") as yazar:
    profil.to_excel(yazar, sheet_name="Kalite")
    ozet.to_excel(yazar, sheet_name="Istatistik")
    bolge.to_excel(yazar, sheet_name="Bolge")
    aylik.to_excel(yazar, sheet_name="Aylik", index=False)
Put the reporting period in the file name; ten files all called rapor.xlsx help nobody. Make the script runnable with a single command and pass the input and output paths in from outside.
A workflow checklist
- Validate
Input - Load &
Convert - Measure
Quality - Document
Decisions - Analyse
- Report
- Review
Protect the raw data
No cleaning step should overwrite the source file; every transformation works on a copy.
Report the quality
Do not hide missing-value and duplicate findings; make the quality profile the report's first sheet.
Make rules visible
Definitions of revenue, returns and discounts belong in the report, not just in a code comment.
State the units
Currency, count or percentage? Write the unit into axis and column names explicitly.
Name the outputs
Include the period and scope in file names; undated outputs blur together within a week.
Chase the surprising
An unexpected jump should be treated as a data error first and presented as a finding second.
Start small, then harden it
Begin with a small flow that only reads the file and produces a quality profile and a short summary report. Once you are confident it works, move the repeating steps into functions and strengthen the schema and threshold checks.
The reason for that order is simple: trying to build a perfect automation from the start usually ends in a script that is never finished. A small working flow starts saving time on day one, and from then on every new file is examined by the same criteria with less manual effort.